TAAI 2026 Program at a Glance


All times are Asia/Taipei (UTC+8).

TAAI 2026 Day 1

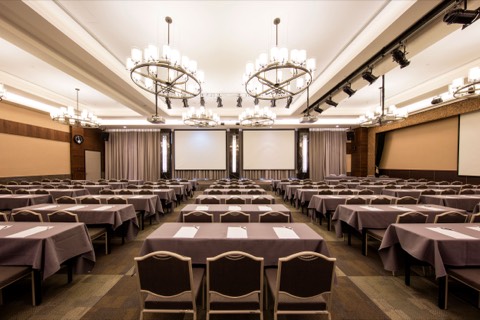
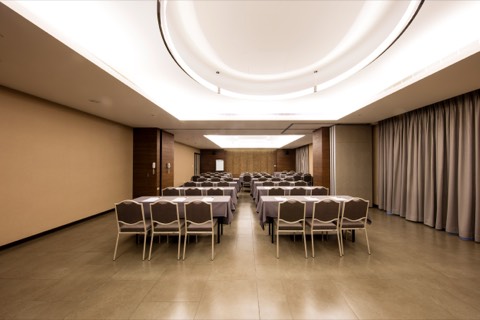
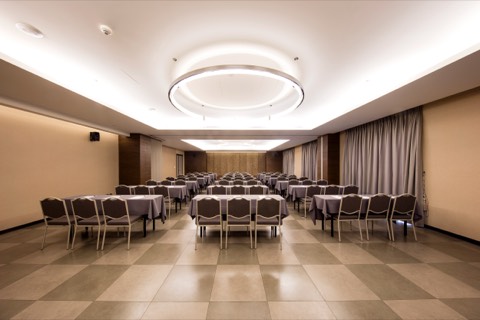
Friday, November 20, 2026 (Venue: The Great Roots Forestry Spa Resort (external site, opens in a new tab))

Scroll horizontally to view all rooms.

Day 1 conference timetable by time and room
Time Plenary Hall5F Lishan Hall (external site, opens in a new tab) Room A2F Lijing Hall A (external site, opens in a new tab) Room B2F Lijing Hall B (external site, opens in a new tab) Room C2F Liquan Hall C1 (external site, opens in a new tab) Room D7F Summit Hall (external site, opens in a new tab) Poster Area2F Liquan Hall exhibition area (external site, opens in a new tab)
08:00-17:00 Registration[5F Lishan Hall open courtyard (external site, opens in a new tab)]
09:20-09:30 Opening CeremonyWelcome remarks: Dalton Lin (President, National Taipei University); Richard Tzong-Han Tsai (President of TAAI and General Chair)
09:30-10:20 Keynote Speech IBeyond Words: Riemannian Geometry for Next-Generation Graph Foundation ModelsProf. Philip S. Yu · University of Illinois Chicago, USAChair: Chih-Hua Tai
10:20-10:40 Coffee Break[5F Lishan Hall exhibition area (external site, opens in a new tab)]
10:40-12:00 Industrial Track 1Chair: Ming-Shun Tsai International Oral Session 1Chair: Chien-Chang Chen Domestic Oral Session 1Chair: Ying-Jia Lin AI CUPFrom AI Competitions to Cross-Domain Innovation and Talent DevelopmentChair: Shih-Hung Wu NSTC ICD MCAEPOral PresentationsChair: Chia-Hui Chang Poster Session 1(International)Chairs: Yung-Chun Chang, Hung-Hsuan Chen
12:00-13:00 Lunch Break[5F Lishan Hall exhibition area (external site, opens in a new tab)] TAAI General Assembly & Board MeetingAssembly first, then Board Meeting Lunch Break
13:00-14:20 Industrial Track 2Chair: Chien-Ping Chung International Oral Session 2Chair: Yi-Zeng Hsieh Domestic Oral Session 2Chair: Meng-Luen Wu Cross-Domain AI Sustainable InnovationSession 1Chair: Min-Yuh Day NSTC ICDProgram Briefing & Planning ReportChair: Chia-Hui Chang Poster Session 2(Domestic)Chair: Jing-Tian Sung
14:20-14:40 Coffee Break[5F Lishan Hall exhibition area (external site, opens in a new tab)]
14:40-16:00 Agentic AI Tutorial 1Agentic AI Deployment in the Enterprise: Code Runs the Workflow, LLMs Provide JudgmentEthan Yin-Hao Tsui · HaoAI Future Technology International Oral Session 3Chair: Shih-Chieh Tang Domestic Oral Session 3Chair: Tz-Heng Hsu Cross-Domain AI Sustainable InnovationSession 2Chair: Sherry Chia-Ying Chan TAAI Thesis Award PresentationsChair: Chia-Ru Chung Poster Session 3(International)Chair: Ching-Ting Tu
16:10-17:00 Keynote Speech IINeural Speech Enhancement and Assessment and Their Applications in Assistive Oral Communication TechnologiesProf. Yu Tsao · Academia Sinica, TaiwanChair: Hsin-Min Wang
17:00-17:50 International Panel DiscussionAdaptive AI in the Real World: Challenges, Opportunities, and Future DirectionsModerator: Ling-Jyh Chen
18:00-20:00 Welcome BanquetPaper awards announced[1F Lichi Hall (麗池廳)]
TAAI 2026 Day 2

Saturday, November 21, 2026 (Venue: The Great Roots Forestry Spa Resort (external site, opens in a new tab))

Scroll horizontally to view all rooms.

Day 2 conference timetable by time and room
Time Plenary Hall5F Lishan Hall (external site, opens in a new tab) Room A2F Lijing Hall A (external site, opens in a new tab) Room B2F Lijing Hall B (external site, opens in a new tab) Room C2F Liquan Hall C1 (external site, opens in a new tab) Room D7F Summit Hall (external site, opens in a new tab) Poster Area2F Liquan Hall exhibition area (external site, opens in a new tab)
08:00-17:00 Registration[5F Lishan Hall open courtyard (external site, opens in a new tab)]
09:00-09:50 Keynote Speech IIIAI-Driven Network Traffic Analysis for Anomaly Detection and CybersecurityProf. Ljiljana Trajkovic · Simon Fraser University, CanadaChair: Chan-Yun Yang
09:50-10:10 Coffee Break[5F Lishan Hall exhibition area (external site, opens in a new tab)]
10:10-11:00 Young Woman Star Session10:10-12:00Chair: Min-Chun Hu International Oral Session 4Chair: Jian-Xing Li Domestic Oral Session 4Chair: Rong-Ming Chen Cross-Domain AI Sustainable InnovationSession 3
10:10-12:00
Chair: Chih-Chien Wang
Agentic AI Session 1 Poster Session 4(Domestic)Chairs: Ling-Yen Pan, I-Hsien Ting +
NSTC Intelligent Computing Discipline Session 1[5F Lishan Hall exhibition area (external site, opens in a new tab)]
11:10-12:00 International Oral Session 5Chair: Wen-Hung Liao Domestic Oral Session 5Chair: Minghsiang Su Agentic AI Session 2 Poster Session 5(International)Chair: Te-Chuan Chiu +
NSTC Intelligent Computing Discipline Session 2[5F Lishan Hall exhibition area (external site, opens in a new tab)]
12:00-13:00 Luncheon[1F Lichi Hall (麗池廳)]
13:00-14:20 Agentic AI Tutorial 2From Modern Poetry to Seamless AI Cinema: Storyboarding and Camera Movement TechniquesProf. Hao-Chiang Koong Lin · National University of Tainan International Oral Session 6Chair: Kuo-Chan Huang Domestic Oral Session 6Chair: Shing-Tai Pan High School Oral Session 1: Long PapersChair: Jen-Wei Huang NAPAI Agentic AI Innovation Competition for Campus ApplicationsSession 1Chair: Chia-Hui Chang Poster Session 6(Domestic)Chairs: Huai-Sheng Huang, Chuei-Huei Kung
14:20-14:40 Coffee Break[5F Lishan Hall exhibition area (external site, opens in a new tab)]
14:40-15:30 Physical AI TutorialImitation Learning with Diffusion Models for Intelligent Embodied AgentsProf. Shao-Hua Sun · National Taiwan University International Oral Session 7Chair: Chuang-Chieh Lin Domestic Oral Session 7Chair: Mao-Hsiu Hsu High School Oral Session 2: Short PapersChair: Jen-Wei Huang NAPAI Agentic AI Innovation Competition for Campus ApplicationsSession 2
14:40-16:30
Chair: Chia-Hui Chang
Poster Session 7(Domestic)Chairs: Ya-Tang Yang, Min-Te Sun
15:40-16:30 Keynote Speech IVGetting to Know You: Long- and Short-Term Adaptation in Dialogue SystemsProf. Kazunori Komatani · The University of Osaka, JapanChair: Yun-Nung Chen No session
16:30-17:00 Closing Ceremony & AwardsPresentation awards

* The papers in each session are listed under Paper Sessions.

Handbook

Conference Handbook

The TAAI 2026 Conference Handbook (PDF) includes the program at a glance, keynote abstracts, paper sessions with paper and author indexes, venue and shuttle information, the organizing committee, and our sponsors and partners.

TAAI 2026 Conference Handbook English edition (PDF, 5.6 MB, 39 pages; opens in a new tab) TAAI 2026 大會手冊中文版 (PDF,6.0 MB,38 頁;於新分頁開啟)

PDF, 5.6 MB (English, 39 pages) · 6.0 MB (中文, 38 頁)

Keynotes

Keynote Speeches

All keynote speeches, the International Panel, the Agentic AI Tutorials 1 and 2, the Young Woman Star Session and the Physical AI Tutorial take place in the Plenary Hall (5F Lishan Hall). Times are Asia/Taipei (UTC+8).

Portrait of Prof. Philip S. Yu

TAAI 2026 Keynote Speech I · Day 1, Fri, Nov 20, 2026 · –

Beyond Words: Riemannian Geometry for Next-Generation Graph Foundation Models

Prof. Philip S. Yu

UIC Distinguished Professor and Wexler Chair in Information Technology, Department of Computer Science, University of Illinois Chicago · ACM / IEEE / AAAS Fellow

Session chair: Prof. Chih-Hua Tai (National Taipei University)

Abstract

Graph Foundation Models (GFMs) are poised to transform graph learning, yet substantial debate remains over how to construct a general-purpose GFM analogous to Large Language Models (LLMs). Traditional Graph Neural Networks (GNNs) struggle with memory retention, principled interpretability, and multi-domain adaptation, while graph serialization limits the direct application of LLMs, as linear tokens fail to capture the rich structural complexity of graphs. In contrast, Riemannian geometry provides a natural, mathematically principled framework for modeling graph structures, offering compatibility with semantic graph learning and LLM integration. In this talk, we argue that for graphs, geometry speaks louder than words. We introduce Riemannian Graph Foundations, which prioritize intrinsic graph geometry and endow models with endogenous capabilities for structural inference and generation, moving beyond simple representation-space transformations. Recent results on building a graph foundation model within Riemannian geometric space will be presented, highlighting how this approach lays the groundwork for next-generation graph intelligence.

Biography

Dr. Philip S. Yu is a Fellow of the ACM, IEEE, and AAAS. Dr. Yu received the ACM SIGKDD 2016 Innovation Award for his influential research and scientific contributions to mining, fusion, and anonymization of big data; the IEEE Computer Society 2013 Technical Achievement Award for “pioneering and fundamentally innovative contributions to the scalable indexing, querying, searching, mining, and anonymization of big data”; and the Research Contributions Award from ICDM in 2003 for his pioneering work in data mining. He has published over 2,000 refereed conference and journal papers, which have been cited more than 278,000 times, with an H-index of 223. He has also applied for more than 300 patents. Dr. Yu served as Editor-in-Chief of ACM TKDD (2011–2017) and IEEE TKDE (2001–2004).
Portrait of Prof. Yu Tsao

TAAI 2026 Keynote Speech II · Day 1, Fri, Nov 20, 2026 · –

Neural Speech Enhancement and Assessment and Their Applications in Assistive Oral Communication Technologies

Prof. Yu Tsao

Research Fellow, Academia Sinica, Taiwan

Session chair: Prof. Hsin-Min Wang (Research Fellow, Academia Sinica)

Abstract

This presentation is divided into three parts. Firstly, we will discuss our recent advancements in neural speech enhancement (SE), a critical element in various speech-related applications. The primary objective of SE is to enhance speech signals by mitigating distortions caused by additive and convoluted noises, thereby improving human-human and human-machine communication efficacy. We'll delve into the system architecture and fundamental theories behind neural SE approaches, as well as explore important directions aimed at achieving better performance. Moving on to the second part, we will focus on our recent progress in neural speech assessment (SA), which aims to effectively evaluate the quality and intelligibility of spoken audio—a crucial aspect in numerous speech-related applications. Traditionally, the evaluation process often relies on listening tests involving human participants, which can be both resource-intensive and impractical due to the need for a large number of listeners. To address this challenge, neural SA metrics have garnered notable attention. We will discuss the fundamental systems of neural SA, highlight several factors influencing performance, and explore emerging trends in this domain. Finally, we will present some applications of neural SE and SA in assistive oral communication technologies. These applications include impaired speech transformation and noise reduction for assistive hearing and speaking devices. Through these discussions, our aim is to illustrate the potential impact of neural-based approaches in improving communication accessibility for individuals with oral communication disorders.

Biography

Yu Tsao (Senior Member, IEEE) received the B.S. and M.S. degrees in Electrical Engineering from National Taiwan University, Taipei, Taiwan, in 1999 and 2001, respectively, and the Ph.D. degree in Electrical and Computer Engineering from the Georgia Institute of Technology, Atlanta, GA, USA, in 2008. From 2009 to 2011, he was a Researcher at the National Institute of Information and Communications Technology (NICT), Tokyo, Japan, where he conducted research and product development in multilingual speech-to-speech translation systems, focusing on automatic speech recognition. He is currently a Research Fellow (Professor) and the Deputy Director at the Research Center for Information Technology Innovation, Academia Sinica, Taipei, Taiwan. He also holds a joint appointment as a Professor in the Department of Electrical Engineering at Chung Yuan Christian University, Taoyuan, Taiwan. His research interests include assistive oral communication technologies, audio coding, and bio-signal processing. He serves as an Associate Editor for IEEE Transactions on Consumer Electronics and IEEE Signal Processing Letters. He received the Outstanding Research Award from Taiwan’s National Science and Technology Council (NSTC), the 2025 IEEE Chester W. Sall Memorial Award, and served as the corresponding author of a paper that won the 2021 IEEE Signal Processing Society Young Author Best Paper Award.

Portrait of Prof. Ljiljana Trajkovic

TAAI 2026 Keynote Speech III · Day 2, Sat, Nov 21, 2026 · –

AI-Driven Network Traffic Analysis for Anomaly Detection and Cybersecurity

Prof. Ljiljana Trajkovic

Professor, Simon Fraser University, Canada · IEEE Fellow

Session chair: Prof. Chan-Yun Yang (Dean, College of Electrical Engineering and Computer Science, National Taipei University)

Abstract

Collection and analysis of data from deployed networks is essential for understanding communication networks. Hence, data mining and statistical analysis of network data have been employed to determine traffic loads, analyze patterns of users' behavior, predict future network traffic, and detect traffic anomalies. The Internet has historically been prone to failures and attacks that significantly degrade its performance, affect the Internet connectivity, and cause routing disconnections. Frequent cases of various cyber threats have been encountered over the years and, hence, detection of anomalous behavior is a topic of great interest in cybersecurity. In described case studies, traffic traces collected by various collection sites are used to classify network anomalies. Various anomaly and intrusion detection approaches based on machine learning have been employed to analyze collected data. Deep learning, broad learning, gradient boosted decision trees, and reservoir computing algorithms were used to develop models based on collected datasets that contain Internet worms, viruses, power outages, ransomware events, router misconfigurations, Internet Protocol hijacks, and infrastructure failures in times of conflict. The reported results indicate that while performance of machine learning models greatly depends on the used datasets, they are viable tools for detecting the Internet anomalies.

Biography

Ljiljana Trajkovic received the Dipl. Ing. degree from University of Pristina, Yugoslavia, the M.Sc. degrees in electrical engineering and computer engineering from Syracuse University, Syracuse, NY, and the Ph.D. degree in electrical engineering from University of California at Los Angeles. She is currently a professor in the School of Engineering Science, Simon Fraser University, Burnaby, British Columbia, Canada. Her research interests include communication networks and dynamical systems. Dr. Trajkovic served as IEEE Division X Delegate/Director, President of the IEEE Systems, Man, and Cybernetics Society, and President of the IEEE Circuits and Systems Society. She serves as Editor-in-Chief of the IEEE Transactions on Human-Machine Systems. She is a Distinguished Lecturer of the IEEE Systems, Man, and Cybernetics Society and was a Distinguished Lecturer of the IEEE Circuits and System Society. She is a Fellow of the IEEE.

Portrait of Prof. Kazunori Komatani

TAAI 2026 Keynote Speech IV · Day 2, Sat, Nov 21, 2026 · –

Getting to Know You: Long- and Short-Term Adaptation in Dialogue Systems

Prof. Kazunori Komatani

Professor, SANKEN, The University of Osaka, Japan

Session chair: Prof. Yun-Nung Chen (National Taiwan University)

Abstract

Large language models have made dialogue systems capable of generating fluent responses. However, being good with words is not the same as understanding the person one is interacting with. A dialogue agent should adapt not just to any user, but to the particular person it is talking to, whose knowledge, experiences, and feelings differ from those of others. In this talk, I will discuss our research on user-adaptive spoken dialogue systems from two complementary perspectives. The first is acquiring knowledge through interaction, particularly learning unfamiliar words by deciding when, what, and how to ask users. The second is understanding users' current states through multimodal sentiment estimation, using information from speech, facial expressions, and physiological signals. I will also discuss how these research topics relate to recent developments in agentic AI, particularly from the perspectives of state representation and action selection.

Biography

Kazunori Komatani is a Professor at SANKEN, the University of Osaka, Japan. He received his Doctor of Informatics degree from Kyoto University in 2002. He was an Assistant Professor at Kyoto University from 2002 to 2010 and an Associate Professor at Nagoya University from 2010 to 2014. He was also a Visiting Scientist at Carnegie Mellon University from 2008 to 2009. He joined SANKEN as a Professor in 2014. His research interests include spoken dialogue systems, dialogue management, user adaptation, and multimodal sentiment analysis.

TAAI 2026 International Panel · Day 1, Fri, Nov 20, 2026 · – · Plenary Hall (5F Lishan Hall)

Adaptive AI in the Real World: Challenges, Opportunities, and Future Directions

Moderator

Prof. Ling-Jyh Chen, Research Fellow, Institute of Information Science, Academia Sinica, Taiwan

Panelists

TAAI 2026 Agentic AI Tutorial 1 · Day 1, Fri, Nov 20, 2026 · – · Plenary Hall (5F Lishan Hall)

Agentic AI Deployment in the Enterprise: Code Runs the Workflow, LLMs Provide Judgment

Ethan Yin-Hao Tsui

Founder, HaoAI Future Technology Co., Ltd., Taiwan

TAAI 2026 Young Woman Star Session · Day 2, Sat, Nov 21, 2026 · – · Plenary Hall (5F Lishan Hall)

Young Woman Star Session

Moderator

Prof. Min-Chun Hu, Professor, Department of Computer Science, National Tsing Hua University, Taiwan

Session convener

Prof. Lun-Wei Ku, Research Fellow, Institute of Information Science, Academia Sinica, Taiwan

Speakers

  • Dr. Yun-Hsuan Lien, Academia Sinica, Taiwan: Adaptive and Reliable Reinforcement Learning
  • Prof. Meng-Fen Chiang, National Yang Ming Chiao Tung University, Taiwan: From Facts to Trust: Structured Knowledge for Reliable LLM Reasoning
  • Prof. Woan-Shiuan Chien, National Yang Ming Chiao Tung University, Taiwan: Beyond Emotion Recognition: Toward Inclusive and Trustworthy Affective AI

TAAI 2026 Young Woman Star Session · Day 2, Sat, Nov 21, 2026 · – · Plenary Hall (5F Lishan Hall)

Adaptive and Reliable Reinforcement Learning

Dr. Yun-Hsuan Lien

Assistant Research Fellow, Research Center for Information Technology Innovation (CITI), Academia Sinica, Taiwan

Abstract

Reinforcement learning (RL) has achieved remarkable success in games, robotics, and foundation models, demonstrating the ability to learn increasingly complex behaviors through interaction. However, deploying RL in real-world environments remains a fundamental challenge. Intelligent systems must continuously adapt to changing tasks, users, and environments while operating under uncertainty, limited data, and stringent safety requirements. Future AI systems therefore need to be not only adaptive, but also reliable. This talk presents a unified perspective on Adaptive and Reliable Reinforcement Learning for building trustworthy embodied intelligence. Recent advances in offline reinforcement learning enable policy learning from previously collected data without requiring costly or unsafe online exploration. Adaptive policy optimization further improves robustness by dynamically balancing performance and conservativeness under uncertainty, while constrained reinforcement learning enables rapid adaptation to changing safety requirements without expensive retraining. Building upon these foundations, reliable perception, multimodal interaction, and human feedback provide the basis for reinforcement learning agents that can collaborate effectively with people in dynamic environments. These capabilities naturally extend to human-centered embodied intelligence, where robots continuously co-adapt with users, personalize their behavior through long-term interaction, and make reliable decisions that balance task performance, safety, and human values. By integrating adaptive optimization, trustworthy decision making, and human-centered learning within a unified framework, this talk outlines a roadmap toward the next generation of embodied AI systems capable of lifelong adaptation, reliable autonomy, and safe collaboration with humans.

Biography

Yun-Hsuan Lien is an Assistant Research Fellow at the Research Center for Information Technology Innovation (CITI), Academia Sinica, specializing in reinforcement learning. Her work focuses on developing theoretical RL algorithms and applying them to dynamic, real-world environments. She is committed to reducing the “reality gap” by improving the robustness of RL models when leveraging simulators or pre-collected data, thereby overcoming the limitations of direct environmental interaction.

TAAI 2026 Young Woman Star Session · Day 2, Sat, Nov 21, 2026 · – · Plenary Hall (5F Lishan Hall)

From Facts to Trust: Structured Knowledge for Reliable LLM Reasoning

Prof. Meng-Fen Chiang

Assistant Professor, Department of Electronics and Electrical Engineering, National Yang Ming Chiao Tung University, Taiwan

Abstract

Large language models produce fluent answers, but fluency is not reliability. In practice, real-world facts often involve multiple entities and conditions, knowledge changes over time, and sources can disagree. Systems that flatten or ignore this structure tend to hallucinate or silently pick one side. This talk presents three steps toward trustworthy LLM reasoning grounded in structured knowledge. First, HyperRAG represents n-ary facts as hypergraphs so that retrieval preserves the relationships among entities and qualifiers. Second, we show how disentangling reasoning logic helps models resolve explicit knowledge conflicts instead of guessing. Third, SiGHT uses graph structure to detect hallucinated claims in domain-specific settings without manual labels. I will close with open challenges in keeping retrieval, reasoning, and evidence aligned as knowledge evolves.

Biography

Meng-Fen Chiang is an Assistant Professor in the Department of Electronics and Electrical Engineering at National Yang Ming Chiao Tung University (NYCU), where she leads the Knowledge Computing Lab. Her research focuses on trustworthy multimodal intelligence, including reasoning over knowledge graphs, hallucination and knowledge conflicts in LLMs and MLLMs, and robust multimodal reasoning. Before joining NYCU, she was a Lecturer at The University of Auckland and a Research Scientist at the Living Analytics Research Centre, Singapore Management University, and earlier worked as a senior engineer at Yahoo Taiwan. She received her Ph.D. in Computer Science from National Chiao Tung University under the supervision of Professor Wen-Chih Peng. Her recent work appears in WWW, KDD, ACL, AISTATS, and ACM TIST.

TAAI 2026 Young Woman Star Session · Day 2, Sat, Nov 21, 2026 · – · Plenary Hall (5F Lishan Hall)

Beyond Emotion Recognition: Toward Inclusive and Trustworthy Affective AI

Prof. Woan-Shiuan Chien

Assistant Professor, Department of Electronics and Electrical Engineering, National Yang Ming Chiao Tung University, Taiwan

Abstract

As voice-based AI agents become increasingly integrated into everyday life, understanding human emotions is essential for more natural and meaningful human-AI interactions. While speech emotion recognition has made significant progress, recognizing emotions is only the beginning. Human emotions are inherently subjective and diverse, shaped by individual differences, social contexts, and varying perceptions. In this talk, I will explore the challenges of moving beyond emotion recognition toward inclusive and trustworthy affective AI. Using speech emotion recognition as a case study, I will highlight our research on speaker–rater fairness, group and individual fairness, and the importance of accounting for human variability in affective modeling. Finally, I will discuss future directions in multimodal and context-aware affective interaction, envisioning AI systems that not only recognize emotional signals but also respect individual differences and support more reliable, empathetic human-AI communication.

Biography

Woan-Shiuan Chien is an assistant professor in the Department of Electronics and Electrical Engineering at National Yang Ming Chiao Tung University (NYCU), Taiwan. She received her Ph.D. degree in Electrical Engineering from National Tsing Hua University (NTHU) in 2025, under the supervision of Prof. Chi-Chun Lee. Her research focuses on human-centered AI, affective computing, multimodal signal processing, and trustworthy AI, with particular interests in speech emotion recognition, algorithmic fairness, and human-AI interaction. She was selected for the 2025 Rising Stars Women in Engineering (Asia) program and named a 2025 Tsing Hua Postdoctoral Research Fellow. Her honors include the IEEE Taipei Section Best Doctoral Dissertation Award (2025), IICM Ph.D. Dissertation Merit Award (2025) and NSTC Outstanding Doctoral Students Fellowship (2022–2023).

TAAI 2026 Agentic AI Tutorial 2 · Day 2, Sat, Nov 21, 2026 · – · Plenary Hall (5F Lishan Hall)

From Modern Poetry to Seamless AI Cinema: Storyboarding and Camera Movement Techniques

Prof. Hao-Chiang Koong Lin

Professor, Department of Information and Learning Technology, National University of Tainan, Taiwan

Abstract

How can the imagery of modern poetry become a continuous cinematic journey across diverse scenes? In this talk, Hao-Chiang Koong Lin demonstrates a creative workflow that begins with his own poetry. Poetic lines are transformed into visual prompts to generate key images in Midjourney. Through successive first- and last-frame transitions, these images are animated and connected to create AI films with the visual continuity and narrative rhythm of a single uninterrupted shot. The talk explores the relationships among poetic imagery, composition, scene transitions, and camera movement. Demonstrations include journeys through Tainan, architectural fly-throughs, behind-the-scenes film set visits, post-apocalyptic landscapes, and immersive passages through famous paintings. These examples illustrate how transitions can maintain visual coherence across changing spaces and artistic styles. Lin also introduces twelve-panel storyboards and point-of-view (POV) approaches, including a technique for subtly embedding camera movement instructions within twelve-panel storyboard images. By combining visual composition with textual direction, creators can guide camera trajectories and the pacing of generated footage. Through practical demonstrations and analysis of his work, participants will explore a complete workflow from poetic inspiration and image generation to storyboarding and continuous video assembly, opening up possibilities for artistic expression, place-based storytelling, and educational content creation.

Biography

Prof. Hao-Chiang Koong Lin holds a Ph.D. in Computer Science from National Tsing Hua University and is a Professor in the Department of Information and Learning Technology at National University of Tainan, where he directs the Digital Art and Interaction Design Laboratory (DDLab). His research spans artificial intelligence, affective computing, the metaverse and extended reality, digital art, and personalized adaptive learning. He is best known for affective tutoring systems that recognize learners' emotions and adjust teaching strategies in real time. Professor Lin has served as Department Chair and Dean of Student Affairs at National University of Tainan, Dean of the College of Innovation and Design at National Taipei University of Business, and Chief Information Officer of Tainan National University of the Arts. He was a Visiting Researcher at the NEC Research Institute in Princeton. He currently chairs the Taiwan Association of Technology Art Education, leads the Ministry of Education's Arts Adaptive Learning platform, and coordinates a regional Ministry of Education metaverse advisory team. He has guest-edited special issues for journals including Sustainability, Frontiers in Artificial Intelligence, and Educational Technology & Society. He has published more than 560 works, led over 170 research and industry projects, and received 29 Best Paper Awards. In 2026, he won the Silver Globee® Award and Best of Category for Artificial Intelligence Technology Education Achievement at the Globee® Awards for Artificial Intelligence, and was ranked among the top 1.3% of scholars worldwide by ScholarGPS. He has also received the NSTC Research Award for Outstanding Talent. He has mentored 27 students who now hold teaching positions, given more than 700 talks, and delivered 41 keynote speeches. Beyond academia, Professor Lin is a published poet and digital artist; one of his poetry collections topped the Books.com.tw bestseller list for contemporary Chinese poetry. He believes that however intelligent AI becomes, education must remain centered on people.

TAAI 2026 Physical AI Tutorial · Day 2, Sat, Nov 21, 2026 · – · Plenary Hall (5F Lishan Hall)

Physical AI: Imitation Learning with Diffusion Models for Intelligent Embodied Agents

Prof. Shao-Hua Sun

Associate Professor, Department of Electrical Engineering, National Taiwan University, Taiwan

Abstract

Imitation learning is a paradigm within reinforcement learning in which agents acquire skills by imitating expert demonstrations rather than optimizing explicit reward functions, and it plays a critical role in applications such as autonomous driving, robotics, and game AI. Despite its practical relevance, existing imitation learning methods often suffer from limited generalization, unstable training dynamics, and strong assumptions regarding the availability and quality of supervision. This talk presents a series of works published at NeurIPS, ICML, and ICLR that leverage diffusion models to address these challenges, improving robustness and generalization, stabilizing adversarial learning, enabling learning without action annotations, extending to video-based decision-making and replanning under partial observability, and supporting effective learning from noisy demonstrations.

Biography

Shao-Hua Sun is an Associate Professor in the Department of Electrical Engineering at National Taiwan University (NTU). He received his Ph.D. from the University of Southern California and his B.S. from NTU. His research spans robot learning, reinforcement learning, program synthesis, generative models, and foundation models. His work has been published in leading venues, including NeurIPS, ICML, CoRL, ICLR, etc. He has organized tutorials and workshops at NeurIPS, ICML, RLC, and CoRL. He has been awarded the MOE Yushan Young Fellow, the NSTC Ta-You Wu Memorial Award, and the IICM K. T. Li Young Researcher Award.

Invited sessions

Invited Sessions

The invited sessions include two NSTC Intelligent Computing Discipline sessions (project reports from the MCAEP program, and a program briefing and planning report, plus the Day 2 project poster exhibition), Industrial Track 1 and the AI CUP session on Day 1, and the Cross-Domain AI Sustainable Innovation sessions, which feature invited talks by experts and scholars in cross-domain AI sustainable innovation. Times are Asia/Taipei (UTC+8). NSTC talk titles are English translations; the original Chinese title follows each one.

MCAEP · Day 1, Fri, Nov 20, 2026 · – · Room D · 7F Summit Hall

NSTC Intelligent Computing Discipline · MCAEP Oral Presentations

Session chair: Prof. Chia-Hui Chang, Department of Computer Science and Information Engineering, National Central University; Convener, Intelligent Computing Discipline, NSTC · 3 research project reports, 25 minutes each

  1. Privacy-Preserving Retrieval-Augmented Generation System on Heterogeneous Platforms for Efficient Data Mining (Year 1 of 3)

    基於異構平台的隱私檢索增強生成系統用於高效資料探勘(1/3)

    Prof. Ming-Syan Chen

    Department of Electrical Engineering, National Taiwan University

  2. Early Anomaly Prediction and Alert System Based on Deep Multimodal Learning (Year 2 of 4)

    基於深度多模態學習之早期異常預測技術及警示系統(2/4)

    Prof. Vincent S. Tseng

    Department of Computer Science, National Yang Ming Chiao Tung University

  3. Forward-Looking Information Technology Research on Multimodal Language Reinforcement Models (Year 3 of 4)

    多模態語言強化模型之訊息科技前瞻技術研究(3/4)

    Prof. Hung-Yu Kao

    National Tsing Hua University

IND 1 · Day 1, Fri, Nov 20, 2026 · – · Plenary Hall · 5F Lishan Hall

Industrial Track 1

Session chair: Ming-Shun Tsai, Taiwan AI Academy

  1. Future Business Models: Innovation Barriers and Business Resilience in the AI-Driven Era

    Shih-Chieh Huang

    Director, Membership Data Innovation and Research Department, FamilyMart Taiwan

    Abstract

    As artificial intelligence and data technologies advance rapidly, the key to competitive advantage is shifting from adopting technology to using data insights, innovative service models, and cross-sector partnerships to sustain growth. With traditional retail facing rising operating costs, competition from e-commerce, and increasingly diverse consumer needs, moving beyond established business models has become central to corporate transformation. Drawing on FamilyMart Taiwan's experience in membership data management and digital transformation, this talk examines how member data analytics, customer relationship management (CRM), and precision marketing can turn everyday purchasing behavior into operational decisions and new business opportunities, breaking away from a growth model that depends on expanding the physical store network. The talk also presents innovative cases, including electric mobile vehicles and mobile retail services, differentiated product strategies for migrant workers and new immigrants, disaster-relief supply support, and the exploration of unmanned services. These cases show how a company can leverage its existing channels and supply chain to extend services beyond the traditional storefront and open up new markets. Finally, from the perspectives of first-principles thinking and business resilience, the talk discusses how companies in the AI era can identify the real pain points of consumers and employees, assess the business value of adopting new technologies, and build future business models that combine innovation, operational efficiency, and lasting competitiveness in a rapidly changing industry.

    Biography

    Shih-Chieh Huang is Director of the Membership Data Innovation and Research Department at FamilyMart Taiwan and an alumnus (Class of 2019) of the Executive MBA Program in Entrepreneurship and Innovation (EiMBA) at the College of Management, National Taiwan University. He has long been involved in FamilyMart's digital membership strategy, data applications, and precision marketing, turning membership data insights into operational decisions and innovative service strategies and driving the integration of digital technology with physical retail. His talks cover retail digital transformation, the value of membership data, business model innovation, and the innovative thinking and operational resilience companies need in a changing market, drawing on FamilyMart's practical experience to show how traditional industries can create new growth opportunities through data and cross-sector collaboration.

  2. From Intelligent Assistants to Task Collaboration: AI Agents in Industry Applications and Business Transformation

    Shihyu Alex Chu

    Industry Consultant and Section Director, Market Intelligence & Consulting Institute (MIC), Institute for Information Industry

    Abstract

    As generative AI extends from content generation to task execution, the central question for companies is shifting from how to use AI tools to how to build AI into operational processes and create measurable business value. AI agents combine language models, enterprise knowledge and tool integration to help break down tasks, call systems and carry out work within authorized limits, opening new possibilities for human-AI collaboration and service models. Moving from single-function proofs of concept to day-to-day operations, however, still requires overcoming challenges in data quality, system integration, execution reliability and organizational roles. Starting from industry applications and enterprise needs, this talk outlines the main development trends of AI agents and uses representative scenarios from manufacturing, finance, retail and information services to examine their role in knowledge retrieval, customer service, business development and software development. Using an application framework of need identification, task planning, tool execution and result verification, it explains how companies can connect scattered data, knowledge and system functions into sustainable workflows, and design human review and exception handling according to the nature of each task. Finally, from the perspectives of industry development and business value, the talk discusses how companies can choose suitable adoption scenarios, assess cost, efficiency and service quality, and progress step by step from validating a single task to cross-departmental process collaboration. It also considers how information service providers can combine domain knowledge, system integration and ongoing operations capabilities to develop industry-specific AI agent solutions that help companies turn technology adoption into operational gains and new service opportunities.

    Biography

    Shihyu Alex Chu is an Industry Consultant and Section Director at the Market Intelligence & Consulting Institute (MIC) of the Institute for Information Industry. His research covers artificial intelligence, the software and information services industry, enterprise digital transformation and technology policy. He has long followed the technical development, industry applications and business models of generative AI and AI agents, examining the conditions for adopting emerging technologies and their market opportunities from the perspectives of industry analysis and enterprise needs. His talks cover AI industry trends, human-AI collaboration, operational process transformation and development strategies for the information services industry, linking international developments with the Taiwanese industrial context to help companies identify where to apply technology and where to begin their transformation.

AI CUP · Day 1, Fri, Nov 20, 2026 · – · Room C · 2F Liquan Hall C1

AI CUP: From AI Competitions to Cross-Domain Innovation and Talent Development

Session chair: Prof. Shih-Hung Wu, Chaoyang University of Technology

AI CUP, the Ministry of Education’s national AI competition for universities and colleges, uses real-world problems, purpose-built datasets and AI technology competitions to develop AI talent and foster cross-disciplinary research and industry–academia collaboration. In this session, three professors share how their competitions were planned and run, the technical challenges they met and the research that grew out of them, from three angles: competition design and talent development, Agentic AI for ESG sustainability commitment verification, and turning competition results into research and international publications. Moving from competition design to cross-domain technology to academic research, the session looks at how AI competitions can drive innovation in teaching, research, cross-disciplinary collaboration and international academic exchange, and at their role in the next generation of AI technology and talent.

  1. Learning and Research through Competition: Experiences in AI CUP and AI Talent Development

    Prof. Shih-Hung Wu

    Department of Computer Science and Information Engineering, Chaoyang University of Technology; Co-Principal Investigator, AI CUP

    Highlights

    How AI CUP has developed; competition design and operation; bringing competitions into teaching; participation across universities; and talent development outcomes.

  2. From AI CUP to Agentic AI: Designing and Implementing an ESG Sustainability Verification Challenge

    Prof. Min-Yuh Day

    Graduate Institute of Information Management, National Taipei University; organizer of the AI CUP 2026 ESG Sustainability Commitment Verification Challenge

    Abstract

    As the global ESG movement continues to deepen, the authenticity and credibility of corporate sustainability reports matter more and more, and combining AI with ESG has become a key topic in sustainable finance and disclosure. Taking the AI CUP 2026 VeriPromiseESG Sustainability Commitment Verification Challenge as an example, this talk follows the whole journey from designing the competition task and building the dataset to extending the results into research. The competition has four subtasks: promise identification, supporting-evidence linking, clarity classification and verification-timeline inference. It is built on VeriPromiseESG4K, a Traditional Chinese ESG promise verification dataset of 4,000 annotated passages from the real sustainability reports of Taiwan 50 Index companies across 15 industries, published at IEEE EM-RITE 2026 (IEEE IRI 2026). Run jointly by Taiwanese and Japanese academic institutions and linked to an NTCIR-19 international evaluation task, the competition selects outstanding Taiwanese AI CUP student teams to present their research in Japan, deepening international academic exchange and developing internationally competitive AI talent. The talk also discusses how Agentic AI techniques such as large language models, retrieval-augmented generation (RAG) and multi-agent systems can be applied to ESG promise verification, shares lessons from cross-disciplinary teamwork, and looks at how AI can make corporate sustainability disclosure more transparent and trustworthy.

    Highlights

    Designing an ESG competition task; building the dataset; applying RAG and multi-agent systems; cross-disciplinary teamwork; and competition results.

  3. From AI CUP to International Publications: Transforming Competition Outcomes into Research

    Prof. Hong-Jie Dai

    Department of Electrical Engineering, National Kaohsiung University of Science and Technology; organizer of the AI CUP Medical Speech Sensitive Personal Information Recognition Challenge

    Abstract

    AI CUP does more than give students hands-on experience with AI technology. Through real-world problems, dataset construction and competition evaluation, it has become an important platform for academic research and cross-disciplinary collaboration. Starting from the speaker’s own involvement in AI CUP, this talk shares how competition results can be extended into research of academic value. Using the medical sensitive-information de-identification competition as an example, it walks through the practical experience of designing the competition task, analysing participants’ results, and moving on to an international workshop, a Springer proceedings volume and a journal article in npj Digital Medicine. Through this example of combining competitions with academic research, the talk explores how one-off competition outcomes can become research topics that keep developing, advancing AI talent development and international academic exchange.

    Highlights

    The speaker’s experience with AI CUP; turning competition results into research; international workshops and proceedings publication; and experience publishing journal articles.

  4. Panel Discussion: Challenges, Achievements and the Future of AI CUP

    Prof. Shih-Hung Wu, Prof. Min-Yuh Day, Prof. Hong-Jie Dai

ICD · Day 1, Fri, Nov 20, 2026 · – · Room D · 7F Summit Hall

NSTC Intelligent Computing Discipline · Program Briefing & Planning Report

Session chair: Prof. Chia-Hui Chang, Department of Computer Science and Information Engineering, National Central University; Convener, Intelligent Computing Discipline, NSTC · discipline briefing and subfield policy planning

  1. Discipline Program Briefing

    學門業務分享說明

    李明霏 (Assistant Researcher)

    National Science and Technology Council

  2. Policy Planning: Artificial Intelligence and Computational Intelligence Subfield

    人工智慧與計算智慧子領域 政策規劃分享

  3. Policy Planning: Data Science and Internet Subfield

    資料科學與網際網路子領域 政策規劃分享

AISI 1 · Day 1, Fri, Nov 20, 2026 · – · Room C · 2F Liquan Hall C1

Cross-Domain AI Sustainable Innovation · Session 1

Session chair: Prof. Min-Yuh Day, Graduate Institute of Information Management, National Taipei University

  1. AI-Driven Energy Governance and Sustainable Industrial Transformation

    Dr. Shr-Yi Chin

    Senior Research Fellow, Center for Japan and Korea Studies, National Chung Hsing University, Taiwan

    Abstract

    The rapid advance of agentic AI and high-performance computing is extending global industrial competition beyond chips and computing power to energy supply, carbon emissions, and sustainability governance. Drawing on an interdisciplinary perspective spanning energy policy, carbon management, and ESG governance, this talk examines how AI development affects electricity demand, energy security, and corporate net-zero transitions, and analyzes the potential of AI in smart energy management, process optimization, and industrial decarbonization. It introduces an integrated “Token–Electricity–Emissions–Cost” analytical framework and discusses how Taiwan can combine its strengths in semiconductors, energy, energy storage, power grids, and computing to pursue a transformation strategy that balances technological innovation, energy resilience, and sustainable competitiveness.

    Biography

    Dr. Shr-Yi Chin is a Senior Research Fellow at the Center for Japan and Korea Studies, National Chung Hsing University, an Adjunct Assistant Professor in the Department of International Business at Kainan University, and a Board Member of the Taiwan Association for Contemporary Japanese Studies. He received his Ph.D. from the Institute of China and Asia-Pacific Studies at National Sun Yat-sen University and his M.A. from the Graduate Institute of Diplomacy at National Chengchi University. With an interdisciplinary background in engineering, international relations, public policy, and business management, Dr. Chin has long worked on climate governance, energy policy, energy transition, ESG and sustainability governance, carbon management, carbon finance, and international political economy. His work focuses on energy security, industrial competitiveness, and corporate sustainability in the context of the global net-zero transition. Combining academic research with industry practice, he previously served as a Chair Professor in the Startup Development Department of the Taipei Exchange, and has held positions as company chairman and CEO and as an adviser on IPOs and ESG governance, with extensive involvement in collaboration among industry, government, and academia. His professional qualifications include lead verifier and lead auditor credentials for ISO 14064-1 (organizational greenhouse gas inventories), ISO 14068-1 (carbon neutrality), ISO 14067 (product carbon footprint), and ISO 50001 (energy management). His recent research focuses on the interplay between AI development and energy governance, examining the relationships among AI computing demand, power systems, carbon emissions, and the cost of carbon neutrality, and on advancing the integration of AI, energy governance, and industrial net-zero transition. He is the author of Corporate ESG and Net-Zero Carbon Neutrality: Practices in Sustainability Governance (in Chinese) and has contributed to book-length research on AI and carbon neutrality.

AISI 2 · Day 1, Fri, Nov 20, 2026 · – · Room C · 2F Liquan Hall C1

Cross-Domain AI Sustainable Innovation · Session 2

Session chair: Prof. Sherry Chia-Ying Chan, Dean, International College of Sustainability Innovations, National Taipei University · 3 invited talks + Q&A

  1. Combining LLM-Driven Test Generation and Combinatorial Interaction Testing for Financial RAG Chatbot Evaluation

    Prof. Chien-Ping Chung

    Department of Information and Finance Management, National Taipei University of Technology

  2. Beyond Accuracy: Engineering Trustworthy and Sustainable AI for Real-World Deployment

    Prof. Haobijam Basanta

    Department of Electrical Engineering, National Taipei University

  3. Governing Sustainable AI: Bringing Environmental Law into the AI Lifecycle

    Prof. Wei-Lun Chang

    Department of Business Administration, National Taipei University

  4. Q&A with all speakers

AISI 3 · Day 2, Sat, Nov 21, 2026 · – · Room C · 2F Liquan Hall C1

Cross-Domain AI Sustainable Innovation · Session 3

Session chair: Prof. Chih-Chien Wang, Graduate Institute of Information Management, National Taipei University

  1. 1

    Cross-Domain AI and the Challenge of the Digital Divide

    Prof. Chih-Chien Wang

    Distinguished Professor, Graduate Institute of Information Management, National Taipei University

  2. 2

    From Illustrated Law to Animated Law: Sustainable Innovation in Legal Teaching Materials through Generative AI Collaboration

    Dr. Shih-Chieh Chien

    Chief Executive Officer, Taiwan Law Foundation

EXPO · Day 2, Sat, Nov 21, 2026 · – · 5F Lishan Hall exhibition area

NSTC Intelligent Computing Discipline Exhibition, Sessions 1 & 2

Session 1: – (with Poster Session 4); Session 2: – (with Poster Session 5) · 13 NSTC project posters, on display in both sessions, listed by poster number. Titles are English translations except No. 15; the original Chinese title follows each one.

  1. Poster01

    A Metaverse-Based Drug-Craving Induction System Using Multisensory Stimuli and Situational Exposure, and an AI-Based Method for Assessing Addiction Severity

    研發基於元宇宙多感官刺激與情景式暴露的毒癮誘發系統以及基於人工智慧的成癮強度評估方法

    Prof. Shih-Ching Yeh

    Department of Computer Science and Information Engineering, National Central University

  2. Poster02

    Innovative Deep Learning for Gastrointestinal Disease Detection: Integrating an Endoscopy Foundation Model with Multiple-Instance Learning

    深度學習在腸胃疾病偵測中的創新應用:內視鏡基礎模型與多實例學習策略的整合

    Prof. Ying-Feng Chang

    Artificial Intelligence Research Center, Chang Gung University

  3. Poster03

    Advanced AI Techniques for Electromagnetic Imaging of Objects Buried beneath Non-Flat Surfaces

    先進人工智慧技術於非平坦表面下掩埋物體之電磁成像

    Prof. Chien-Ching Chiu

    Department of Electrical and Computer Engineering, Tamkang University

  4. Poster04

    Well-Being Interior Design: Bridging Cognitive Neuroscience and AI through Indoor Space Representation Learning with Encoder–Decoder Attention Networks

    安適室內設計:使用編解碼注意力網路進行室內空間表徵學習橋接認知神經科學與人工智慧

    Prof. Po-Chih Kuo

    Department of Computer Science, National Tsing Hua University

  5. Poster05

    Functional Identification of Membrane and Transport Proteins with a Multi-Window Scanning Deep Learning Model Combining Fast Multiple Sequence Alignment and Language-Model Encoding

    結合快速多重序列比對與語言模型編碼技術的多重視窗掃描深度學習模型來做膜蛋白與運輸蛋白的功能鑑別

    Prof. Yu-Yen Ou

    Graduate Program in Biomedical Informatics, Yuan Ze University

  6. Poster06

    Tumor Neoantigen Prediction with Deep Learning and Protein Language Models and Its Application to Personalized Immunotherapy

    基於深度學習和蛋白質語言模型的腫瘤新抗原預測及其在個人化免疫治療中的應用

    Prof. Yu-Yen Ou

    Graduate Program in Biomedical Informatics, Yuan Ze University

  7. Poster08

    Cross-Camera Multimodal Vehicle Tracking with Vision–Language Models

    整合視覺語言模型之跨相機多模態車輛追蹤

    Prof. Chow-Sing Lin

    Department of Computer Science and Information Engineering, National University of Tainan

  8. Poster09

    Evaluating the Quality of Embedding Features in Deep Learning Models: Developing Effective Metrics

    評估深度學習模型嵌入特徵品質:研發有效量度方法

    Prof. Yi-Chieh Wu

    Interdisciplinary Artificial Intelligence Center, National Chengchi University

  9. Poster10

    A Model-Building Platform Assisted by an LLM-Based Visual Intelligent Assistant

    基於大型語言模型之可視化智慧助理輔助模型建置平台

    Prof. Jui-Hung Chang

    Department of Computer Science and Information Engineering, National Cheng Kung University

  10. Poster11

    Exploring Immune-Related Drug Resistance Factors in Cancer through Machine Learning and Bioinformatics: Integrating scRNA-seq and Bulk RNA-seq Analyses

    透過機器學習和生物資訊學探索癌症中與免疫相關的抗藥性因素:scRNA-seq和Bulk RNA-seq分析的整合

    Prof. Yen-Jung Chiu

    Department of Biomedical Engineering, Chang Gung University

  11. Poster12

    Building a Multimodal Medical Foundation Model for Cancer with Contrastive and Federated Learning

    以對比和聯邦學習方法建立癌症多模態醫學基石模型

    Prof. Che Lin

    Department of Electrical Engineering, National Taiwan University

  12. Poster14

    A Machine-Learning-Based Gene Prioritization Database for Inborn Errors of Immunity

    以機器學習開發先天免疫缺損關連基因優先排序資料庫

    Prof. Cho-Yi Chen

    Institute of Biomedical Informatics, National Yang Ming Chiao Tung University

  13. Poster15

    A novel deep neural framework optimized by the Internet of Things (IoT) for spatial optimization and interpretable lung cancer analysis and smart healthcare systems

    Prof. Zeshan A. Khan

    International Graduate School of Artificial Intelligence, National Yunlin University of Science and Technology

Paper sessions

Paper Sessions

Sessions, rooms, and presentation slots for TAAI 2026 papers. Search by title, author, keyword, or paper ID to find your paper, or link directly to a session or paper. All times are Asia/Taipei (UTC+8).

Oral sessions

About 10 minutes per paper, including Q&A. Papers are presented in the order listed.

Outstanding oral presentations receive the TAAI 2026 Best Oral Paper Presentation Awards, presented at the Closing Ceremony & Awards (Day 2, Sat, Nov 21, 16:30–17:00, Plenary Hall).

Poster sessions

A 3-minute presentation per poster when the poster session chair(s) visit. Each paper has a numbered board: IP- international, DP- domestic. See the poster guidelines.

Outstanding poster presentations receive the TAAI 2026 Best Poster Paper Presentation Awards, presented at the Closing Ceremony & Awards (Day 2, Sat, Nov 21, 16:30–17:00, Plenary Hall).

Day 1

Friday, November 20, 2026

–

IO1 · – · Room A · 2F Lijing Hall A

International Oral Session 1

Topics: Optimization, Theory & RLSpeech & AudioComputer Games & Game AILLMs & NLP

Session chair: Prof. Chien-Chang Chen (Tamkang University) · 8 papers

  1. Score-Based Voting for Diverse Game-AI Teams: Bridging Optimistic and Plurality Voting

    Shogo Takeuchi

    Affiliations: Kochi University of Technology, Japan

    Keywords: Voting, Game, Caibration

    Paper #148 · Computer Games & Game AI

    Abstract

    Voting enables game-AI teams to combine recommendations from multiple engines, but their search-derived win-rate estimates may not be directly comparable. This raises a practical question: how should a team balance the highest reported score against agreement among its members? We investigate temperature-controlled hybrid voting to adjust this balance across team compositions. Low temperatures emphasize score differences, whereas high temperatures give greater weight to recommendation counts. We also examine engine-specific calibration using observed game outcomes to improve the empirical interpretation of reported scores.

    Experiments in $9\times9$ Go compare four three-engine teams, from identical Pachi instances to a heterogeneous combination of Fuego, Pachi, and Ray. Among the evaluated score-based rules, teams with lower observed decision diversity achieve their highest observed raw-score win rates at lower temperatures, whereas more diverse teams favor higher temperatures. Both Logit and Beta calibration improve held-out predictive metrics for all seven engines, but these improvements do not consistently translate into stronger team play. For a team of related Pachi variants containing a substantially weaker member, Beta calibration increases the observed optimistic-voting win rate from 46.26\% to 55.84\%. The heterogeneous team achieves its best observed win rate without calibration. These results suggest that score calibration should be evaluated together with the aggregation rule and team composition, rather than judged solely by individual predictive quality.

  2. Distributed Bandit Learning toward Social Optimum in Congestion Games: Nonlinear Costs and Convergence Analysis

    Shu-Ting Chang, Yi-Lin Chang, Kuan-Hsu Lo, Zih-Cheng Lyu

    Affiliations: National Yang Ming Chiao Tung University, Taiwan

    Keywords: Congestion games, Distributed bandit learning, Social optimum, Quadratic costs, Gradient estimation

    Paper #194 · Optimization, Theory & RL

    Abstract

    Distributed multi-agent learning in congestion games under bandit feedback aims to reach the social optimum when each player only observes the cost of its chosen path. Existing work by Cheng et al. adapts the generalized mirror descent framework in the bandit setting of Chen and Lu from tackling Nash equilibrium to coping with social optimum. This paper investigates the framework under nonlinear congestion costs, with particular attention to quadratic cost functions of the form $c_e(\ell)=a_e\ell^2+b_e\ell+c_e$, which can model increasing marginal costs such as delays in traffic congestion.

    We examine a three-point perturbation procedure based on negative, zero, and positive path-cost observations. Although this procedure provides a practical path cost reconstruction under linear edge costs, its relationship to the true social-cost gradient requires further analysis. For the marginal-cost sample-average estimator in [1, Equation (7)], we establish a high-probability error bound with bias of order $O(m/n)$ under additional smoothness assumptions. We also derive a conditional social-cost convergence result under a bounded gradient-estimation error for lin ear edge costs, showing that the social cost eventually remains within a bounded neighborhood of its minimum. However, whether the three-point reconstruction satisfies the required error bound remains an open question. Numerical experi ments with 10 players, 7 edges, and 6 paths show that the social cost decreases and subsequently stabilizes over 300 learning epochs across 10 independent runs. These results illustrate the behavior of distributed bandit learning under quadratic congestion costs while highlighting the remaining theoretical challenges.

  3. EF1-Constrained Nash Social Welfare with Identical Additive Valuations: Complexity, Guarantees, and Experiments

    Zih-Sian Yang1, Yi-Hao Chen1, Yu-Te Kuan1, Cheng-Jui Wu1, Chuang-Chieh Lin1, Po-An Chen2

    Affiliations: 1National Taiwan Ocean University, Taiwan 2National Yang Ming Chiao Tung University, Taiwan

    Keywords: Fairness, Envy-freeness up to one good (EF1), Nash social welfare, Deep reinforcement learning, Prospective action masking, Online streaming

    Paper #26 · Optimization, Theory & RL

    Abstract

    We study the allocation of indivisible goods among agents with identical additive valuations, focusing on envy-freeness up to one good (EF1) and Nash social welfare (NSW). Since every maximum-NSW allocation is EF1 under additive valuations, the associated threshold problem inherits the known strong NP-hardness of NSW maximization under identical additive valuations and is strongly NP-complete. We therefore focus on welfare guarantees satisfied by arbitrary EF1 allocations. Although every such allocation is known to achieve an $e^{-1/e}$-approximation to the unrestricted optimal NSW, we identify conditions yielding stronger guarantees. Under uniform valuations, every EF1 allocation is NSW-optimal. Under an $\varepsilon$-small-item condition, every EF1 allocation achieves an explicit approximation ratio $\rho_n(\varepsilon)$ satisfying $\rho_n(\varepsilon) = 1-O(\varepsilon^2)$ as $\varepsilon\to 0$ for fixed $n$.

    We further consider the stronger sequential requirement that $\operatorname{EF1}$ be maintained after every item assignment. For this setting, we propose \emph{PriorityNet}, a deep reinforcement learning framework trained using Proximal Policy Optimization and equipped with prospective $\operatorname{EF1}$ action masking. The mask restricts every decision to assignments that preserve $\operatorname{EF1}$, thereby guaranteeing prefix-wise $\operatorname{EF1}$ by construction without post-processing repair. Across 3,000 test instances in each of the offline and random-order online regimes ($n\in[2,20]$ and $m\in[5,100]$), PriorityNet attains mean normalized $\operatorname{NSW}$ values of $0.9911$ and $0.9701$, respectively. Relative to offline Longest Processing Time (LPT) and online least-valued-bundle baselines, it achieves instance-wise win-minus-loss rates of $+27.10\%$ and $+17.87\%$, while matching the offline baseline's mean normalized welfare to four decimal places and modestly improving the online mean from $0.9694$ to $0.9701$.

  4. DEPO: Dual-module Evaluator for Few-shot Prompt Optimization

    Chun-Pai Yang1, Ying-Chun Lai2, Shou-De Lin1

    Affiliations: 1National Taiwan University, Taiwan 2Chung Shan Medical University, Taiwan

    Keywords: Prompt optimization, Large language models, Few-shot learning

    Paper #87 · Optimization, Theory & RL

    Abstract

    Prompt optimization is essential when deploying large language models in real-world applications. Existing prompting techniques are effective in scenarios where performance can be directly evaluated using standard references. However, numerous generative tasks lack explicit evaluation metrics, presenting considerable challenges for optimizing prompts effectively. To address the issue, we propose DEPO, a novel few-shot automated prompt optimization framework. Distinct from conventional approaches, DEPO introduces an evaluator module acting as a surrogate metric, enabling reliable output quality evaluation. Notably, our framework requires only a single round of human annotation for training samples to complete the whole prompt optimization process, thereby significantly reducing the need for human effort. Comprehensive experiments conducted on multiple public datasets demonstrate that DEPO consistently outperforms existing prompt optimization and output scoring approaches.

  5. Phase-wise Economic Policy Optimization for Auto-Battler Games using Evolutionary Algorithms

    Ching-Ting Chen, Yi-En Dong, Yi-Ruei Chen, Chuan-Kang Ting

    Affiliations: National Tsing Hua University, Taiwan

    Keywords: auto-battler game, game strategy optimization, evolutionary computation, genetic algorithm, evolution strategies

    Paper #207 · Optimization, Theory & RL

    Abstract

    Economic decision making plays a critical role in auto-battler games. Effective strategies must balance short-term survival and long-term growth while adapting to different game phases under multi-player competition. However, existing approaches largely rely on human-designed heuristics and lack a systematic framework for optimizing phase-dependent economic strategies. To address this gap, this study proposes a simulation-based evolutionary optimization framework for phase-wise economic policies in Teamfight Tactics (TFT), a popular auto-battler game. The economic decision process is parameterized into a compact, interpretable policy representation; furthermore, this study employs genetic algorithm (GA) and evolution strategies (ES) to optimize the policy parameters. To enable efficient policy evaluation, a simplified simulation environment is developed, in which combat outcomes are approximated using board power comparisons, and artificial opponents are generated by sampling from real match data. Simulation-based validation demonstrates that the proposed environment reproduces realistic survival dynamics observed in actual gameplay. Experimental results show that both GA and ES can effectively improve economic policies, with ES achieving superior performance. The evolved policies outperform a human-designed heuristic baseline across multiple gameplay-oriented metrics, including average rank, Top-4 rate, and win rate. Further analysis highlights the importance of phase-wise policy representation, showing that policies explicitly distinguishing between early, mid, and late game phases consistently achieve better performance. These results demonstrate that evolutionary optimization, when combined with a data-driven simulation environment, provides an effective and interpretable approach for optimizing economic strategies in complex multi-player auto-battler games.

  6. Contextual Biasing for Streaming ASR via CTC-based Word Spotting

    Kai-Chen Tsai1, Tien-Hong Lo1, Yun-Ting Sun1, Hsueh-Wei Liao2, Berlin Chen1

    Affiliations: 1National Taiwan Normal University, Taiwan 2Realtek, Taiwan

    Keywords: Contextual biasing, Streaming ASR, CTC, RNN-T, Keyword Spotting

    Paper #153 · Speech & Audio

    Abstract

    Contextual biasing for ASR improves the recognition of rare and domain-specific terms, but most context-biasing methods involve modification of the ASR model, additional training, or changes to the beam-search decoding algorithm, complicating deployment and model reuse. CTC-based word spotting (CTC-WS) avoids these limitations by detecting target phrases from CTC log probabilities, but its offline formulation assumes complete utterances and cannot reliably handle phrases split across chunks. This paper proposes Streaming CTC-WS, which turns offline CTC word spotting into a stateful streaming context-biasing procedure. The method carries active keyword paths across chunks through token passing and applies incremental commitment to emit only stable regions while deferring unfinished keyword hypotheses. Streaming CTC-WS is compatible with hybrid CTC/RNN-T ASR models and requires neither acoustic-model modification nor additional training. Experiments on the publicly available STOP1 and STOP2 datasets show consistent improvements in WER and keyword F-score. On STOP1, Streaming CTC-WS reduces CTC WER from 18.36\% to 12.83\% and improves keyword F-score from 66.84\% to 89.61\%. These results indicate that stateful CTC word spotting is effective for streaming contextual biasing.

  7. SpokenWait: A Benchmark for Real-Time Voice Agents Awaiting Tool Results

    Bo-Xuan Zheng, Yu-Kai Guo, Ho-Lam Chung, Hung-yi Lee

    Affiliations: National Taiwan University, Taiwan

    Keywords: real-time voice agents, asynchronous tool use, spoken interaction, response latency, benchmarking

    Paper #195 · Speech & Audio

    Abstract

    Real-time voice agents increasingly rely on external tools whose results may remain unavailable for several seconds. Existing evaluations, however, primarily emphasize final-answer correctness or end-to-end latency, leaving the agent’s behavior during this waiting interval largely unexamined. We introduce SpokenWait, a benchmark of 100 human-reviewed tasks across ten everyday service domains, including both one-step workflows and two-step workflows with cross-stage tool dependencies. We evaluate five real-time voice agents under controlled tool delays using stage-aware measures of speech coverage, maximum silence, response latency, and correctness. Our results reveal substantially different waiting strategies: some agents actively occupy the interval, whereas others remain almost entirely silent. Moreover, greater speech coverage does not necessarily correspond to shorter uninterrupted silences or faster incorporation of returned results, while answer accuracy alone provides limited separation among the strongest agents. A matched pending-state cue study further shows that a lightweight intervention can increase speech coverage and reduce maximum silence, but does not improve answer accuracy or result-to-answer latency. These findings establish tool-waiting behavior as a distinct and measurable dimension of real-time voice-agent evaluation.

  8. Correspondence Between Repeated-Run LLM Variation and Human Disagreement in Sentence-Level News Annotation

    Mai Sugimoto, Mitsunori Matsushita

    Affiliations: Kansai University, Japan

    Keywords: LLM annotation, human annotation, annotation variation, human–LLM correspondence

    Paper #106 · LLMs & NLP

    Abstract

    Improving an annotation specification commonly involves revising it in response to disagreements observed during pilot annotation. Recent work has used LLM disagreement or repeated-run instability to prioritize cases for human review. We examine how repeated-run variation under a fixed LLM condition behaves as a screening signal across multiple sentence-level judgments on the same set of news articles. We use five Japanese political news articles annotated by 13 student annotators and compare their local judgments with ten repeated runs per article under each of three fixed LLM conditions: GPT-5.6 Sol, Claude Sonnet 5, and Gemini 3.8 Flash. For the indicator asking whether a sentence contains an individual's opinion (S1), the human-disagreement base rate was .44; the three conditions selected 11--17 of 68 sentences as candidates, with precision of .65--.91 and recall of .33--.43. Under the primary non-unanimity criterion, 61 of the 68 sentences were human-disagreement sentences for the indicator distinguishing episodes from themes (F2); for 20 of these same sentences, all three fixed LLM conditions were constant across all ten runs. Overall, rank correspondence between human variation and repeated-run LLM variation was indicator-dependent: pooled rank correlations over all 68 sentences were positive under all three conditions for S1, whereas F2 showed no positive rank-correlation pattern shared by all three conditions and included many human-disagreement sentences with stable repeated outputs.

DO1 · – · Room B · 2F Lijing Hall B

Domestic Oral Session 1

Topics: Data Mining & ForecastingComputer Games & Game AIOptimization, Theory & RLSecurity & Trustworthy AI

Session chair: Prof. Ying-Jia Lin (Chang Gung University) · 7 papers

  1. Lightweight Dual-Stream Temporal Decoupling for Behavior Cloning in Minecraft's Hybrid Action Space

    張晉瑋 (Jin-Wei Jhang), 黃意婷 (Yi-Ting Huang)

    Affiliations: 國立臺灣科技大學電機工程系

    Keywords: Minecraft, behavior cloning, dual-stream Transformer, hybrid action space, feature decoupling

    Paper #83 · Computer Games & Game AI

    Abstract

    Minecraft’s native keyboard-and-mouse interface simultaneously supports first-person 3D World control and 2D GUI interaction, which exhibit substantial differences in action distributions, temporal structures, and spatial requirements. In this work, we construct a lightweight behavior cloning model using a 20.25-hour subset of the OpenAI Video PreTraining (VPT) Contractor Dataset, consisting of 267 recordings and 1,405,556 frames. We propose a mode-predictor-driven Dual-Early Transformer, in which World and GUI interactions are represented by separate Transformer streams from the beginning of temporal modeling, while maintaining approximately the same total number of temporal blocks and model parameters as the single-stream baseline. Data analysis shows that the Jensen–Shannon divergence between the World and GUI keyboard distributions reaches 0.769 bits, while GUI cursor trajectories exhibit clear target convergence prior to clicking. On an independent test set with a fixed temporal window of T=32, Dual-Early improves Keyboard macro-F1 by 10.1%, Mouse macro-F1 by 41.7%, and Hotbar accuracy by 9.4%, while reducing Cursor MAE by 13.2% compared with the Single baseline. These improvements require only a 0.082% increase in model parameters and approxim-ately a 7.4% increase in pure forward-pass latency on an NVIDIA H200 GPU. Further ablation studies on the router and 2×2 temporal/head specialization indicate that the primary performance gains arise from domain-specific temporal representations. In addition, a parameter-matched multi-scale CBS(MS-CBS) module is evaluated as supplementary validation. With only a 0.149% increase in parameters, MS-CBS further improves validation Keyboard and Mouse F1 scores by 13.9% and 30.0%, respectively, supporting the complementarity between multi-scale spatial representation and temporal decoupling.

  2. 一個整合深度強化學習與蒙地卡羅模擬之混合式台灣麻將丟牌策略架構

    劉柏毅 (Po-Yi Liu), 黃國展 (Kuo-Chan Huang)

    Affiliations: 國立臺中教育大學資訊工程學系

    Keywords: 台灣麻將, 丟牌處理, 深度學習, 蒙地卡羅模擬, 強化學習

    Paper #189 · Computer Games & Game AI

    Abstract

    本研究以先前台灣麻將競賽冠軍程式Rowlet為基礎,提出一個混合式丟牌處理架構,整合了原本的深度學習、蒙地卡羅模擬,以及新引進的搭配了預訓練的強化學習作法,採用循序漸進的方式來進一步提升AI 代理的表現。實驗結果顯示,我們所提出的混合式丟牌處理架構,以及相關的改進機制,在500局的對戰中,能夠擊敗原本的Rowlet版本,證實了深度強化學習於台灣麻將對局中的應用潛力。

  3. CoRe-QCNN:基於跨解析度學習的樣本自適應量子影像分類

    李洳錚 (Ru-Jheng Li)1, 凃瀞珽 (Ching-Ting Tu)2, 王雅書 (Ya-Shu Wang)1

    Affiliations: 1國立中興大學應用數學系 2國立中興大學資料科學與資訊計算研究所

    Keywords: 量子機器學習, 量子卷積神經網路, 跨解析度學習, 樣本自適應參數生成, 遙測影像

    Paper #199 · Optimization, Theory & RL

    Abstract

    現階段量子影像分類受限於可用量子位元數量與電路執行成本,通常需先降低影像解析度再進行量子編碼。此處理雖可降低量子資源需求,卻使不同影像在降採樣後保留不同程度的空間結構與類別判別資訊。若量子卷積神經網路(quantum convolutional neural network, QC-CNN)對所有輸入影像共享同一組量子卷積參數,便等同以固定的特徵轉換處理具有不同資訊缺失型態的低解析度(low-resolution, LR)樣本,因此難以依個別樣本調整量子特徵擷取。 為處理上述問題,本研究提出跨解析度量子卷積神經網路(Cross-Resolution QCNN, CoRe-QCNN)。其核心不是增加量子電路規模,而是利用訓練期間可取得的高解析度(high-resolution, HR)影像,學習「樣本內容與適合量子轉換參數之間的關係」。首先,成對HR/LR影像被映射到同一個可比較且具類別判別能力的表示空間;接著,由HR表徵產生配對LR樣本所使用的量子卷積參數。因而,在固定QC-CNN電路架構下,不同LR樣本可採用不同的特徵轉換,而不需增加量子位元數。 訓練完成後,系統將HR訓練表徵與其量子參數存入離線資料庫。推論時僅輸入LR影像,先以其表徵搜尋最相近的HR訓練表徵,並使用其參數完成量子特徵擷取與分類。無須HR測試影像。 在五個地球觀測影像分類資料集上,於相同8×8量子輸入解析度與QC-CNN骨幹下,CoRe-QCNN相較於本研究重新實作的共享參數QC-CNN,分類準確率提升8.13至35.17個百分點。

  4. 基於隱式神經表示法與時空交叉注意力機制之高解析度 PM2.5 預報偏差修正

    高哲凱 (Che-Kai Kao), 林上文 (Shang-Wen Lin), 凃靜珽 (Ching-Ting Tu)

    Affiliations: 國立中興大學資料科學與資訊計算研究所

    Keywords: PM₂.₅, 預報偏差修正, 隱式神經表示, 交叉注意力, 連續時空場

    Paper #168 · Data Mining & Forecasting

    Abstract

    數值空氣品質預報可提供區域性細懸浮微粒(PM₂.₅)污染趨勢,但仍受排放清冊、氣象輸入與模式參數化誤差影響;既有資料驅動修正方法則多限制於固定測站或規則網格。本文將 PM₂.₅ 預報偏差修正建模為連續時空場估測問題,提出結合隱式神經表示法(Implicit Neural Representations, INRs)與氣象引導交叉注意力的架構。模型整合測站前 24 小時的 PM₂.₅ 與氣象觀測、未來 24 小時的網格化空氣品質預報(Air Quality Forecast, AQF;包含 PM₂.₅ 與氣象預報),以及查詢位置與預報時步,分別聚合測站與預報網格資訊,再以乘法調變 Gabor 網路(Multiplicative and Modulated Gabor Network, MMGN)輸出指定時空座標的校正濃度。以臺灣本島 75 個測站及 2024 年獨立測試資料評估,本文模型相較原始 AQF 的 RMSE 與 MAE 分別降低 36.6% 與 38.3%;高濃度事件的誤報率(False Alarm Ratio, FAR)由 0.774 降至 0.278,誤報次數由 23,772 降至 2,810。結果顯示,本方法在本資料與測試設定下可同時進行測站級偏差修正與連續空間查詢。

  5. Enhanced API Recommendation using Community Question-Answering Information

    Tong-Hua Lin, Liang-Chen Lu, Min-Hui Hsu, Chia-Li Chang, Guan-Lin Chen, Cheng-Zen Yang

    Affiliations: Yuan Ze University, Taiwan

    Keywords: API Recommendation, Community Question-Answering Information, Lexical Gaps, Semantic Mismatch

    Paper #108 · Data Mining & Forecasting

    Abstract

    In software development, application programming interface (API) functions are crucial for program functionality. In the past, many query-based API recommendation approaches have been proposed to help software developers efficiently develop programs. However, these query-based approaches suffer from problems such as lexical gaps and semantic mismatches. For these two issues, this paper proposes an API recommendation approach, CQAAR, based on the document embeddings of community-based question-answering (CQA) information. The CQAAR approach has been applied to a query-based model BIKER model, and the experimental results show that CQAAR consistently outperforms BIKER for method-level and class-level recommendation performance in terms of the Mean Reciprocal Rank (MRR) index and the Mean Average Precision (MAP) index.

  6. Revisiting Evaluation in Neural Weather Forecasting: Reporting Choices and Evidence Limits

    Shao-Kang Huang, Yu-Xiang Liu, Ting-Yuan Wang, Lu-Hung Chen

    Affiliations: National Chung Hsing University, Taiwan

    Keywords: Neural weather forecasting, neural operators, model evaluation, reproducibility, checkpoint selection

    Paper #112 · Data Mining & Forecasting

    Abstract

    We audit archived neural weather forecasting experiments on 96 ERA5 single-level variables at 33×64 resolution using 27 training logs, saved configurations, and retained code. Recomputing each seed's minimum test error gives a spherical hybrid an MSE of 0.3915 versus 0.4017 for UNet++. Using the final checkpoint instead gives 0.4096 and 0.4085, reversing the mean ordering without establishing superiority. The archive supports this reporting correction, but lacks the historical boundaries needed to exclude a documented training-window overlap. Inspection also identifies unequal FFT-SHT spectral capacity and non-equivalent standalone and hybrid local networks. These comparisons are therefore retained as descriptive cases. The audit separates recoverable reporting decisions from missing evidence that prevents verified held-out performance claims; changing checkpoints cannot repair possible training-test contamination.

  7. Graph-CKA:結合化學知識圖譜上下文之大型語言模型安全測試方法

    陳廷鈞, 謝文川, 龔千芬

    Affiliations: 國立高雄科技大學智慧商務系

    Keywords: 大型語言模型, 安全測試, 越獄攻擊, 知識圖譜, 自動化紅隊測試, Graph-CKA, 化學安全

    Paper #117 · Security & Trustworthy AI

    Abstract

    大型語言模型(Large Language Models, LLMs)逐漸應用於科學研究與專業知識處理,但在高風險領域中仍可能受到多輪知識探索式越獄攻擊。現有 CKA-Agent 能依據目標模型回應動態調整搜尋路徑,但候選知識主要來自模型本身,而外部知識圖譜則能提供結構化領域資訊。為探討外部領域知識對動態搜尋式安全測試的影響,本研究提出 Graph-CKA,於每一測試案例開始時由化學知識圖譜擷取固定的領域知識上下文,並結合 CKA 的目標模型回應與動態搜尋樹進行多輪測試。本研究針對 GPT-5.2、GPT-5.4 與 Claude Sonnet 4.5 進行比較。結果顯示,Graph-CKA 在 No Context 條件下對三個目標模型皆呈現較高的最終攻擊成功率,但其早期成功能力與搜尋效率未一致優於 Original CKA,顯示外部知識圖譜上下文的效益會受到目標模型與上下文設定影響。

PS1 · – · Poster Area · 2F Liquan Hall exhibition area

Poster Session 1 (International)

Topics: Optimization, Theory & RLData Mining & ForecastingAI for HealthLLMs & NLP

Session chairs: Prof. Yung-Chun Chang (Taipei Medical University); Prof. Hung-Hsuan Chen (National Central University) · 8 papers

  • BoardIP-01

    A multiobjective evolutionary algorithm with adaptive mating and environmental selection for dynamic economic emission dispatch

    Mao-Ting Lee, Thammarsat Visutarrom, Tsung-Che Chiang

    Affiliations: National Taiwan Normal University, Taiwan

    Keywords: Economic dispatch, Emissions, Evolutionary algorithm, Multiobjective, Adaptive selection

    Paper #190 · Optimization, Theory & RL

    Abstract

    Dynamic Economic Emission Dispatch (DEED) is a challenging constrained multiobjective optimization problem that seeks to simultaneously minimize power generation cost and pollutant emissions. In this paper, we propose EAGAMES-MOEA/D, an enhanced decomposition-based multiobjective evolutionary algorithm featuring an adaptive search framework with two complementary selection mechanisms. The proposed adaptive mating selection mechanism allocates computational resources by jointly considering convergence and diversity, while the adaptive environmental selection mechanism dynamically switches between weighted sum and Tchebycheff scalarizing functions according to the distribution of the current population. The proposed algorithm is evaluated on six representative DEED benchmark problems ranging from 5 to 40 generating units and compared with 26 existing algorithms. Experimental results demonstrate that EAGAMES-MOEA/D consistently produces well-converged and well-distributed approximation fronts under competitive computational budgets.

  • BoardIP-02

    Graph Neural Network-Driven Reinforcement Learning for Job-Shop Scheduling

    Yang-Rui Li, Yi-An Chen, Ming-Yi Ju

    Affiliations: National University of Tainan, Taiwan

    Keywords: Job-shop scheduling, Graph neural network, Reinforcement learning, Proximal policy optimization, Size generalization

    Paper #67 · Optimization, Theory & RL

    Abstract

    This paper investigates graph neural network-based reinforcement learning for deterministic job-shop scheduling (JSSP), aiming to minimize makespan. Each instance is represented as a disjunctive graph using a five-feature operation representation combining scheduling status and workload information. A two-layer graph convolutional network (GCN) with proximal policy optimization (PPO) is used to compare two policy architectures under this common representation. GCN-RL1 employs a mean-pooled graph embedding with a fixed-dimensional policy head, whereas GCN-RL2 uses candidate-wise scoring to support variable-size action sets. On 100 unseen random instances per problem size, GCN-RL1 achieves average makespans of 558.88 and 982.77 on $6\times6$ and $10\times10$ JSSPs, respectively. It also obtains the lowest aggregate relative scheduling error (RSE) of 17.5\% among the evaluated methods on selected Ft, Orb, and La benchmarks. GCN-RL2 trained on $15\times15$ instances transfers directly to Taillard instances up to $100\times20$, achieving an RSE of 13.3\% on the $100\times20$ group. These results illustrate differences in same-size scheduling performance and cross-size applicability. The implications of non-delay scheduling are also discussed.

  • BoardIP-03

    A Comparative Study of n-Step Returns for State-Augmented Double DQN under Action Delays

    Yi-Sheng Chen, Feng-Nan Hwang

    Affiliations: National Central University, Taiwan

    Keywords: Double Deep Q-Network, Action delay, n-step retun, Reinforcement learning, State augmentation

    Paper #98 · Optimization, Theory & RL

    Abstract

    Standard reinforcement-learning formulations generally assume that a selected action affects the environment immediately. In practical control systems, however, actions may be executed only after a fixed delay, making it difficult to associate an action with its subsequent effects. State augmentation addresses this problem by appending the pending action sequence to the physical state, while $n$-step returns incorporate multiple sampled rewards before bootstrapping from an action-value estimate. This study empirically compares backup lengths in state-augmented Double Deep Q-Network (DDQN) under fixed action delays using CartPole-v1 and independent training seeds. The results show that backup length affects evaluation performance, learning speed, and consistency across training seeds. Larger tested backup lengths often achieve higher mean evaluation returns over a wider range of delays, although performance does not improve monotonically with $n$. All tested settings yield low returns under very long delays. Matching the backup length to the earliest reward that can reflect the selected action does not consistently yield the highest mean evaluation return among the tested settings. These findings suggest that backup length should be considered alongside action delay.

  • BoardIP-04

    Development of a System for Estimating Mental-Physical States Based on Biological, Behavioral, and Environmental Data

    Daisuke Kitakoshi1, Ayano Kubo1, Arao Funase2, Kentarou Suzuki3, Masato Suzuki1

    Affiliations: 1National Institute of Technology, Tokyo College, Japan 2National Rehabilitation Center for Persons with Disabilities, Japan 3Kyorin University, Japan

    Keywords: Mental-Physical States Estimation, Activity log, Preventive care

    Paper #36 · Data Mining & Forecasting

    Abstract

    Our research group has been developing a Mental-Physical States Estimation System that estimates the degradation of the respective users' mental-physical states and then supports the system users' healthy daily lives continuously by promoting awareness and behavioral improvements. To achieve the above goal, this paper aims to investigate the relationships among three kinds of data regarding participants' biometric, weather, and activity log(life-log) information collected through experiments, and to clarify valuable features available for the prediction of their mental-physical states.

    Experiments are conducted to evaluate relationships among participants' mental-physical states, biometric information, activity logs, and environmental information. In the experiments, participants were instructed to wear a wearable device (watch-shaped activity tracker) to record their biometric data and input their activity logs into the activity-log application we developed in this research. Experimental results showed relationships between sleep patterns and mental-physical load, between weather information and the load, and so on. However, further investigations are needed to achieve mental-physical state estimation.

  • BoardIP-05

    A Shikakeology-Based Graphically Illustrated Recommendation System

    Ying-Yu Chen1, Hiroki Shibata1, Lieu-Hen Chen2, Yasufumi Takama1

    Affiliations: 1Tokyo Metropolitan University, Japan 2National Chi Nan University, Taiwan

    Keywords: AI Recommendation, Image-based Recommendation, Shikakeology

    Paper #59 · Data Mining & Forecasting

    Abstract

    In the era of information overload, recommendation systems play a critical role by efficiently guiding users toward desired information or products. Although personalized recommendations often enhance user experiences, excessive personalization can result in user discomfort and negative reactions. To address these concerns, this paper proposes a Graphically Illustrated Recommendation System that integrates AI-generated recommendations, image generation technologies, and psychological and behavioral theories. In addition, the system also employs culturally intuitive interactive elements—including selecting traditional Japanese charms (Omamori) and comic-style character illustrations—to implicitly detect user preferences and individual status in a comfortable and engaging manner. Finally, the recommendation content, which includes strategically embedded recommended items, is seamlessly integrated into visually appealing tarot-style images and positively oriented tarot-themed textual interpretations, both generated through generative AI tools including ChatGPT and Stable Diffusion. Experimental results using a virtual E-Mall with 12 participants showed that Hit Rate increased from 33.3% to 75.0% by experiencing interaction with the proposed system. In addition, their emotional responses after interacting with the system indicated that participants accepted the recommended items while showing generally positive emotional responses toward the recommendation process. By aligning with the FAD principles of Shikakeology—ensuring fairness through user-controlled interactions, enhancing attractiveness via culturally familiar and gamified elements, and embedding dual purposes of entertainment and recommendation—the proposed system offers an user-centered design that balances personalization with psychological comfort and cultural resonance.

  • BoardIP-06

    Playlist-Based Synthetic Dataset Generation for Context-Aware Music Recommendation

    Masato Imamura, Hiroki Shibata, Yasufumi Takama

    Affiliations: Tokyo Metropolitan University, Japan

    Keywords: Synthetic data, Music recommendation, Session-based recommendation, Context-aware recommendation

    Paper #53 · Data Mining & Forecasting

    Abstract

    This paper proposes a method for generating synthetic playlist dataset for context-aware session-based music recommendation. In music recommendation, users' preferences may vary depending on contexts such as activity, mood, and season, but constructing large-scale sequential dataset with contextual information is difficult. To address this problem, the proposed method extracts context-related playlists from the Spotify Playlists Dataset based on playlist names. Using the collected data as a seed, synthetic playlists dataset are generated considering context-specific track distributions. The quality of the synthetic dataset generated from Spotify playlist dataset is evaluated by training recommendation models with three conditions: training with real playlist dataset associated with target contexts (Real matched), training with context-based synthetic dataset generated by the proposed method (ContextSynth), and randomly generated dataset (Random). GRU4Rec and SASRec are trained on each condition. Recommendation performance is evaluated on test data from Spotify. Experimental results show that ContextSynth consistently outperforms Random, although it does not reach the performance of Real matched. These results suggest that incorporating contextual information into synthetic playlist dataset is effective for constructing training data for session-based music recommendation.

  • BoardIP-07

    Performance-Based Evaluation of XAI Feature Rankings

    Kuo-Wei Chen, Chih-Wei Hsu, Ying-Jia Lin

    Affiliations: Chang Gung University, Taiwan

    Keywords: Explainable Artificial Intelligence, Feature Selection, Feature Ranking, XGBoost, LightGBM

    Paper #111 · AI for Health

    Abstract

    Explainable artificial intelligence (XAI) methods are increasingly used to derive feature-importance rankings, yet a feature that explains a trained model well is not necessarily the most useful one once the model is retrained on a reduced input set. This study evaluates XAI rankings from a performance-based feature-selection perspective. Six methods---SHAP, LIME, PDP, ALE, permutation importance (PI), and tree-based feature importance (FI)---are compared on WDBC, WPBC, and Spambase with XGBoost and LightGBM: within each cross-validation fold, rankings are generated from the training partition only, top-$k$ subsets are retrained with five seeds, and AUC is measured on the held-out fold. MIP reranking, rank aggregation, and the ANOVA and mutual information (MI) filters serve as comparisons. Across the 24 settings (three datasets, two models, and four top-$k$ values for each dataset), no XAI method is universally best: FI and PI are most often the strongest ranking, but each leads in fewer than a third of the settings. The choice of method matters mainly when very few features are kept, except on the small WPBC dataset. At larger top-$k$ the six rankings yield similar AUC and, with one exception, exceed the filter baselines; at the smallest top-$k$, ANOVA and MI are comparable to at least half of them. MIP yields no consistent gain, and simple rank aggregation is comparable to the best single ranking on two of the three datasets. These results support evaluating explanation-derived rankings through downstream retraining rather than treating explanation importance as a proxy for feature-selection quality.

  • BoardIP-08

    Effects of On-Screen Feedback Display on Error Repair in an LLM-Based Japanese Speaking-Practice System

    Yangdi Ni, Junjie Shan, Megumi Yasuo, Yoko Nishihara

    Affiliations: Ritsumeikan University, Japan

    Keywords: Computer-assisted language learning, Large language models, Dialogue-hint feedback, Corrective feedback, Learner uptake, Japanese as a second language

    Paper #62 · LLMs & NLP

    Abstract

    Large language models (LLMs) can support spoken language practice, but it is unclear how corrections should be displayed during a conversation. We built a Japanese speaking-practice system that recognizes learner speech, checks grammar, vocabulary, and politeness, generates a corrected sentence, and replies as a conversation partner. Twelve learners used three display conditions: no text (C1), subtitles (C2), and subtitles plus panel (C3). The partner's voice is played in every condition. C2 adds text to C1: the partner's replies, and each learner turn as two lines, the kana the system heard and the corrected sentence, without marking what was changed. C3 adds to C2 a feedback panel that shows error details and repeats the corrected sentence. Each learner completed the same scenario twice under each condition. We checked whether errors flagged in the first conversation were repaired in the second. Repair rates were 74% under C1, 45% under C2, and 67% under C3. Words from the corrected sentences reappeared most often under C3, and 10 of the 12 learners ranked C3 first. Learners rated C2 positively despite its lowest repair rate. With 12 learners, most differences between conditions were not clear; the clearest was the lower repair rate under C2 than under C1. These exploratory results suggest that showing the corrected sentence without marking what was changed may not help learners use the correction.

–

IO2 · – · Room A · 2F Lijing Hall A

International Oral Session 2

Topics: Computer Games & Game AIData Mining & ForecastingAI for HealthComputer Vision & Multimodal

Session chair: Prof. Yi-Zeng Hsieh (National Taiwan University of Science and Technology) · 8 papers

  1. Analyzing Features of Natural Truncation and Branching Points in Shogi AI Principal Variations

    Taisei Kikkawa, Takeshi Ito

    Affiliations: The University of Electro-Communications, Japan

    Keywords: shogi AI, principal variation, explainable artificial intelligence

    Paper #137 · Computer Games & Game AI

    Abstract

    A principal variation (PV) generated by a shogi AI can help users understand move intent, whereas a long, unbranched sequence can be difficult to interpret. We investigated features associated with points judged natural for truncation and with candidate points at which alternative moves should also be considered. Twenty-three adults evaluated two PVs for each of 12 positions. Truncation was modeled as a discrete-time survival process and branching as a binary choice, using mixed-effects logistic regression with random intercepts for participants, candidate points, and response units. The mixed-effects model suggested an association between truncation and position within the PV, whereas the corresponding GEE joint test was not significant either before or after Holm adjustment; thus, no stable position feature for truncation was identified. For branching, a tenfold decrease in policy was associated with 1.77 times the odds of selection (95% approximate credible interval: 1.69–1.86), and the Holm-adjusted GEE result remained p < .001. A 1,000-point increase in absolute evaluation-score change was associated with an odds ratio of 0.91. The association between lower policy and branching remained after excluding the first move of each PV wOR 1.80, 1.72–1.89; unadjusted and Holm-adjusted GEE p < .001), supporting robustness within the selected PVs rather than establishing generalizability beyond the selected positions. It also remained positive in all leave-one-question-out analyses (OR range: 1.73–1.81). Across these data, truncation and branching showed different association patterns, and lower skill-adjusted-AI policy was consistently associated with candidate branching points.

  2. Analysis of AI Game Outcome Distributions and Placement Features for 1,440 Point-Symmetric Initial Positions in 66 Shogi

    Yoshimasa Yamaguchi, Takeshi Ito

    Affiliations: The University of Electro-Communications, Japan

    Keywords: 66 Shogi, game AI, outcome distribution, NNUE, self-play, point-symmetric initial positions

    Paper #174 · Computer Games & Game AI

    Abstract

    66 Shogi is a 6×6 shogi variant with a free-placement phase. We played 200 games for each of 1,440 point-symmetric initial positions using the same 100M NNUE model on both sides at 300 ms/move and analyzed the observed four-category outcome distributions and their descriptive relationships with placement features. Across 288,000 games, first-player wins, second-player wins, repetition draws (sennichite), and max_ply-unresolved games accounted for 54.60%, 33.99%, 9.70%, and 1.71%, respectively, with substantial variation among positions. We then reevaluated all 1,440 positions at 372,000 nodes/move, running two games per position with the execution labels swapped between sides. For every position, the two games produced identical move sequences, while the fixed-nodes reference outcome agreed with the modal category under the 300 ms condition in 56.3% of positions. Therefore, the proportions from the 200 repeated games per position are interpreted not as position-specific outcome probabilities, but as observed outcome distributions that may reflect variation in search volume under a fixed AI and real-time search condition. Relationships with placement features are likewise treated only as descriptive associations that include dependencies among piece placements.

  3. Affective Representations for Conversation Derailment Forecasting

    Retnani Latifah, Yi-Shin Chen

    Affiliations: National Tsing Hua University, Taiwan

    Keywords: forecasting conversation derailment, affective signals, forecasting horizon

    Paper #70 · Data Mining & Forecasting

    Abstract

    Online conversations can deteriorate from civil discussion into personal attacks, motivating methods that forecast derailment before explicit breakdown occurs. However, it remains unclear whether different representations of pre-breakdown affect exhibit different forecasting behavior, particularly regarding when predictions first become correct and when they stabilize as additional turns become available. Each observed turn is represented using valence, arousal, and toxicity, with inter-turn time gaps retained as an auxiliary interaction signal. Two representations are compared: a Sequential representation that preserves turn-level affective progression and a Global Summary representation that captures accumulated affective state and trends. To examine forecasting behavior across conversation prefixes, we introduce First-Hit Horizon (FHH) and Stable Horizon (SH) to distinguish the earliest correct prediction from the earliest point at which correct predictions remain stable. On CGA-WTP, affective models outperform the controlled text baselines in F1 for the derailing class, with Global Summary exceeding the strongest controlled text baseline by 9.2 points. Across conversation prefixes, Sequential has an earlier mean FHH, whereas Global Summary has an earlier mean SH. Controlled lexical experiments further show significant gains when affective information is added to text-only classifiers, while adding lexical information to the affective predictor does not significantly improve class-1 F1. These findings suggest that different affective forecasting formulations can exhibit differences not only in final performance but also in the timing and stability of correct predictions.

  4. Disentangling Heterogeneous Traffic Dynamics for Multi-Step Traffic Forecasting via Adaptive Spectral Decomposition

    Zijun Huang1, Chenrui Fu1, Wenhao Wang1, Xiaochuan Gou2, Chih-Chieh Hung3, Guanyao Li1

    Affiliations: 1Beijing Normal-Hong Kong Baptist University, China 2Dalian Maritime University, China 3National Chung Hsing University, Taiwan

    Keywords: Traffic forecasting, Frequency-domain learning, Spectral decomposition

    Paper #135 · Data Mining & Forecasting

    Abstract

    Accurate multi-step traffic forecasting remains challenging because observed traffic signals contain heterogeneous temporal dynamics with different characteristics and levels of predictability. Existing approaches typically model these dynamics within a unified representation or rely on predefined decomposition rules, which may limit their ability to flexibly separate persistent patterns from rapidly varying fluctuations. To address this issue, we propose the Adaptive Decomposition Network (ADNet), a component-specific forecasting framework that adaptively disentangles traffic dynamics into dominant and residual components. ADNet introduces a learnable complementary spectral decomposition mechanism that determines the contribution of each frequency bin to the two components. Unlike hard frequency partitioning, every frequency bin can contribute to both components with different learned proportions, allowing the decomposition to be optimized jointly with the forecasting objective. The reconstructed components are then modeled by two dedicated spatiotemporal forecasting branches, and their predictions are integrated to generate the final multi-step forecast. Experiments on the Alameda and Orange regions of the TraffiDent dataset show that ADNet achieves the best performance in 20 of the 24 reported region--horizon--metric comparisons, with particularly clear gains at longer forecasting horizons. Capacity-controlled ablation experiments further show that the learnable decomposition substantially outperforms a fixed decomposition and provides additional improvements beyond the dual-branch architecture alone. These results demonstrate the effectiveness of adaptive decomposition and component-specific modeling for multi-step traffic forecasting.

  5. Historical Satellite Embedding Trajectories Provide Predictive Information About the Next Observed Embedding State

    Vinicius Buri Lux

    Affiliations: LuxVerso Research Initiative, Brazil

    Keywords: Satellite Foundation Models, AlphaEarth, Geospatial Embeddings, Temporal Prediction, Trajectory Representation, Remote Sensing, Earth Observation, K-Nearest Neighbors

    Paper #204 · Computer Vision & Multimodal

    Abstract

    Satellite foundation models provide dense representations of Earth’s surface that can be compared across time, but an open empirical question is whether the historical trajectory of such representations contains information useful for predicting the next observed embedding state. We investigate this question using 887 spatial trajectories constructed from annual 64-dimensional AlphaEarth Foundation Model embeddings across six heterogeneous territorial phenomena between 2018 and 2024. Each complete trajectory contains seven annual states, yielding a 448-dimensional representation. We evaluate a deliberately simple temporal prediction protocol in which a distance-weighted k-nearest-neighbor regressor predicts the next 64-dimensional embedding state from the available historical trajectory and is compared against a persistence baseline. Predictions are evaluated for 2022, 2023, and 2024 using trajectory-level 80/20 random splits with seed 42, as well as a leave-one-trajectory-out procedure for 2024.

    Across all six ecosystems, the reproduced experiments yield positive gains over persistence at all three prediction horizons. Gains range from 14.50% to 84.20% for 2022, from 28.80% to 83.34% for 2023, and from 24.36% to 83.66% for 2024. The reproduction audit additionally resolved a historical discrepancy in the Carajás leave-one-out result: 51.60% is the correct gain against the 2023 persistence state, whereas 73.34% is generated by a historical comparative implementation whose baseline indexing selects the 2022 state. The KNN prediction error is identical in both cases.

    The evidence supports a narrow empirical conclusion: under the tested protocol, historical AlphaEarth embedding trajectories contain predictive information about the next observed embedding state beyond a persistence baseline. The experiment does not establish superiority over snapshot-only predictors, memory in a cognitive or physical sense, causal territorial dynamics, universal dynamics, or direct prediction of physical territorial change.

  6. Changes in Self-Perceptions of Detecting AI-Generated News Comments Across Discrimination and Generation Tasks: A Preliminary Study

    Nanase Mogi, Mitsunori Matsushita

    Affiliations: Kansai University, Japan

    Keywords: online news comments, active inoculation, AI-generated text, authorship judgment, human-AI interaction

    Paper #138 · AI for Health

    Abstract

    Online news comments can affect how readers perceive public opinion. Large language models (LLMs) can generate comments that vary in stance, emotion, and tone, although readers may rely on these features when judging authorship. We examined how authorship judgments and subjective perceptions changed across an experimental sequence combining discrimination tasks with an LLM comment-generation task. Participants completed two discrimination tasks separated by a two-stage generation task. Discrimination sensitivity did not differ significantly between the tasks, whereas the response criterion shifted toward AI classifications. Confidence in distinguishing AI-generated comments decreased, while participants perceived AI-generated opinions as more prevalent after the task sequence. Their perception that comment sections reflect public opinion did not change significantly. LLM-generated comments with restrained emotion and a polite tone were more likely to be classified as AI-generated than comments with stronger emotion and a casual tone. However, this relationship did not differ significantly between the two discrimination tasks. Taken together, the results indicate a shift in response criterion rather than improved discrimination sensitivity.

  7. Evidential Deep Learning with conditional entropy for glaucoma detection

    Hai Siong Tan1, Kuancheng Wang2

    Affiliations: 1Gryphon Center for Artificial Intelligence and Theoretical Sciences, Singapore 2University of California, San Diego, USA

    Keywords: Uncertainty Quantification, Glaucoma Detection

    Paper #129 · AI for Health

    Abstract

    We propose a novel conditional entropy function as a basis for quantifying predictive uncertainty in Evidential Deep Learning (EDL) for glaucoma detection from retinal fundus images. Using the EyePACS-AIROGS-light-V2 and RIM-ONE-DL datasets for validation, we found that our proposed EDL model regularized by conditional entropy function produced uncertainty estimates with substantially lower calibration errors than Deep Ensembles, MC Dropout, post-hoc calibration and the conventional EDL framework based on Dempster uncertainty. To further probe our models' interpretability, we analyzed Grad-CAM heatmaps using a focus index representing spatial concentration. Compared with the other uncertainty quantification methods, EDL models exhibited greater separation between the index distributions of correctly and incorrectly classified fundus images. In particular, false negatives were associated with localized Grad-CAM activations that were displaced from the optic disc, consistent with its established clinical importance in glaucoma assessment. Overall, our findings suggest that our proposed EDL framework for glaucoma detection provides not only enhanced uncertainty calibration but also admits a more physiologically consistent interpretability.

  8. Automatic Generation of Open-Vocabulary Descriptive Tags for Anime Cut Scenes Using Vision-Language Models and Syntactic Parsing

    Junjie Shan, Jianrui Yan, Yoko Nishihara, Yangdi Ni, Zhenzhong Duan

    Affiliations: Ritsumeikan University, Japan

    Keywords: Anime scene caption, Open-vocabulary image tagging, Vision–language model, Image captioning, Syntactic parsing

    Paper #57 · Computer Vision & Multimodal

    Abstract

    Tags that describe the visual content of anime cut scenes are a key device for retrieving a desired scene from ever-growing collections of anime videos. Existing anime taggers, however, cast tagging as multilabel classification over a predefined vocabulary, and therefore cannot express content outside that vocabulary, including object attributes and relations between objects. This paper proposes a method that automatically generates open-vocabulary descriptive tags for anime cut scenes by combining Vision–Language Models (VLMs) with syntactic parsing. The method samples the first, middle, and last frames of each cut scene, prompts a VLM to produce objective English captions, and extracts tags by matching the dependency parses of the captions against eight syntactic patterns distilled from the tag taxonomy of a fixed-vocabulary tagger. Noise tags are suppressed by stop-word rules and a manually built blocklist (87.1% noise removal on held-out scenes with no false deletions). In experiments on 1,000 cut scenes with two VLMs (InternVL3 and JoyCaption), each under deterministic and stochastic decoding, the method produced up to 28,085 unique tags—13.4 times the 2,101 tags of the fixed-vocabulary baseline DeepDanbooru, and no fewer than 7,586 (3.6 times) in any of the four configurations—with markedly higher proportions of attribute (adj+noun) and relation (noun+prep+noun) expressions. Embedding-based clustering further shows that the generated tags spread over as many as 215 semantic clusters, versus 21 for the baseline, while their principal clusters remain semantically aligned with the baseline’s core visual concepts (mean cosine similarity 0.876): the method extends both the vocabulary and the expressive forms of scene tags while preserving compatibility with existing taggers.

DO2 · – · Room B · 2F Lijing Hall B

Domestic Oral Session 2

Topics: AI for HealthLLMs & NLP

Session chair: Prof. Meng-Luen Wu (Tamkang University) · 7 papers

  1. Gauge or Process? Attributing Location Shifts at a Single Inspection Station Using Bridging Re-inspection Pairs

    Hubert Huang

    Affiliations: National Taiwan University, Taiwan

    Keywords: measurement system analysis, statistical process control, change-point attribution, equivalence testing, smart manufacturing.

    Paper #139 · AI for Health

    Abstract

    Inspection logs often contain only an item identifier, a measured value, a timestamp and the specification limits. When such a series shifts, engineers must decide whether to recalibrate the gauge or to adjust the process, yet from single-measurement data the two explanations are indistinguishable. When the same item is measured before and after a change point, the difference between the two readings cancels its fixed true value, and production lines naturally generate such re-inspections. Bridging-Pair Attribution (BPA) adjusts for their selection bias with a pre-change baseline, decomposes the observed shift into gauge and process contributions against an equivalence band to give a mutually exclusive four-way verdict, and requests a noise-adaptive budget of random re- measurements when evidence is insufficient. In 1,400 simulated runs no cross-attribution was observed and the inconclusive rate fell from 90% to 8–10% once the budget was met; on the real SECOM series the gauge contribution is recovered to within about 0.01h.

  2. A Compact and Biologically Reproducible Transcriptomic Signature for Cross Cohort LUAD and LUSC Classification

    Muhammad Hussain1, Najeeb Ullah2, Hussain Abbas3, Musawir Hussain2, Hassan Abbas2, Quang Thai Ho1, Iqrar Hussain4

    Affiliations: 1Yuan Ze University, Taiwan 2National Taipei University, Taiwan 3National Taipei University of Nursing and Health Sciences, Taiwan 4National Sun Yat-sen University, Taiwan

    Keywords: LUAD · LUSC · transcriptomics · external validation · gene signature · machine learning

    Paper #133 · AI for Health

    Abstract

    Accurate molecular classification of lung adenocarcinoma (LUAD) and lung squamous cell carcinoma (LUSC) requires models that generalize across independent cohorts while retaining stable and biologically reproducible features. This study evaluated a transcriptomic classification framework using GSE30219 as the discovery cohort (167 tumors) and GSE50081 as the independent external cohort (171 tumors). After preprocessing, 21,752 shared genes were retained and transformed to within sample percentile ranks. Seven classifier families were evaluated using fold local ANOVA feature ranking and repeated stratified 5 fold cross validation. The selected 20 gene MLP achieved a discovery ROC AUC of 0.9983 and an external ROC AUC of 0.9010 (95% CI: 0.8322 to 0.9601), with balanced accuracy of 0.8833, F1 score of 0.7917, and MCC of 0.7191. Nineteen of the 20 genes showed consistent effect directions across cohorts, and 18 remained significant after Benjamini Hochberg correction in the external cohort. Enrichment analysis identified significant estrogen response and membrane lipid catabolic processes. These findings indicate good cross-cohort discrimination, while external LUSC precision (0.7170) and PR AUC (0.7735) highlight limitations in minority-class prediction and the importance of independent biological validation.

  3. 單一模型跨規格之可重構智慧面相位即時生成

    顏俊儀, 劉立頌, 林士程, 陳佑誠, 黃信睿

    Affiliations: 國立中正大學電機工程研究所

    Keywords: 可重構智慧面, 條件式生成器, 特徵線性調變, 啟發式神經網路混合訓練, 深度學習

    Paper #25 · AI for Health

    Abstract

    針對第六代行動通訊 (6G) 環境下可重構智慧面 (Reconfigurable Intelligent Surface, RIS) 所要求之即時、動態與多規格相位生成需求,本研究提出一套基於條件式生成方法之深度學習框架,命名為條件式生成器 (Condition-Based Generator),用以即時生成各種客製化角度規格之 1-bit 相位分布。本方法以入射角與反射角組合作為動態輸入,並於網路中導入特徵線性調變 (Feature-wise Linear Modulation, FiLM) 機制,使單一模型得以於同一組權重內承載大量角度規格之相位映射,克服既有方法須逐規格重新訓練之限制。於訓練流程中,本研究以陣列因子公式建構物理引導損失,將 Gumbel-Sigmoid 量化整合為單階段端到端流程,並參考硬體層之隨機相位預編碼概念,於量化前疊加固定隨機遮罩以抑制 1-bit 量化所致之鏡像波束;針對多波束高自由度場景,另提出啟發式神經網路混合訓練機制以突破收斂瓶頸。實驗以陣列因子公式與 Ansys HFSS 電磁模擬評估生成品質,並將模型部署至 NVIDIA Jetson AGX Orin 邊緣運算裝置量測即時推論能力。結果顯示,單一模型可涵蓋多種單波束與多波束規格並展現良好泛化,於邊緣裝置維持毫秒等級推論速度,且電磁模擬與公式解之主波束方向及增益一致。

  4. 基於跨模態知識蒸餾之輕量化腕戴式壓力辨識

    翁政雄, 于永庭 (Yu-Yung-Ting), 林易叡 (Lin-Yi-Rui), 陳盈智 (Ying Zhi Chen), 李文愷 (Li-Wen-Kai), 洪煜傑 (Yu Chieh Hung), 江承紘 (Chiang-Cheng-Hong)

    Affiliations: 國立彰化師範大學資訊管理系

    Keywords: 壓力辨識, 穿戴式感測, 知識蒸餾, 跨模態學習, WESAD

    Paper #119 · AI for Health

    Abstract

    穿戴式生理訊號可提供連續且客觀的壓力狀態資訊,然而腕戴式裝置受限於感測通道與訊號品質,其辨識效能通常低於具有較完整生理資訊之胸戴式裝置。本研究提出一套基於跨模態知識蒸餾之腕戴式壓力辨識方法,利用 WESAD多模態生理資料建立教師—學生架構。首先,以NeuroKit2萃取ECG、BVP與EDA等生理訊號特徵,並利用胸部與手腕多模態資訊訓練教師模型;其後,透過知識蒸餾將教師模型之機率分布資訊傳遞至僅使用手腕訊號之輕量學生模型。實驗採留一受試者交叉驗證(Leave-One-Subject-Out,LOSO),並以Macro-F1作為主要評估指標。結果顯示,最佳教師模型 GRU之Macro-F1為0.8949;未使用知識蒸餾之腕戴式GRU學生模型為0.7175,而導入知識蒸餾後提升至0.8743,增加0.1568。結果顯示,跨模態知識蒸餾能有效縮小僅使用腕戴式訊號時所造成的辨識效能落差,並在降低感測資訊與模型複雜度的情況下維持接近多模態教師模型之壓力辨識效能。

  5. 兼顧高敏感度辨識與病人內檢索之多模態皮膚病灶風險排序

    翁政雄1, 楊惟麟1, 施丞澤2

    Affiliations: 1國立彰化師範大學資訊管理系 2國立彰化師範大學資訊工程學系

    Keywords: ISIC 2024, 皮膚癌檢測, 多模態學習, 風險排序, 多模態表徵

    Paper #101 · AI for Health

    Abstract

    皮膚病灶篩檢除需辨識高風險病灶,也需將惡性病灶優先排入病人內前段候選。本研究建立以完整配置為單位的多模態風險排序選擇流程,先篩選具融合增益的模型配對,再聯合比較由預測與病人內排序、局部近鄰表徵及不同融合模型。Random Forest–DINOv2 搭配局部近鄰表徵與注意力融合取得最高 pAUC 0.170319;搭配基本排序表徵與 Gated MLP 則取得最高 Top-15 命中 294。結果顯示,聯合配置評估可辨識不同排序目標下較適合的多模態配置,且增加表徵層級並不必然帶來一致的效能提升。

  6. 基於模型微調式醫療命名實體識別與句子編碼之自動化胃腸科護理問診系統

    林鈺耀 (Yu-Yao Lin)1, 陳履恒 (Lieu-Hen Chen)1, 洪晧銘 (Hao-Ming Hung)1, 吳曉光 (Hsiao-Kuang Wu)2

    Affiliations: 1國立暨南國際大學資訊工程學系 2國立中央大學資訊工程學系

    Keywords: 胃腸科問診, 醫療命名實體識別, 句子編碼器, 臨床摘要, 臺灣醫療

    Paper #121 · AI for Health

    Abstract

    臺灣問診語句常包含口語及地區性醫療用語,使通用模型難以同時判斷回答是否切題並擷取結構化資訊。本研究針對臺灣繁體中文胃腸科問診情境,建置並評估兩個核心模組:以中文 RoBERTa 全詞遮罩模型微調的 Twclinical NER 醫療命名實體識別模型,以及以 Triplet Loss 微調的多語句子編碼器。NER 由研究者依五類實體規範完成人工標記並自行複核,資料包含 1,550 筆訓練、380 筆開發及 120 筆測試語句;依開發集選定的模型,在測試集取得 0.8526 Strict Span F1。句子編碼器使用 922 筆真實胃腸科問診回答作為正例,每筆搭配 5 個跨步驟難負例,共形成 4,610 筆 triplet;於 112 組正負回答配對取得 0.9295 ROC-AUC,並於固定門檻 0.35 下取得 0.8795 Balanced Accuracy。相較未微調基準,Balanced Accuracy 提升 16.07 個百分點,ROC-AUC 提升 15.68 個百分點。另以相同步驟分布及資料規模建立樣板合成訓練資料作為對照後,使用真實問診回答訓練的模型仍分別高出 4.46 及 4.25 個百分點。系統最後使用 Gemini 生成臨床摘要,並參考 G-Eval 以 GPT-4o-mini 進行品質評估;在 20 個問診情境中,AI 評分與護理系學生評分的 Spearman 相關係數為 0.868(p<0.0001)。結果支持真實胃腸科問診回答與跨步驟難負例有助於提升回答切題判斷能力,並完成從問診資料到臨床摘要的整合流程。

  7. 隨拍、隨比、隨時學, AI 客語隨身教:結合電腦視覺與聲學評測之客語情境教學系統實作

    吳怡臻1, 黃璿羽1, 梁易軒1, 張育倫2, 林守毅2, 李俊賢3

    Affiliations: 1國立中央大學客家語文暨社會科學學系 2國立中央大學企業管理學系 3國立中央大學資訊管理學系

    Keywords: AI 語音評測, 情境化語言學習, 客語數位教學, 電腦視覺

    Paper #58 · LLMs & NLP

    Abstract

    本研究提出「所見即所學」理念,開發「AI 客語隨身教」行動學習系統。學生拍照後,系統以 Gemini 為主、YOLOv11 為備援辨識物件,以 Tesseract 與 PaddleOCR 擷取文字,再經客委會四縣腔 API 取得客語詞彙、拼音與合成語音,並由大型語言模型生成中文例句後轉譯為客語。發音練習以梅爾頻率倒頻譜係數(MFCC)結合動態時間校正(DTW)計算與標準音之相似度,作為練習回饋而非精確之發音診斷。於正式環境中,三種辨識模式各 10 張測試照片均正確辨識,平均延遲 14.6 至 24.1 秒,48 個測試詞彙亦皆成功轉換為客語詞彙、拼音與語音。

PS2 · – · Poster Area · 2F Liquan Hall exhibition area

Poster Session 2 (Domestic)

Topics: AI for HealthData Mining & ForecastingComputer Games & Game AIAI Agents & RAG

Session chair: Jing-Tian Sung (Institute for Information Industry) · 12 papers

  • BoardDP-01

    Rank-Conditioned Multimodal Move Prediction in Go: Fine-Tuning on Ten Skill Levels

    Yu-Shan Yen1, Shi-Jim Yen2

    Affiliations: 1National Taiwan Normal University, Taiwan 2National Dong Hwa University, Taiwan

    Keywords: Go, move prediction, skill imitation, multimodal features, deep learning

    Paper #183 · Computer Games & Game AI

    Abstract

    We study rank-conditioned next-move prediction on the ten skill levels of the AI CUP 2026 Go training set (A–D = 1–3, 4–6, 7–9 and 10–12 kyu; 1d–6d). The nested-residual network of an open-source AICUP 2023 entry is extended from 17 to 30 input planes with ladder, 10-way rank and move-number features, initialized from its pretrained dan model in a function-preserving way, and fine-tuned on 10.6M positions. On 2.21M test positions from players unseen in training, the rank-aware model reaches 55.60% top-1 and 86.33% top-5 accuracy, 0.22 points above an otherwise identical control without rank planes (95% CI [0.19, 0.24]). No level gets worse, and the gain is concentrated at both ends of the rank axis. A counterfactual rank-swap test shows that, although one-hot labels carry no order, the model recovers the true order A > B > C > D.

  • BoardDP-02

    基於閘控路徑規劃網路之無人機路徑規劃方法

    黃彥皓, 陳冠佑, 陳柏儒

    Affiliations: 國立臺東大學綠能與資訊科技學系

    Keywords: 無人機, 路徑規劃, GPPN

    Paper #144 · Data Mining & Forecasting

    Abstract

    本研究探討閘控路徑規劃網路(GPPN)應用於無人機局部路徑規劃的可行性。研究使用八方向 Dijkstra 演算法產生教師價值圖,以監督式學習訓練 GPPN,並於 10 張未參與訓練的 BEV 地圖上測試 3,000 組地圖與目標組合。實驗結果顯示,預測價值圖與教師價值圖的平均皮爾森相關係數為0.9147,任務成功率與路徑合法率皆達 100%,平均路徑成本比為 1.0001。GPPN 整體規劃時間為 213.99 毫秒,Dijkstra 則為 133.08 毫秒。結果顯示,GPPN 雖未具速度優勢,仍能在未見地圖中產生接近最佳解的有效路徑。

  • BoardDP-03

    A Modular Autonomous Driving Framework with DQN-Based High-Level Decision Making

    Yan-Han Chen1, Wei-Chun Hsu1, Ying-Jen Chen2, Li Cho1

    Affiliations: 1Tatung University, Taiwan 2Yuan Ze University, Taiwan

    Keywords: autonomous driving, Dueling Double DQN, CARLA, lane selection, braking arbitration, recovery

    Paper #191 · Data Mining & Forecasting

    Abstract

    In this paper, we have used a modular driving system in CARLA for lane selection and braking. Dueling Double DQN (D3QN) selects lanes using 13 traffic features, a deterministic executor carries out the decision, and a separate controller handles braking. Recovery can reconsider an unfinished lane change after braking. We have evaluated navigation, braking, and recovery separately. In 200 Town05 navigation cases, our system achieved 200 contact-free arrivals, compared with 13 for a Safe Navigation-based implementation. In 200 Town06 static braking cases at 20–90 km/h, the extended-speed model achieved 200 safe stops, compared with 99 for the original model. In 200 paired repetitions of one fixed blockage configuration, recovery enabled resulted in 200 arrivals, while recovery disabled resulted in none. The framework completed the tested tasks and handled the stopped-maneuver condition, although the comparisons did not isolate the route learner.

    Keywords: autonomous driving, Dueling Double DQN, CARLA, lane selection, braking arbitration, recovery

  • BoardDP-04

    結合空間距離與建設生命週期特徵之房價溢價預測:基於CatBoost之實證研究

    吳常熙 (Chang-Hsi Wu), 廖鈞義 (Jun-Yi Liao)

    Affiliations: 龍華科技大學電子工程系

    Keywords: CatBoost, 相對溢價率, 房價預測, 空間外部性, 重大建設生命週期

    Paper #84 · Data Mining & Forecasting

    Abstract

    重大建設與住宅價格之關聯可能隨空間距離及發展階段而變化。本研究以新北市住宅交易為基礎,依行政區、建物型態及坪數建立歷史價格基準,以相對溢價率為預測目標,結合捷運距離衰減、商場 Push-Pull 及建設生命週期特徵建立 CatBoost 模型。2024-2025 年共 30,007 筆時間外測試結果顯示,房價 RMSE 為 6.8989 萬元/坪、R²為 0.7857,較僅使用住宅屬性之模型降低 13.87% RMSE。SHAP 分析顯示,捷運距離貢獻呈遞減趨勢,商場則呈現非單調駝峰型態;生命週期特徵僅提供小幅預測增益。研究結果反映模型預測關聯,不代表直接因果效果。

  • BoardDP-05

    A Study on Prompt Design in Generative AI for Buddhist Short Videos

    Rou-Jen Lu, Meng-Chien Shih, Shi-Jim Yen

    Affiliations: National Dong Hwa University, Taiwan

    Keywords: Generative AI, Prompt Design, Image Generation, Animation Generation

    Paper #147 · AI for Health

    Abstract

    Buddhist stories contain rich wisdom and educational value, but their abstract language can make them difficult to understand. This study uses generative AI to transform Buddhist stories into animations. ChatGPT handles text segmentation, character features, and prompt generation, while Qwen maintains character consistency and Wan 2.2 converts images into animations. The results show that generative AI can support the animation of Buddhist stories.

  • BoardDP-06

    From Approval to Execution: A Verifiable Governance Continuity Model for Enterprise AI Agents

    Austin Hsieh

    Affiliations: Independent Researcher, Taiwan

    Keywords: AI agents, governance continuity, authorization, governance events, evidence qualification

    Paper #55 · AI Agents & RAG

    Abstract

    Enterprise AI agents require evidence that distinguishes approval from execution and observed effects. We propose a process-to-execution governance continuity model with five non-equivalent stages: Decision, Authorization, Dispatch, Runtime, and Outcome. Governance Event Core (GEC) v0.1 supplies an implementation-neutral event representation and semantic qualification contract. An OpenCode vocabulary case classifies seven claims as three PROVEN, three CONTRADICTED, and one NOT_OBSERVED. Paired isolated executions distinguish matching from mismatched request authorization. Post-submission fixtures address context drift, observation completeness, and five-stage control flow while preserving rejected mappings and post-effect failures. Seven workflow classifications replay consistently, but only five meet all original expectations. The contribution is bounded claim qualification over governance evidence, not a production authorization or enforcement system. The study does not establish cross-platform interoperability, scalability, or general agent safety.

  • BoardDP-07

    An Offline On-Device Method for Citrus Pest and Disease Recognition with Grounded Diagnosis

    Cheng-Yan Cai, Yuan-Chin Tu, You-Jia Huang, Chen-En Chien, Huan-Yu Chen

    Affiliations: National Taichung University of Science and Technology, Taiwan

    Keywords: citrus pest and disease, object detection, edge AI, retrieval-augmented generation, small language model

    Paper #163 · AI for Health

    Abstract

    This paper presents a fully on-device method for citrus pest and disease recognition with grounded diagnosis, combining lightweight object detection, retrieval-augmented generation (RAG), a quantized small language model, and a safety guardrail. On a nine-class Ministry of Agriculture dataset (7,264/401/401 training/validation/test images), the detector achieves a test mAP50 of 0.861 and an mAP50–95 of 0.641; the eight classes unaffected by an annotation-rule change reach a pooled mean AP50 of 0.8508. With 33 atomic knowledge chunks and adaptive N-gram retrieval, a 0.5B-parameter model reaches 85.05% Faithfulness, 100.0% Context Precision, and 93.06% Context Recall on a 40-question benchmark and defends against all four boundary questions. A five-stage ablation shows that atomic chunking and the guardrail contribute most. The mean latency per question on a Samsung Galaxy A33 is 29.98 s. Reliable on-device agricultural AI depends on annotation consistency, generalization, retrieval evidence, and safety boundaries rather than a single accuracy score.

  • BoardDP-08

    個人化雙耳節拍音樂誘導睡眠

    蘇敬堯, 陳思穎, 林和宇, 謝宗澔

    Affiliations: 東海大學資訊工程學系

    Keywords: 雙耳節拍binaural beats, 睡眠分期sleep staging, 腦電圖electroencephalography, 音樂治療music therapy, 睡眠誘導sleep induction

    Paper #118 · AI for Health

    Abstract

    失眠已成為現代社會普遍的健康問題,長期藥物治療伴隨依賴性與副作用等疑慮。雙耳節拍(Binaural Beats, BB)為一種非侵入性介入手段,可改善睡眠品質,然而其神經夾帶效應強弱因人而異,為既有研究尚未解決之缺口。本研究提出個人化雙耳節拍音樂誘導睡眠系統,透過分析腦電圖自動篩選對使用者有效之BB刺激組合,並結合自動睡眠分期即時判定誘導效果是否持續,若失效則自動切換下一組合,系統包含BB自動篩選、睡眠分期、入睡品質評估三部分。實驗招募3位受試者,結果顯示有效BB組合具明顯個體差異,其中兩組合對所有受試者皆有效,另五組合僅對個別受試者有效;睡眠分期模型測試準確率達0.89以上。受試者聆聽個人化BB音樂後入睡時間較雙和醫院資料集為短。本研究初步驗證個人化策略可提升睡眠誘導效果,未來將擴大樣本進一步驗證。 Insomnia has become a prevalent health issue in modern society, and long-term pharmacological treatment raises concerns such as dependency and side effects. Binaural beats (BB) represent a non-invasive intervention that can improve sleep quality; however, the strength of their neural entrainment effect varies across individuals, a gap that existing research has yet to address. This study proposes a personalized binaural-beat-induced sleep system that automatically screens BB stimulus combinations effective for each user by analyzing electroencephalography (EEG) signals, and combines this with real-time automatic sleep staging to determine whether the induction effect persists—automatically switching to the next combination if it fails. The system consists of three components: automatic BB screening, sleep staging, and sleep onset time (SOT) assessment. Three subjects were recruited for the experiment, and the results showed marked individual differences in effective BB combinations: two combinations were effective for all subjects, while five combinations were effective for only specific individuals. The sleep staging model achieved a test accuracy above 0.89. Subjects exhibited a shorter sleep onset time (SOT) after listening to personalized BB music compared to sleep onset times recorded in a dataset from Shuang Ho Hospital. This study provides preliminary validation that a personalized strategy can enhance sleep induction effectiveness; future work will expand the sample size for further validation.

  • BoardDP-09

    Effects of Aggressive Front-End Downsampling on Prediction Concentration in CNN-Based Radiographic Grading of Mandibular Third Molar Surgical Difficulty

    Tsung-Yu Wu1, Bo-Gang Chen1, Chia-Yu Chiu1, Tzer-En Nee1, Jyh-Kwei CHEN2

    Affiliations: 1Chang Gung University, Taiwan 2Linkou Chang Gung Memorial Hospital, Taiwan

    Keywords: mandibular third molar, surgical difficulty grading, panoramic radiography, convolutional neural network, early downsampling, prediction collapse

    Paper #76 · AI for Health

    Abstract

    Convolutional neural networks commonly reduce spatial resolution at the front end, but the effect of aggressive early downsampling on radiographic grading of mandibular third molar surgical difficulty remains unclear. We investigated this effect using 682 panoramic radiograph samples. Under the same patient-level split and training protocol, two opposite-direction front-end interventions were evaluated: the aggressive ResNet-style stem was replaced by a milder staged design in ResNet50-GN, while the same aggressive design was introduced into VGG16. Prediction concentration was quantified using the majority prediction rate (MPR), where MPR = 1.0 denotes complete single-class collapse. In the ResNet pair, milder downsampling reduced Angle MPR from 1.0000 to 0.8472 and Ramus MPR from 0.8472 to 0.7917. In the reverse VGG intervention, aggressive downsampling increased Angle MPR from 0.7222 to 1.0000 and Ramus MPR from 0.7778 to 1.0000, resulting in complete single-class predictions, whereas Depth showed a different response. These paired results indicate that aggressive early downsampling can substantially alter prediction concentration in mandibular third molar radiographic grading and that its effect is task dependent, highlighting front-end spatial compression as an important architectural consideration.

  • BoardDP-10

    基於全同態加密並結合 HMAC 完整性驗證與密文域可逆資訊隱藏之隱私保護心臟病風險預測系統

    沈奕昕 (Shen Yi Hsin), 葉采瑩 (Yeh Tsai Ying), 戴婕伊, 李哲瑋 (Che-Wei Lee)

    Affiliations: 國立高雄師範大學軟體工程與管理學系

    Keywords: 全同態加密, CKKS, 心臟病預測, 完整性驗證, 可逆資訊隱藏

    Paper #78 · AI for Health

    Abstract

    健檢資料屬高度敏感之個人隱私,於雲端進行心臟病風險預測時,明文外洩風險極高。本系統提出一套以全同態加密(FHE)為核心之隱私保護心臟病風險預測系統,採用 TenSEAL 函式庫實作CKKS 加密方案,使伺服器於不接觸明文之情形下完成羅吉斯迴歸心臟病風險推論。本 研 究以Framingham Heart Study 資料集訓練,選用八項臨床特徵,測試集 AUC 達 0.7371,準確率 82.79%,惟因類別不平衡不宜作為主要目標。鑑於標準 FHE僅保證機密性,本研究進一步整合 HMAC-SHA256完整性驗證與密文域可逆資訊隱藏技術,使系統同時具備機密性、完整性與可追溯性,實驗證實三面向皆具可行性與有效性。

  • BoardDP-11

    WGAN資料增強對常見機器學習與深度學習模型 於EEG神經退化性疾病分類效能之影響評估

    鐘培嘉, 曾金宏, 蘇奕安, 陳榮銘

    Affiliations: 國立臺南大學資訊工程學系

    Keywords: 腦電圖, 神經退化性疾病分類, 生成對抗網路, WGAN, 資料增強

    Paper #151 · AI for Health

    Abstract

    本研究探討Wasserstein生成對抗網路(WGAN)資料增強應用於腦電圖(EEG)神經退化性疾病診斷之效果,並系統性比較常見的機器學習與深度學習模型在資料增強前後的分類效能。實驗採用公開EEG資料集(Dataset B),涵蓋阿茲海默症(AD)、輕度認知障礙(MCI)及正常認知狀態(CN)三類,原始資料存在嚴重類別不平衡問題(AD:MCI:CN≈33:4:2)。本研究以Progressive WGAN with Gradient Penalty生成合成EEG訊號,將各類別訓練資料補足至4,000筆,並評估RF、SVM、1D CNN、2D CNN及ViT五種分類模型在資料增強前後的表現。實驗結果顯示,WGAN生成資料在有效頻段內與真實EEG訊號具有高度吻合性;SVM與1D CNN改善最顯著,2D CNN與ViT則效能略有下滑或持平。整體而言,WGAN對因類別不平衡受限的模型具有顯著修復效果,但對效能已飽和的模型效益有限,MCI始終是最難辨識的類別。

  • BoardDP-12

    ERP 交易限制下 LLM Agent 失敗恢復與驗證

    吳書逸 (Shu-Yi Wu), 謝文川, 林欣瑾

    Affiliations: 國立高雄科技大學智慧商務系

    Keywords: LLM 代理, 失敗恢復, 代理評估, 企業資源規劃, 執行軌跡

    Paper #201 · AI Agents & RAG

    Abstract

    企業資源規劃系統(Enterprise Resource Planning, ERP)中之 Agent 任務多以正常流程為評估情境,對於交易遭既有後端拒絕後之恢復過程仍缺乏觀察證據證明。為探討 LLM Agent 在 ERP 既有交易約束下之失敗恢復能力,本研究將單一 Agent 接入商用 ERP 系統,並以請購單、採購單與收貨單之採購流程作為研究情境;並進一步設計輸入與參數、商業規則、狀態依賴、跨文件一致性,以及工具與系統五種受控異常情境,每種異常情境進行三次驗證,共有 15 筆觀察。當異常發生後,Agent 僅依實際系統回饋自主查詢、修正與重新提交交易,且系統同步保存公開回應、工具操作、參數與後端回傳結果,並於實驗結束後回讀交易文件及其關聯,以驗證恢復結果。本研究結果發現,於15 筆觀察中,其中有 14 筆解除原始錯誤並完成採購流程,唯一未完成者,雖辨識出過帳日期問題並提出修正方向,卻未實際執行收貨。本研究結果顯示,在保留 ERP 商業規則與交易控制之條件下,Agent 可於多類異常後完成恢復,但問題辨識、處理決策與實際交易完成並不相同。因此,於評估企業流程中之 Agent 恢復能力時,除最終結果外,亦需整合可追溯之執行軌跡與後端狀態驗證。

–

IO3 · – · Room A · 2F Lijing Hall A

International Oral Session 3

Topics: Computer Vision & MultimodalAI for HealthAI Agents & RAG

Session chair: Prof. Shih-Chieh Tang (National Cheng Kung University) · 7 papers

  1. Quantum Computational Intelligence and Generative AI for Taiwanese-English-Japanese Language Co-Learning with STEM Education Applications

    Chang-Shing Lee1, Mei-Hui Wang1, Hsin-Wei Chen1, Chun-Chieh Tseng1, Pin-Yen Shen1, Naoyuki Kubota2, Chu-Kiong Loo3

    Affiliations: 1National University of Tainan, Taiwan 2Tokyo Metropolitan University, Japan 3University of Malaya, Malaysia

    Keywords: Quantum Computational Intelligence, Generative AI, Human–Machine Co-Learning, Fuzzy Inference, STEM Educational Applications

    Paper #213 · AI for Health

    Abstract

    This paper proposes a Quantum Computational Intelligence (QCI) and Gener-ative AI (GAI) framework for human–machine co-learning in Taiwanese-English-Japanese language education with STEM applications. The proposed framework integrates multilingual Automatic Speech Recognition (ASR), Large Language Models (LLMs), GAI, data and knowledge modeling, fuzzy inference, and QCI with software- and hardware-based learning tools. It sup-ports multilingual interactions among Taiwanese, English, and Japanese through speech recognition, language generation, translation, and multimodal AI applications. A progressive learning workflow guides young students from multimodal AI interaction and software with hardware-based data modeling to knowledge modeling, fuzzy inference modeling, fuzzy model optimization, quantum fuzzy inference engine (QFIE), and the generation of simulated quan-tum circuits using the QFIE. The framework was deployed and evaluated in four real-world educational settings in 2026: a Software Engineering course at the National University of Tainan (NUTN), Taiwan; an IEEE CIS Outreach Workshop in Maastricht, the Netherlands; a QCI&AI Science Camp in Kaohsiung, Taiwan; and an IEEE R10 EAC Workshop at Petrosains in Kuala Lumpur, Malaysia. These field studies involved learners with different educa-tional backgrounds and provided hands-on experiences in multilingual AI, GAI, QCI, and software–hardware integration. Evaluation results showed in-creased self-reported understanding after the learning activities and generally high levels of task completion. Participant feedback also indicated that ad-vanced QCI concepts, hardware operation and troubleshooting, and learning pace remained major challenges. The results suggest that the proposed frame-work can support Taiwanese-English-Japanese human–machine co-learning while providing progressive and hands-on learning experiences for QCI, GAI, and STEM education applications.

  2. Hierarchy-Guided Question Generation and Adaptive Testing for Agent Preference Shifts

    Jing-Tian Sung, Tsan-Yu Tsai, Daniel Liu

    Affiliations: Institute for Information Industry, Taiwan

    Keywords: Behavioral testing, Question generation, Knowledge graphs, Adaptive sampling

    Paper #215 · AI for Health

    Abstract

    Fixed test sets may miss preferences arising from an agent’s domain knowledge. We generate underspecified questions from parent and sibling concepts with source provenance, combine them with condition dimensions, and compare coded answers under a reference corpus and a corpus with an added preference statement. To search the resulting question pool under a limited budget, we study a graph-guided selector that first covers target concepts and contrasts condition values, then uses observed answer shifts to expand locally while continuing global exploration. We evaluate four adaptive selectors and no-feedback controls on fixed library, tax-filing, and dietary-guide pools of 111, 93, and 246 questions. In 30 seeded offline replays of frozen answer labels, the revised graph selector retrieved all observed shifts in every seed using 10% of the library and tax pools and 50% of the diet pool. Coverage alone matched the early result in the first two cases, whereas graph-local feedback improved diet discovery at larger budgets. These retrospective results show that structured, budgeted probing can reduce the number of questions needed to find observed changes; independent online validation remains necessary.

  3. Evidence-Grounded Dental Vision-Language Framework for Implant Detection and Marginal Bone Loss Assessment in Panoramic Radiographs

    Wen-Ze Chen, Min-Yuh Day

    Affiliations: National Taipei University, Taiwan

    Keywords: dental implants, panoramic radiographs, vision-language model, keypoint localization, marginal bone loss, multimodal artificial intelligence

    Paper #172 · Computer Vision & Multimodal

    Abstract

    Reliable dental implant detection and marginal bone-loss assessment are important for interpreting panoramic radiographs. However, existing AI approaches often focus on isolated visual tasks without establishing structured evidence for subsequent vision-language reasoning. This study proposes an evidence-grounded framework for future Dental Vision-Language reasoning. It evaluates implant detection and six-point anatomical keypoint localization as the visual foundation for subsequent quantitative bone-loss assessment and structured evidence generation. Preliminary experiments using 1,792 panoramic radiographs showed that the Keypoint R-CNN model achieved 97.78% COCO detection AP50 and 98.29% F1-score, while six-point anatomical keypoint localization achieved 98.43% COCO-style keypoint AP50, 93.73% mean OKS, and 3.10% normalized mean error. Qualitative analysis further identified representative detection and localization errors. This study contributes a structured evidence framework connecting visual predictions with proposed downstream Dental VLM reasoning. The framework provides a foundation for transparent and auditable AI-assisted implant assessment, while quantitative bone-loss measurement and VLM-based clinical interpretation require further validation.

  4. Video-Only Badminton Highlight Generation with Conservative Subtitle Control

    Tsan-Tsung Yang, Kuang-Da Wang, Wen-Chih Peng

    Affiliations: National Yang Ming Chiao Tung University, Taiwan

    Keywords: Badminton highlights, Temporal localization, Subtitle grounding

    Paper #126 · Computer Vision & Multimodal

    Abstract

    Badminton highlight generation requires precise rally boundaries, selective retrieval, and commentary grounded in visible action. We present a video-only framework combining CLTDR-GMG rally localization, I3D-based retrieval, Qwen3-VL shortlist scoring, and time-varying subtitle generation. Window-level visual observations constrain subtitle candidates, followed by deterministic text processing, visual quality assessment, and quality-eligible selection with latest-window priority. On the ShuttleSet test split, CLTDR-GMG achieves 91.55% average mAP, exceeding the evaluated baseline by 2.42 percentage points, with a 5.09-point gain at tIoU 0.7. A paired evaluation on 435 common ground-truth rallies shows lower endpoint error and higher temporal intersection-over-union under both raw and search policies. Endpoint search reduces early cuts but worsens temporal precision, distinguishing endpoint safety from localization accuracy. Separately, 68 preliminary paired comparisons from four sessions evaluate commentary-enabled reels using fixed clip selections against reference highlights. The system receives higher time-efficiency ratings and slightly more preferences, while overall-quality means are descriptively close and the reference scores higher on action completeness. These results suggest a compactness--completeness trade-off in the evaluated reels.

  5. Evaluating Cluster-Based Noise Exclusion in Disaster Social Media Imagery under Recall Constraints

    Yutaka Morino

    Affiliations: Aoyama Gakuin University, Japan

    Keywords: Disaster informatics, Social media, information triage, Recall-constrained retrieval, Vision-language-model

    Paper #149 · Computer Vision & Multimodal

    Abstract

    Monitoring social media during disasters is hampered by useful information buried in a large volume of irrelevant posts. Subtractive triage addresses this by having an operator exclude clearly irrelevant content cluster by cluster, exploiting the fact that noise has more stable features than useful information; however, the human cost of maintaining 100% recall has not been quantified. Using 33,082 annotated images from 476,827 posts collected during the Heavy Rain Event of July 2020 and embedded with a Japanese vision-language model, we examine how much the search space can be reduced without excluding a single damage image, and how many exclusion decisions this requires. Because clusters are excluded in order of their true damage proportion, the results are an upper bound for an operator who judges every cluster correctly. At the granularity of the annotation scheme, raising the target recall from 95% to 100% lowers the search-space reduction from 81% to 55%, and most of this loss arises in the last 0.5 percentage points. Finer clustering raises the reduction by a factor of 1.4(recall 100%, k=19 to k=200) but increases the exclusion decisions from about 10 to about 146. Adding post text in the same embedding space, at any of the tested text weights, yields no substantial improvement in clustering, supervised ranking, or the separation of a potentially confusable category pair. These results motivate distributing the decisions among multiple operators and replacing claims of zero loss with statistically guaranteed lower bounds on recall. This study quantifies how cluster granularity affects both search-space reduction and the number of exclusion decisions at fixed damage recall, providing a basis for designing cluster-level human review.

  6. Training-free Conditional Object Composition for Multi-object Image Generation with Diffusion Models

    Hsuan-Fu Wang, Hsuan-Tien Lin

    Affiliations: National Taiwan University, Taiwan

    Keywords: Diffusion models, Multi-object generation, Compositional generation, Training-free methods, Image editing and inpainting

    Paper #37 · Computer Vision & Multimodal

    Abstract

    Multi-object image generation in text-to-image diffusion models remains challenging, as existing approaches struggle to reliably generate all objects specified in a prompt. Compositional approaches that generate objects independently often fail to capture the interactions among them, whereas joint generation methods tend to suffer from inter-object interference. In this work, we propose a training-free framework, termed conditional object composition, that relaxes joint generation methods by taking one step back toward compositional approaches. Our framework decomposes the generation of $N$ objects into two stages: it first generates a subset of $N-1$ objects and then composes the remaining object conditioned on the generated content. To enable effective composition, we adopt an inpainting-based formulation with layout guidance to preserve existing regions and encourage spatially coherent placement. To address the challenge of selecting which objects to generate separately, we introduce an attention-based scoring mechanism based on cross-attention maps and further explore the use of off-the-shelf object detectors. We evaluate our method on multi-object image generation using the widely adopted MS COCO dataset. Experimental results show that our approach achieves competitive or improved performance compared to existing methods, particularly as the number of objects increases. Further studies highlight the importance of the proposed design choices.

  7. A Study on Synthetic Data Refinement through Agent Feedback

    Takumi Miyazawa, Hiroki Shibata, Yasufumi Takama

    Affiliations: Tokyo Metropolitan University, Japan

    Keywords: Synthetic data, Collaborative filtering, Agent feedback

    Paper #82 · AI Agents & RAG

    Abstract

    This paper proposes a method to refine a synthetic rating matrix for collaborative filtering (CF) to improve the recommendation accuracy for users who are receiving poor recommendations. CF is one of the major approaches in recommender systems, which predicts the ratings that a target user would give to items based on a rating matrix. The effectiveness of CF, however, is limited by the availability of rating histories. Synthetic data have been attracting considerable attention as a solution to the problem of insufficient data in CF and other machine learning tasks. Existing methods for generating synthetic data, however, do not fit a rating matrix to individuals. It is therefore necessary to introduce feedback from users into the synthetic data, so that the synthetic data are optimized to their preferences. Because it is difficult to obtain feedback from real users, this paper employs agents based on a large language model (LLM), each of which simulates the rating behavior of a user according to a given persona. To assess the reliability of ratings given by the agents, which are called feedback ratings, this paper proposes three metrics: persona sensitivity, repetitional consistency, and positional consistency. In the experiments, the MovieLens 100K dataset is used, where Llama 3.1 8B Instruct is employed as an agent. The results show that feedback ratings are sufficiently reliable and that the proposed metrics serve as valid measures for assessing the reliability of the feedback ratings.

DO3 · – · Room B · 2F Lijing Hall B

Domestic Oral Session 3

Topics: Computer Vision & MultimodalAI for Health

Session chair: Prof. Tz-Heng Hsu (Southern Taiwan University of Science and Technology) · 7 papers

  1. 小規模資料下模型效能評估變異性之探討:以腦電圖失智症分類訓練資料取樣策略為例

    蔡尹瑜, 陳榮銘

    Affiliations: 國立臺南大學資訊工程學系

    Keywords: 腦電圖, 失智症分類, 小規模資料, 模型效能評估變異性, 訓練資料取樣策略

    Paper #89 · AI for Health

    Abstract

    腦電圖(electroencephalography, EEG)具有非侵入性及臨床可近性等優勢,具潛力作為失智症篩檢與分類之輔助工具。然而,公開EEG資料集樣本規模有限,可能產生較大的抽樣變異,進而影響模型效能評估及不同訓練資料取樣策略之比較。本研究以CAUEEG資料集公開測試集之158筆記錄為研究資料,探討小規模資料情境下模型效能評估之變異性,並以EEG失智症分類作為研究案例。研究評估兩種訓練資料取樣策略,於原始單一資料切割下,所提策略之Multi-Crop正確率相較原方法最高提升7.81個百分點。然而,10折交叉驗證結果顯示,模型效能標準差達7.59%,其中超過九成的變異與測試集僅包含31名受試者所造成的抽樣不確定性相關。原始單一資料切割所估計之絕對分類效能亦約高估10.7個百分點;於相同10折資料切割下,兩種取樣策略之效能差異縮小至1.88個百分點,且未達統計顯著(p = 0.317)。結果顯示,小規模資料下單一資料切割可能造成較大的模型效能評估變異,進而影響效能估計及方法比較。採用交叉驗證可更穩健地評估模型效能之不確定性。

  2. 整合全域與局部基因模組之多視角遮罩自編碼器於單細胞 RNA 定序聚類之大規模跨資料驗證

    彭姿穎1, 張乃文2, 陳榮銘1

    Affiliations: 1國立臺南大學資訊工程學系 2國立臺灣大學醫學院附設醫院醫學研究部

    Keywords: 單細胞RNA定序, 遮罩自編碼器, 基因分群, 特徵融合, 細胞聚類

    Paper #130 · AI for Health

    Abstract

    scRNA-seq技術能於單一細胞層級量測基因表現,有效揭露細胞間異質性,已廣泛應用於細胞類型辨識、生物醫學研究及疾病分析等領域。然而,其高維度、高稀疏性及高雜訊特性,並伴隨大量Dropout現象,使細胞表示學習與聚類分析面臨顯著挑戰。近年來,單細胞遮罩自編碼器(scMAE)利用自監督遮罩重建進行細胞表示學習,已展現良好聚類效能,然其設計主要著重整體基因表現矩陣之全域資訊擷取,對不同基因模組所蘊含之局部生物特徵關注不足。本研究提出多視角單細胞遮罩自編碼器架構(Multi-view Single-cell Masked Autoencoder, MV-scMAE),結合K-means基因分群、區域特徵學習及特徵串接融合,建立兼具全域與區域資訊之細胞表示。於十五組公開scRNA-seq資料集之實驗顯示,MV-scMAE有十二組(ARI)及十四組(NMI)優於Global-only基線,整體提升達統計顯著水準(ARI: p = 0.0013;NMI: p = 0.0001)。

  3. SMART PHOTOGRAPHER

    Guan-Chang Li1, Hung-Wei Wang1, Yu-Hui Huang2

    Affiliations: 1Yuan Ze University, Taiwan 2National Central University, Taiwan

    Keywords: Pose retrieval, photography assistance, human pose, voice guidance

    Paper #178 · Computer Vision & Multimodal

    Abstract

    Photographing people often requires subjects to adjust their poses, which can be difficult to accomplish without guidance. This study proposes Smart Photographer, a photography assistance system that integrates reference pose retrieval, body-part difference analysis, and voice guidance. The proposed PoseAlign-Match (PAM) method combines position and scale normalization, in-plane rotation alignment, common valid-joint distance, and an annotation-range mismatch penalty to reduce matching errors caused by in-plane orientation variations and missing keypoints in existing normalized keypoint-based methods. The system further employs rule-based body-part analysis to determine pose adjustment directions and provides users with text and voice guidance for pose adjustment. Experiments were conducted on the COCO 2017 dataset using 18,033 reference images and 146 query images. Compared with the normalized keypoint baseline, the proposed PAM method reduced MPJPE by approximately 16.26%, while improving PCK@0.2 by 5.11 percentage points and Precision@5 by 13.43 percentage points.

  4. A Comparative Study of Deep Learning Models for 3D Cardiac Muscle Segmentation: Accuracy–Efficiency Trade-offs from CNNs to Transformers

    An-Yun Liu, Chien-Chang Chen

    Affiliations: National Central University, Taiwan

    Keywords: medical image segmentation, myocardium segmentation, deep learning, Transformer, model efficiency, accuracy-efficiency trade-off

    Paper #30 · Computer Vision & Multimodal

    Abstract

    Accurate segmentation of the cardiac muscle (myocardium) is a prerequisite for assessing ventricular function, yet manual delineation is labor-intensive and operator-dependent. Using the 50 labeled cardiac CT cases of the AI CUP 2025 dataset, we benchmarked eleven 3D segmentation architectures, covering CNNs, attention-augmented CNNs, Transformer/hybrid models, and ConvNeXt-based networks, and examined their accuracy together with inference time and model size. The linear-attention variant of UNETR++ achieved the highest score (0.9037), followed by UNesT (0.9006) and 3D UX-Net (0.8946), whereas the pure ViT encoder UNETR scored only 0.8370. UNETCNX-A1 gave the best accuracy-to-size ratio (0.8886 at 36 MB), and DynUNet the best speed–accuracy balance. Per-structure results revealed a weakness that the overall score hides: only UNesT and UNETCNX-A1 reached a calcification Dice near 0.3, UNETR++ (linear) succeeded partially, and the other eight models failed almost completely. Because no labeled hold-out set was available, all scores were computed on the training cases and each model was trained once. The results therefore describe how well each architecture fits this dataset rather than how well it generalizes. We conclude with preliminary guidance for model selection.

  5. LIPAML: A CROSS-BACKBONE LANGEVIN-INSPIRED PREPROCESSING FRAMEWORK FOR GRAPH-BASED ANTI-MONEY LAUNDERING

    Hao-Yang Li, Berlin Chen

    Affiliations: National Taiwan Normal University, Taiwan

    Keywords: anti-money laundering, graph neural networks, transaction graphs, interpretable feature construction, behavioral representation

    Paper #43 · Computer Vision & Multimodal

    Abstract

    Graph-based anti-money laundering (AML) methods increasingly exploit transaction networks, yet behavioral indicators are often introduced as isolated predictive features. We propose LIPAML, an interpretable feature-construction framework that organizes transaction behavior through a Langevin-inspired view of account state, stochastic fluctuation, interaction, impedance, and additional driving. Its core Node/Edge feature module (NE) constructs label-free node- and edge-level representations from fund-flow states, local variability, endpoint relations, route familiarity, and transaction intensity, while a lightweight propagation module adds risk-context information. On the IBM AML HI-Small dataset, LIPAML improves test F1 over Base by 2.48–5.92 percentage points across four task-adapted graph backbones. These consistent gains suggest preliminary cross-backbone potential and support LIPAML as a reusable preprocessing framework for account-level AML screening.

  6. Multi-View Grasp Pose Generation Using the Diffusion Model

    Tien-Yu Wu, En-Ti Lin, Hsin-Chung Yin, Jenn-Jier James Lien

    Affiliations: National Cheng Kung University, Taiwan

    Keywords: Robotic Grasping, SE(3)-Equivariance, Diffusion Models, Multi-View Perception

    Paper #187 · Computer Vision & Multimodal

    Abstract

    Automated 6-DoF robotic grasping in unstructured industrial environments requires high data efficiency, spatial generalization, and precise physical system integration. Traditional grasp detection approaches rely heavily on large-scale physics simulation data, manual annotations, and object segmentation pipelines. In this work, we present a vision-guided robotic grasping framework based on an SE(3)-equivariant diffusion model (Diffusion-EDFs) integrated with a multi-view point cloud preprocessing pipeline. By combining Eye-in-Hand (EIH) and Eye-to-Hand (ETH) RGB-D sensing with rigid-body coordinate transforms, spatial cropping, 1 cm voxel downsampling, and statistical filtering, the system constructs clean point cloud representations. Using only 12 physical demonstration trajectories without pretraining, data augmentation, or segmentation, the system generates robust 6-DoF grasp poses directly from point clouds. Real-world physical experiments on a Yaskawa MH5LF arm demonstrate an 86.7% grasp success rate.

  7. Power- and Severity-Aware LLM Scheduling in Battery-Powered Navigation Aids for the Visually Impaired

    Quan-Quan Yang, Yu-Fu Huang, Yoke-Hou Tan

    Affiliations: Chung Yuan Christian University, Taiwan

    Keywords: assistive technology, visual impairment, large language model, edge AI, power-aware scheduling, time-to-contact

    Paper #150 · Computer Vision & Multimodal

    Abstract

    Edge AI navigation aids for visually impaired users must continuously run object detection and spoken warnings on battery power, and adding large language model (LLM) scene descriptions can make them more informative but also costs energy and time. This paper proposes two scheduling mechanisms for the optional LLM. A power-aware mechanism invokes the LLM only when needed and restricts it further as the battery runs low, while detection and warnings always remain active. A severity-aware mechanism gives more severe hazards longer descriptions, falls back to a shorter description when time is limited, and skips the description when it cannot finish before the user reaches the hazard. We evaluate both mechanisms in a 100-seed Monte Carlo simulation built on power and latency measured on a Raspberry Pi 5 + Hailo-8 and a Jetson Orin Nano. On the Pi, average power drops by 27.2% relative to always invoking the LLM, while the share of high-severity hazards described in time rises from 13.1% to 23.9%. The results offer a reference design for future LLM-enabled edge assistive devices.

PS3 · – · Poster Area · 2F Liquan Hall exhibition area

Poster Session 3 (International)

Topics: Computer Vision & MultimodalLLMs & NLPAI Agents & RAGOther

Session chair: Prof. Ching-Ting Tu (National Chung Hsing University) · 9 papers

  • BoardIP-11

    Robust Obstacle Avoidance of Autonomous Nano-UAVs with Liquid neural Networks with Monocular Depth Estimation based on Optical Flow

    Jheng-Lin Lin, Zong-Ying Shen, Chung-Chuan Lo, Ya-Tang Yang

    Affiliations: National Tsing Hua University, Taiwan

    Keywords: nano drones, nano-UAVs, obstacle avoidance, optical flow, liquid neural networks, monocular depth estimation, decision tree

    Paper #96 · Computer Vision & Multimodal

    Abstract

    In this work, we designed a learning framework using liquid time constant neural networks (LTC-RNNs), a brain-inspired class of continuous-time neural models to perform vision-based obstacle avoidance. The learning framework is based on training data generated by the decision tree as control policy. The vision-based obstacle avoidance is achieved with monocular depth estimation using optical flow with the image streaming from the nano quadcopter, Bitcraze Crazyflie 2.1 (with a weight of 34 grams). The usage of genetic algorithm successfully identifies optimized LTC-RNN with interpretable decision making network motif. The LTC-RNN generalized well to previously unseen environments with drastic scenery changes.

  • BoardIP-12

    Efficient Machine Unlearning for Vision Transformers via Weight Resetting Strategies

    Zhe-Yu Lin, Wen-Hung Liao

    Affiliations: National Chengchi University, Taiwan

    Keywords: Machine Unlearning, Vision Transformer, Weight Resetting, Model Maintenance

    Paper #94 · Computer Vision & Multimodal

    Abstract

    As privacy regulations increasingly require the removal of specific training data from deployed models, machine unlearning has become a crucial model maintenance mechanism for privacy-aware intelligent systems. This challenge is particularly significant for Vision Transformers (ViTs), whose non-local self-attention and distributed representations make selective forgetting difficult without full retraining. This work studies machine unlearning in ViTs through a weight-resetting unlearning framework. Specifically, we compare three resetting strategies: magnitude-based reset (as an unstructured pruning baseline), gradient-based reset, and attention head reset. We formally decouple the conceptual multi-objective unlearning goal from the practical two-stage resetting-and-recovery pipeline, and formulate parameter importance at an element-wise scalar resolution. Experiments are conducted on CIFAR-100 under the forget-10 setting alongside benchmark baselines and efficiency profiling. The results demonstrate that while all three resetting methods achieve near-complete forgetting after post-fine-tuning, gradient-based reset achieves the most favorable balance between forgetting effectiveness, retain accuracy recovery, and reference model alignment, yielding an ≈ 8.3× speedup over full retraining. Furthermore, intervention scope analysis indicates that targeted parameter resetting in late-stage transformer blocks is sufficient to induce zero-retrain forgetting, offering practical insights for sustainable and privacy-compliant vision deployments.

  • BoardIP-13

    A Foul Classification Model for Basketball Layup Shots Based on Multi-View Image Fusion

    Kenya Oba, Masayoshi Kanoh

    Affiliations: Chukyo University, Japan

    Keywords: Basketball, Foul Classification, Multi-View Images, Deep Learning

    Paper #45 · Computer Vision & Multimodal

    Abstract

    This paper proposes a learning model for classifying the presence or absence of fouls during basketball layup shots using multi-view still images. In the proposed method, still images obtained at the same time from six cameras positioned at different viewpoints are treated as a single input set, and the presence or absence of fouls is classified by fusing the features extracted from each image. To verify the effectiveness of the proposed method, its performance was compared with that of a conventional method using single-view images. The results showed that the proposed method outperformed the conventional method on all evaluation metrics: Accuracy, Recall, Precision, Specificity, and F1 Score. These results demonstrate that fusing and utilizing multi-view information is effective for improving foul classification performance during layup shots.

  • BoardIP-14

    Video-Camera-Based Multi-Person Gaze Estimation System Using Facial Features

    Zhenzhong Duan, Junjie Shan, Megumi Yasuo, Yoko Nishihara

    Affiliations: Ritsumeikan University, Japan

    Keywords: Gaze estimation, Multi-user interaction, Facial Features, Human-computer interaction

    Paper #23 · Computer Vision & Multimodal

    Abstract

    While most video-camera-based gaze estimation methods target a single user, few multi-user studies have investigated per-user per-sonalized facial-landmark models or quantified how anatomical feature partitioning and screen-region granularity affect estimation performance. This study proposes a video-camera-based system that simultaneously estimates the gaze points of two users sharing a screen. The proposed system applies principal component analysis (PCA) to 3D facial landmarks extracted from video images to construct compact facial features. A non-person-specific model (base model) is built before applying each user’s 9-point personal calibration, and the gaze estimation results of multiple users are output simultaneously. We evaluated the proposed system with 18 participants across evaluation screens divided into 9 regions (evaluating accuracy at calibrated positions) and 16 and 25 regions (evaluating spatial generalization to unseen positions). The method separating the eye region yielded the highest sample mean gaze-region accuracies of 95.06%, 88.12%, and 78.44% under the single-user condition and 91.98%, 77.71%, and 64.00% under the two-user condition, respectively.

  • BoardIP-15

    Topological Analysis of Handwritten Japanese Characters Using Persistent Properties

    Masato Suzuki, Daisuke Kitakoshi

    Affiliations: National Institute of Technology, Tokyo College, Japan

    Keywords: Persistent property, Extended persistence landscape, Persistent homology, Character recognition

    Paper #44 · Computer Vision & Multimodal

    Abstract

    Persistent homology is effective for analyzing the structure of handwritten characters, which often exhibit diverse forms. In our previous research, we proposed elliptical filtration and CHD filtration as methods for calculating persistent homology to accurately extract the invariant structure of handwritten characters. However, the persistent intervals extracted using these methods represent the lifespan of each hole or cluster of black pixels. Consequently, if components differ in size or position but have the same number, these features can potentially lead to misrecognition. In this study, we define the persistent property by incorporating information on the position and size of holes or clusters of black pixels into the conventional persistent interval. We prove that this information is contained within specific basis vectors of the representation matrix of the first boundary homomorphism in persistent homology. We also propose an algorithm to extract this information. The proposed persistent property better represents invariant features of characters, and we found that these features improve recognition accuracy.

  • BoardIP-16

    Script-Derived Index Expansion for Natural-Language Retrieval of Anime Production Assets

    Hinata Kirayama, Ryosuke Yamanishi

    Affiliations: Kansai University, Japan

    Keywords: anime production assets, information retrieval, index expansion, script context, dense retrieval

    Paper #102 · LLMs & NLP

    Abstract

    Anime production archives group intermediate assets by production cut; individual files may provide incomplete visual evidence. This study examines how to represent cut-aligned scripts on the index side of a natural-language retrieval system. With a fixed multilingual encoder and ranking procedure, we compare nine conditions based on raw script text, neighboring context, structured metadata, retrieval-oriented rewriting, text concatenation, and score fusion. The evaluation covers Little Witch Academia (LWA1) and Little Witch Academia: The Enchanted Parade (LWA2), with 373 and 269 indexed production-cut units and 53,620 asset files. We report mean pooled nDCG@10 over 23, 12, and 8 queries for the two work-specific settings and the combined corpus. Several representations yielded numerical gains over raw script text, but none of the nDCG@10 comparisons with the baseline reached statistical significance after Holm correction.

  • BoardIP-17

    Parameter-Efficient Knowledge Distillation with DoRA for Instruction-Following Language Models

    Yi-Sin Chen1, Min-Te Sun1, Wei-Shinn Ku2, Po-Wei Harn1

    Affiliations: 1National Central University, Taiwan 2Auburn University, USA

    Keywords: large language models, knowledge distillation, parameter-efficient fine-tuning, DoRA, instruction-following models, model compression

    Paper #103 · LLMs & NLP

    Abstract

    Instruction-tuned large language models have shown strong instruction-following and reasoning capabilities, but their deployment remains costly due to high computational and memory requirements. To improve the practicality of smaller language models, this work investigates parameter-efficient knowledge distillation for transferring instruction-following capability from an 8B teacher model to a 3B student model. Specifically, we investigate a training framework that combines supervised fine-tuning, logits-based knowledge distillation, and DoRA-based parameter-efficient adaptation. To support training, we construct a 20k-sample instruction-style corpus, named Curated Instruction Mixture 20K (CIM-20K), by combining and filtering samples from WizardLM, Magpie-Pro, and ShareGPT. We refer to the resulting distilled 3B student as DoRA-KD-3B and evaluate it against Llama-3.2-3B, DoRA-3B, and LoRA-KD-3B, together with Llama-3.2-3B-Instruct and the Llama-3.1-8B-Instruct teacher as instruction-tuned reference models. Across three random seeds, DoRA-KD-3B achieves mean scores of 3.787 on MT-Bench, 0.474 on ARC-C, 0.293 on GSM8K, 0.552 on MMLU, and 0.456 on TruthfulQA, exceeding the base Llama-3.2-3B model on all five aggregate benchmarks. Among the trained non-instruction-tuned 3B models, DoRA-KD-3B achieves the highest mean scores on MT-Bench, ARC-C, MMLU, and TruthfulQA, while DoRA-3B achieves the highest mean score on GSM8K. Overall, the results suggest that logits-based distillation can complement DoRA-based adaptation, although its benefit depends on the evaluation task.

  • BoardIP-18

    GuardianNet: An LLM-Assisted Multi-Agent Framework for Detecting Stealthy SDN Anomalies

    Yu-Yang Huang, Chirag Jindal, Mochamad Fakhri Andian, Po-Yu Chen, Kippei Ando, Le Anh Kiet, Po-Wei Harn

    Affiliations: National Central University, Taiwan

    Keywords: Software-Defined Networking, Large Language Models, Multi-Agent Systems, Anomaly Detection, DDoS, Cybersecurity

    Paper #66 · AI Agents & RAG

    Abstract

    Software-Defined Networking (SDN) centralizes control-plane intelligence, exposing it to both volumetric DDoS floods and stealthy, low-rate poisoning attacks. Existing defenses address these threats in isolation---volume-based classifiers miss covert low-rate patterns, while purely entropy-based methods suffer elevated false positives---and both lack the semantic contextual awareness needed to reliably distinguish benign fluctuations from adversarial behavior. To address these limitations, we propose GuardianNet, an LLM-assisted multi-agent framework deployed within a Mininet and Ryu SDN testbed. Our system comprises a hierarchical three-agent architecture: (1) a Statistical Agent employing a K-Nearest Neighbor (KNN) classifier for instantaneous volumetric screening; (2) an Entropy Agent that computes Shannon Entropy over the packet-delta sequence of each flow to detect the mechanical regularity characteristic of low-rate injection; and (3) a Reasoning Supervisor powered by a locally deployed open-source Large Language Model (Llama-3.1). By converting raw telemetry and entropy signals into structured natural-language contexts, the LLM supervisor enables reasoning over attack semantics that numerical classifiers cannot capture. Compared against four established baselines---KNN, Random Forest, LSTM, and an Entropy Only detector---GuardianNet attains 90.0\% accuracy with a 0.0\% FPR. The ablation study across six agent configurations shows that rule-based fusion of the two statistical agents reaches 68.1\% accuracy with a 68.2\% false positive rate (FPR), whereas adding the LLM supervisor raises accuracy to 83.2\% and eliminates false positives entirely.

  • BoardIP-19

    What a Decoder-Side Network Recovers from CRA5: Near-Surface versus Upper-Air Error over CONUS

    Tong-Jen Wang, Chieh-An Chou, Lu-Hung Chen

    Affiliations: National Chung Hsing University, Taiwan

    Keywords: Scientific data compression, Atmospheric reanalysis, Learned compression, Decoder-side residual prediction, ERA5

    Paper #113 · Other

    Abstract

    Learned atmospheric compressors are usually assessed by aggregate distortion, which does not reveal how much residual error remains predictable from decoded fields. We apply a fixed 1.65\,M-parameter U-Net to CRA5 reconstructions over CONUS without adding per-frame bits. On the full 2018 test year, mean normalised RMSE decreases by 25.8\% over 19 directly represented FourCastNet variables (95\% temporal block-bootstrap interval [25.32, 26.18]\%). On the complete 2022 year outside CRA5's published training window, the same frozen checkpoint and normalisation give a 26.4\% reduction [25.90, 26.93]\%, without fine-tuning. Near-surface versus upper-air gains are 32.2\% versus 3.5\% in 2018 and 32.8\% versus 3.6\% in 2022. A mean-rate-matched MPCA-only control has a smaller near/upper gain ratio, while additional MPCA+PCA controls are explicitly non-matched. A parameter-matched dilation ablation retains a roughly eightfold split and concentrated gradient sensitivity. Using ERA5 orography and land--sea masks, western-land correction gains increase from 18.1\% to 36.9\% between the lowest and highest terrain-roughness deciles, while corrected errors remain larger on rough ground. Elevation-stratified comparisons support an association but do not isolate a terrain mechanism. These results measure model-relative predictability; terrain causality, corrector architecture effects, and broader distribution-shift robustness remain open. Shared weights and inference add deployment costs.

Day 2

Saturday, November 21, 2026

–

IO4 · – · Room A · 2F Lijing Hall A

International Oral Session 4

Topics: Computer Vision & MultimodalLLMs & NLP

Session chair: Prof. Jian-Xing Li (National University of Tainan) · 5 papers

  1. A Closer Look at Road Damage Detection on Imbalanced Multi-Country Data

    Mirkamol Mirkamilov, Lematte Ahmed, Saydobid Khusanov, Yuan Zhou

    Affiliations: Nanjing University of Information Science and Technology, China

    Keywords: Road Damage Detection, Object Detection, Imbalanced Data, Benchmarks, Computer Vision

    Paper #211 · Computer Vision & Multimodal

    Abstract

    Maintaining road infrastructure imposes critical challenges, such as road monitoring, condition assessment, and targeted fixes. Manual road surveillance is costly and unsuitable for long-term sustainable development, which necessitates automation of the process. Road Damage Detection (RDD) is one of the most crucial applications of Computer Vision. As automated detection requires the integration of the Internet of Things (IoT) with intelligent detectors, implementing lightweight detection methods is crucial. Apart from the architectural design, training data plays a crucial role, which necessitates a careful data preparation pipeline to overcome common issues such as class imbalance. In this study, we investigate various methods to overcome this issue with a controlled experimental setup. We employ the challenging, severely imbalanced multi-country N-RDD2024 dataset to perform data-centric analysis. Our comparison includes three YOLOv8 (small, medium, and large) and three YOLOv11 (small, medium, and large) detector backbones trained using four different data-class modes (original, grouped, frequency-filtered, and priority) to overcome class imbalance and four training and inference strategies (standard training, Test-Time Augmentation, localization-focused, and class-weighted training) to analyze the role of optimization. The experimental results reveal that the data-class design was the primary driver of performance improvement, where grouped and frequency-filtered aggregations led to the highest performance regardless of the backbone. The analysis also includes investigating various image resolutions, as well as inference latency and efficiency metrics. This work aims to contribute to efficient RDD development under resource-constrained environments, making the detectors suitable for edge deployment and real-time inference.

  2. Environment Curriculum Generation via Vision-Language Models

    Yu-Hsin Chou, Kuei-Chung Chen, Hsuan-Tien Lin

    Affiliations: National Taiwan University, Taiwan

    Keywords: Reinforcement Learning, Vision-Language Models, Unsupervised Environment Design

    Paper #56 · Computer Vision & Multimodal

    Abstract

    Unsupervised Environment Design (UED) aims to promote generalization by automating the generation of a curriculum of environments for training control policies, maximizing the learning utility tailored to the current policy's capabilities. Replay-based UED methods prioritize environments sampled from a random generator, while learning-based UED methods generate environments via a learned generator. However, for control tasks with complex environment generation spaces, randomly generated environments can become overly complex. In addition, learning-based methods often rely either on a predefined dataset, which may not be available, or on reinforcement learning, which can be unstable. In this work, to address these challenges, we investigate whether an off-the-shelf Vision-Language Model (VLM) can serve as an effective environment curriculum generator for UED because a VLM can leverage its prior knowledge of real-world distributions to constrain environment generation for replay-based methods and serve as a training-free alternative. Experimental results demonstrate that a VLM, when properly prompted, serves as a promising generator that outperforms existing UED baselines. Furthermore, we show that integrating a complementary replay-based method can further improve generalization performance.

  3. Multimodal Representation and Reformulation of Creative Intention in AI Video Generation

    Chuei-Huei Kung

    Affiliations: Fu Jen Catholic University, Taiwan

    Keywords: Generative Video, Multimodal Representation, Agentic AI, Retrospective Case Analysis, Research through Design

    Paper #127 · Computer Vision & Multimodal

    Abstract

    This RtD-informed retrospective case analysis examines how creative requirements were represented and reformulated while producing a 121-second AI-generated video comprising ten interdependent narrative units. Generation histories for S01–S10 were retained in Seedance 2.0, but coverage did not imply equal claim-level support. The analysis distinguishes event organization from requirement decomposition, maps object–relation and state–process configurations, and assesses input specification, output compliance, and subsequent action separately. Evidence is classified by support level: paired input–output (Vp), ordered revision-chain (Vc), summary-supported (S), or conflict-flagged (C). S05 documents an unmet fivefold scale requirement and a subsequent ordered revision to a tenfold scale; S08 and S09 provide additional chains. Evidence varies across four reformulation codes: process elaboration and relational-constraint change are chain-supported, event segmentation occurs in S09, and reference reconfiguration remains unverified. The framework suggests preliminary intention checks for future agentic creative systems without evaluating autonomous behavior, independently validating coding, or testing causal revision effects.

  4. Attack-Resilient Hierarchical Federated Intrusion Detection for Communication-Constrained Low-Altitude UAV Networks

    Mao-Hsiu Hsu, Po-Chia Chuang

    Affiliations: National Formosa University, Taiwan

    Keywords: Federated learning · Hierarchical federated learning · Intrusion detection · UAV networks

    Paper #179 · Computer Vision & Multimodal

    Abstract

    UAV-based Intrusion Detection Systems (IDS) for LowAltitude Wireless Networks (LAWN) face three major obstacles that undermine conventional Federated Learning (FL): non-independent and identically distributed (Non-IID) data, class imbalance, and communication constraints. To address them, we present a robust three-tier Hierarchical Federated Learning (HFL) framework based on a “Client– Aggregator–Cloud” architecture. The framework combines FedProx, Server EMA, dynamic class weighting, and cloud-based knowledge distillation with Prototype Learning. Evaluations on the CICIDS2017 dataset, including systematic ablation studies and tests under Label Flipping and Model Poisoning threats, show that the proposed framework reaches an F1-score of 0.9753 and substantially surpasses the FedAvg baseline in both accuracy and convergence speed. The resulting hierarchical security solution is secure, communication-efficient, and deployable in LAWNs. The source code is available in the project repository.

  5. A Comparative Analysis of Humor in Japanese Ogiri Responses Generated by an LLM and Humans

    Bifu Ohishi, Megumi Yasuo, Junjie Shan, Yoko Nishihara

    Affiliations: Ritsumeikan University, Japan

    Keywords: Large language model· Humor generation· Japanese Ogiri · Humor evaluation· Text analysis· AI Humor

    Paper #73 · LLMs & NLP

    Abstract

    This study compared and analyzed the humor generated by an LLM and humans in the context of Ogiri. Ogiri is a Japanese comedy format in which participants improvise short responses to a given theme, competing based on the unexpectedness and humor of their ideas. Re-sponses often involve deviations from context and wordplay, requiring spontaneous creativity. In recent years, advancements in generative AI technology have made sophisticated language generation possible. How-ever, it remains unclear whether LLMs possess the same capabilities as humans when it comes to generating humor that requires cultural con-text and spontaneous creativity, as seen in Ogiri. Therefore, this study conducted a subjective evaluation experiment with 24 participants, us-ing responses generated by ChatGPT (an LLM) and response data from comedians on the Ogiri TV Show for the same themes. In the experi-ment, responses from the LLM and humans were presented randomly, and participants were asked to rate the humor of each response on a 7-point Likert scale ranging from 0 to 6. In total, we selected 10 themes and prepared 20 responses for each theme, consisting of 10 responses generated by the LLM and 10 responses created by humans, resulting in 200 responses evaluated by the participants. The results showed that, on average, human responses significantly outperformed LLM-generated re-sponses. Analysis of the responses revealed that humans excelled in the leaps of logic and surprise characteristic of Ogiri. On the other hand, instances were observed where the LLM received higher ratings than humans for certain themes. Analysis revealed that the LLM generated responses containing logical and concrete explanations, suggesting that ease of understanding contributed to the higher humor ratings. In con-trast, the short responses provided by humans were difficult to under-stand in context when presented as text alone. The results of this study indicate that while the LLM excels at contextual coherence and explana- tory ability, humans currently hold the advantage in Ogiri, suggesting that LLMs have the potential to surpass humans under specific condi-tions.

DO4 · – · Room B · 2F Lijing Hall B

Domestic Oral Session 4

Topics: Computer Vision & Multimodal

Session chair: Prof. Rong-Ming Chen (National University of Tainan) · 4 papers

  1. Mapping Intent: Agentic UAV Route Planning with Semantic Cost Maps

    Jeng Wen Joshua Lean1, Ting-Yu Yen1, Kang-Chiao Lin2, Xu-Peng He2, Shih-Hsuan Hung1, Hung-Kuo Chu1

    Affiliations: 1National Tsing Hua University, Taiwan 2Industrial Technology Research Institute, Taiwan

    Keywords: UAV path planning, vision-language models, agentic AI, semantic cost maps

    Paper #208 · Computer Vision & Multimodal

    Abstract

    Natural-language UAV missions combine terrain preferences with ordered visits and surveys. We present a vision-language agent that constructs semantic cost maps and route anchors, evaluates A* paths, and revises its decisions through visual feedback. In 27 missions with three repetitions per method, it returns all 81 routes and achieves a mean model-judged checklist violation rate of 14.7%, versus 45.8% for an OVerSeeC implementation. The system integrates semantic terrain modeling, ordered route planning, and visual revision in a unified workflow for compositional aerial missions.

  2. 基於姿態估計之個人化網球教練系統:揮拍特徵組合歸納與修正建議驗證架構

    陳孝宗 (Hsiao-Tsung Chen), 溫演福 (Yean-Fu Wen), 謝立文 (Li-Wen Hsieh)

    Affiliations: 國立臺北大學資訊管理研究所

    Keywords: 姿態估計, 網球, 揮拍特徵, 個人化回饋, 教育科技

    Paper #216 · Computer Vision & Multimodal

    Abstract

    現有網球 AI 教練系統多以專家模板之相似度作為回饋依據,難以說明動作差異與擊球結果之關聯,其建議之正確性亦未被驗證。本研究提出一套基於姿態估計之個人化網球教練系統驗證架構,以多視角攝影擷取人體關節點、球拍與球體軌跡,計算擊球瞬間之拍面角度、揮拍速度、擊球點位置、肩髖分離角與重心轉移量等多維揮拍特徵,並以過網高度與落點區域定義擊球是否達成目標。系統以特徵重要性辨識關鍵因子,並從揮拍條件相近之成功擊球產生量化修正建議,再以混淆矩陣評估建議之準確度。驗證分為兩階段:先以預試檢驗姿態估計與特徵之可靠性;再以 10 至 15 位初學者之發球機正手直線擊球(每人 50 球),以實際落點正反向檢驗建議之正確性,並與基準方法比較。本文完成架構與協議之設計,正式資料收集尚未執行。

  3. 資料集特性分析於少樣本類別增量學習中的影響

    賴瑋宥, 劉立頌, 劉育銨

    Affiliations: 國立中正大學電機工程研究所

    Keywords: 少樣本類別增量學習, 跨模態語義對齊, 提示學習, CLIP, 需求分析

    Paper #79 · Computer Vision & Multimodal

    Abstract

    少樣本類別增量學習 (Few-Shot Class-Incremental Learning, FSCIL) 的核心目標,是在每個新類別僅有少量樣本的條件下持續學習,同時維持對舊類別的辨識能力,因此同時面臨災難性遺忘與少樣本過擬合。現有方法多以固定策略處理不同資料集,較少考量資料特性在特徵空間幾何上的差異。本研究借用軟體工程的需求分析思維,以 SEC-Prompt 為提示學習基底,並引入凍結的 CLIP 文字編碼器作為跨模態語義錨點,針對 CIFAR-100 的高雜訊與低解析度、CUB-200 的細粒度極端相似性,以及 ImageNet-R 的跨領域風格變異,分別設計信心感知邊界語義對齊模組 (CAM-SAC)、跨模態柔性分佈蒸餾模組 (CM-SDD) 與跨模態同步混合語義對齊 (Mixup-SAC)。標準 5-shot 實驗中,本研究在三個資料集皆取得最高平均準確率 (AAvg),且相較基線 SEC-Prompt,準確率下降幅度 (PD) 分別降低 1.54、0.42 與 1.49 個百分點。跨資料集消融中,CIFAR-100 於方法錯置時 PD 最高達專屬方法的 4.6 倍。

  4. 基於 StressID 資料集之多模態與集成學習壓力辨識方法

    李佳芸, 黃芷婕, 蘇明祥 (Minghsiang Su)

    Affiliations: 東吳大學資料科學系

    Keywords: 壓力辨識, 多模態情感運算, 集成學習, SGKF, Transformer-BiLSTM

    Paper #176 · Computer Vision & Multimodal

    Abstract

    長期壓力會危害身心健康,因此建立可靠且可泛化的自動壓力辨識系統已成為情感運算的重要課題。然而,既有研究常未嚴格隔離受試者,且在有限資料下,手工特徵、深度序列模型、多模態融合與集成學習之相對效益仍缺乏一致比較。本研究使用同步蒐集生理訊號、影像與語音之 StressID 資料集,採用五折受試者分層群組交叉驗證(Subject-wise Stratified Group K-Fold, SGKF),並以巢狀模型選擇確保外層測試受試者不參與超參數或投票權重調整。實驗系統性比較手工特徵、ResNet-50 與 Wav2Vec 2.0 表徵、LSTM、Transformer-BiLSTM、特徵層與決策層融合,以及多種集成方法。結果顯示,基於原始 500 Hz 訊號萃取之生理手工特徵整體最佳:二元壓力辨識使用 ExtraTrees 的加權 F1 為 0.699、平衡準確率為 0.704;三分類情感辨識使用加權軟投票的加權 F1 為 0.513。多模態 Transformer-BiLSTM 於二元任務達 0.652,仍未超越生理集成模型。5、25、50 與 100 Hz 的控制式消融亦顯示,提高輸入取樣率並未改善生理 LSTM。研究結果說明,在受試者獨立且資料有限的條件下,領域知識導向的生理表徵與穩健集成學習,比單純增加時間解析度、模態數量或模型複雜度更具效益。

PS4 · – · Poster Area · 2F Liquan Hall exhibition area

Poster Session 4 (Domestic)

Topics: Computer Vision & MultimodalSpeech & Audio

Session chairs: Prof. Ling-Yen Pan (National Taipei University); Prof. I-Hsien Ting (National University of Kaohsiung) · 12 papers

  • BoardDP-13

    Point-Supervised Weed Stem Candidate Localization Using U-Net Heatmaps for RealSense-Assisted Laser Weeding

    Pradeep Marimuthu, Yu-Sung Liu

    Affiliations: National Formosa University, Taiwan

    Keywords: weed detection, stem localization, U-Net, heatmap regression, point annotation, RealSense camera, laser weeding

    Paper #122 · Computer Vision & Multimodal

    Abstract

    This work presents a preliminary weed stem candidate localization method for RealSense-assisted laser weeding. Instead of using full polygon segmentation masks, the proposed approach uses point-level annotations placed near visible weed stem centers. The annotated points are converted into Gaussian heatmaps and used to fine-tune a U-Net-based model for stem candidate prediction. A manually prepared dataset containing 114 cropped field images and 974 weed-stem point labels was used. The data were split into 79 training images, 17 validation images, and 18 test images. On the 18 test images, an exploratory threshold of 0.85 produced 137 matched points from 155 ground-truth stem points, with 25 false positives and 18 missed points. The precision, recall, and F1-score were 0.8457, 0.8839, and 0.8644, respectively, with a mean localization error of 3.7629 pixels on a 512-pixel scale. Preliminary RealSense RGB camera experiments using printed weed images demonstrated live stem-candidate localization. However, false detections on crop or non-target plants remain a limitation. Future work will focus on crop-weed filtering, height-aware RealSense calibration, and laser shooting efficiency tests on weeds with different heights.

  • BoardDP-14

    FRESHKG MISSION SUPERVISION WITH TRACKING AND ATTITUDE EVALUATION

    Chun Shih Cheng, Yu Jie Tsai, Cheng You Lin, Zih Sian Yang

    Affiliations: Chaoyang University of Technology, Taiwan

    Keywords: UAV mission supervision, information freshness, knowledge graph, waypoint tracking, attitude evaluation.

    Paper #161 · Computer Vision & Multimodal

    Abstract

    FreshKG is evaluated as a mission-level supervisor for UAV routes whose corridor permissions can age, arrive late, or conflict across sources. Experiments in gym-pybullet-drones and safe-control-gym comprise 30,000 mission episodes and 2,000 fixed-reference tests, with 100 paired seeds per condition. With the safe-control-gym PID controller, FreshKG safely completes 464/600 missions, compared with 107/600 for LatestArrival; the paired improvement is 59.5 percentage points (95% cluster-bootstrap CI, 57.7-61.2). An equal-information table implementation and the graph implementation make identical supervisory decisions, indicating that the gain arises from the information rules rather than graph representation alone. We repeat the mission study with PID, LQR, MPC, and six fixed PPO/SAC residual checkpoints, and use separate fixed-reference trials to characterize tracking and attitude behavior. Ablations isolate observation order, expiry, and source filtering, while recorded failures show where replanning is insufficient. The evidence is limited to simulation and supports a mission-supervision claim, not a new flight controller or formal safety guarantee.

  • BoardDP-15

    Hierarchical Specialist Networks and Few-Shot Language Reconstruction for Skeleton-Based Taiwanese Sign Language Recognition

    Jhih-Shan Tsai, Pei-Hao Chen, Tou-Tou Wu, You-Yin Lin, Huan-Yu Chen

    Affiliations: National Taichung University of Science and Technology, Taiwan

    Keywords: Taiwanese Sign Language, skeleton features, hierarchical classification, few-shot prompting, LangChain

    Paper #171 · Computer Vision & Multimodal

    Abstract

    This paper presents a skeleton-based Taiwanese Sign Language (TSL) recognition and sentence reconstruction system. MediaPipe Holistic landmarks are normalized, cropped by wrist motion, and resampled to 30 frames. A task-specific hierarchy routes inputs to five motion families and activates a specialist whose features match the observed motion structure. On a video-level 80/20 split, the 124-dimensional Uni-LSTM with temporal attention achieves 99.42% gatekeeper accuracy, while specialist accuracies are 81.40%, 100.00%, 92.40%, 91.60%, and 95.80% on 79 labels and 398 videos. These are component results; the approximately 91.7% cascade value is an independence-based estimate rather than a measured end-to-end accuracy. A local language reconstruction module uses seven TSL-oriented few-shot patterns and a three-turn LangChain memory to reconstruct fragmented lexical predictions into Chinese sentences. The language results are prototype-scale qualitative evidence, and signer-independent testing, controlled baselines, sentencelevel metrics, human evaluation, and full-pipeline latency remain future work. All data processing and document preparation for this study were performed locally.

  • BoardDP-16

    Ego-Motion Compensated Adaptive Spatio-Temporal Difference Gating for UAV Edge Dynamic Object Detection

    Ming Chien Ho, Yan Je Wang, Ting Ying Chien

    Affiliations: Yuan Ze University, Taiwan

    Keywords: UAV edge computing, camera ego-motion compensation, spatio-temporal gating, dynamic object detection, green AI

    Paper #182 · Computer Vision & Multimodal

    Abstract

    Real-time visual surveillance on unmanned aerial vehicles (UAVs) is severely constrained by onboard battery storage and thermal dissipation limits, rendering continuous 30 FPS deep neural network (DNN) forward passes unsustainable. Conventional background subtraction fails catastrophically in aerial video due to 6-DoF camera ego-motion. In this paper, we propose an Ego-Motion Compensated Adaptive Spatio-Temporal Difference (ASTD) gating architecture for energy-efficient edge detection. ASTD dynamically neutralizes drone flight motion via real-time RANSAC homography alignment and scale-invariant spatial filtering, serving as an intelligent compute gate that awakens downstream DNN detectors only upon genuine dynamic events. Evaluated on a continuous 1,821-frame 1080P real-world construction flight sequence, ASTD successfully skips 97.91% of redundant background frames at an ultra-low edge latency of 22.04 ms (45.37 FPS). ASTD slashes weighted per-frame inference latency by 91.0% (serving as an effective proxy for edge computational energy reduction) while achieving 100% event recall across all active machinery, demonstrating exceptional power efficiency for persistent autonomous UAV surveillance.

  • BoardDP-17

    結合PatchCore與視覺語言模型之可解釋工業異常檢測 (Explainable Industrial Anomaly Detection by Combining PatchCore and Vision Language Models)

    廖偉煊 (Liao Wei-Syuan)1, 饒建奇 (Jiann-Chyu Rau)2

    Affiliations: 1淡江大學電機工程學系人工智慧物聯網組 2淡江大學電機工程學系

    Keywords: VLM, PatchCore, 工業異常檢測, 開放權重模型, 可解釋人工智慧, VLM, PatchCore, Industrial Anomaly Detection, Open-Weight Model, Explainable AI

    Paper #17 · Computer Vision & Multimodal

    Abstract

    現有將 VLM 應用於工業異常檢測的研究多偏重邏輯性異常,較少顧及結構性異常。本研究透過資料庫式異常檢測與 VLM 的結合來完善兩類異常的偵測平衡:PatchCore 將區域異常分數以文字提供給 VLM,VLM 回答邏輯性與結構性問題集後評分,最後整合兩者的分數判斷是否異常。我們發現僅用邏輯性問題集時,VLM 在結構異常上與 PatchCore 的貼合度不足,因此加入了結構性問題集讓 VLM 回答更多結構性異常原因;而實驗中也發現 VLM 擁有最終判定權時會否決 PatchCore 的資訊,因此改採等權重分數融合。本架構不需訓練模型參數,在 MVTec LOCO-AD 上達到 logical F1-max 0.870、logical AUROC 0.916、structural AUROC 0.917 與 overall AUROC 0.915,並能輸出自然語言的異常原因說明。

    Existing VLM-based work on industrial anomaly detection focuses mainly on logical anomalies and pays less attention to structural ones. We balance the two by combining database-based anomaly detection with a VLM: PatchCore supplies regional anomaly scores to the VLM as text, the VLM answers a logical and a structural question set and returns scores, and the two scores are fused to decide whether an image is anomalous. We found that with logical questions alone the VLM aligned poorly with PatchCore on structural anomalies, so we added a structural question set that lets the VLM report more structural causes; we also found that the VLM overrides PatchCore when given final decision authority, so we fuse the scores with equal weights. The framework trains no model parameters. On MVTec LOCO-AD it achieves a logical F1-max of 0.870, logical AUROC of 0.916, structural AUROC of 0.917, and overall AUROC of 0.915, with natural-language explanations of detected anomalies.

  • BoardDP-18

    基於 MCP 的使用者行為資料最小化與異常分析

    金石開, 袁佳慶

    Affiliations: 嶺東科技大學資訊科技系

    Keywords: 模型上下文協定, 使用者行為資料蒐集, 使用者行為分析, 異常偵測, 資料最小化

    Paper #165 · Computer Vision & Multimodal

    Abstract

    語言模型可透過模型上下文協定(Model Context Protocol, MCP)調用外部工具,但通過身分與角色授權,並不代表每次操作都符合使用者原有的行為脈絡。研究原型在 MCP 工具呼叫包裝層建立事件:呼叫前取得使用者、工作階段、工具、時間與工作流程等脈絡,呼叫後補入目的地類別及執行狀態,再選取分析所需欄位形成研究資料;完整提示詞、憑證、敏感工具參數及完整輸出不納入本文分析資料。固定合成測試集共 290 筆事件,工作流程感知規則模型的 Recall、Precision、F1 與 FPR 分別為 0.724、0.974、0.831 與 0.050,ROC-AUC 及 PR-AUC 分別為 0.986 與 0.994。在同一測試集的回溯消融中,加入工作流程脈絡欄位後,F1 由 0.794 增至 0.831。結果顯示,依 MCP 工具呼叫結構形成的操作脈絡可轉換為可追溯的使用者行為資料,並用來辨識時間、工具、目的地與工作流程等偏離。所有結果均來自合成資料,尚不能視為真實企業環境的異常偵測成效;行為分數也不直接改變既有授權決策或工具執行結果。

  • BoardDP-19

    探討不同多模態架構於黑色素瘤預測效能之比較

    蔣典宸, 王翊宇 (Yiyu Wang), 吳芷瑩, 陳映瑄, 鄭秋艷, 李彩儀, 翁政雄

    Affiliations: 國立彰化師範大學資訊管理學系

    Keywords: 黑色素瘤分類, 多模態深度學習, 特徵融合, 類別不平衡, 焦點損失函數

    Paper #90 · Computer Vision & Multimodal

    Abstract

    黑色素瘤資料高度不平衡,且既有多模態研究常採不同模型與實驗設定,難以釐清各架構元件的實際影響。本研究以 ISIC 2020 資料集進行四階段比較,依序評估影像特徵提取器、臨床資料模型、融合策略與損失函數,並以惡性類別 Recall 與 F1-score 為重點。最終架構(EfficientNet + MLP + Ori-concat + Focal Loss)於驗證集達 ROC-AUC 0.9108、Accuracy 0.9470、惡性 Recall 0.5043 與 F1-score 0.2516,其惡性 Recall 高於影像單模態 (0.0342),Precision (0.1676) 則在 Recall 相近下高於僅用臨床資料之模型 (0.0498)。結果顯示,在本實驗設定下,較複雜的融合機制未提升惡性檢出,而多模態資訊與 Focal Loss 有助於改善極度不平衡情境下的少數類別辨識。

  • BoardDP-20

    應用影像監控系統於海鱺性徵成熟度判定

    謝易錚, 蒙諺勳

    Affiliations: 國立臺灣科技大學電機工程系

    Keywords: 深度學習, 海鱺性徵成熟度分析, Openpose, FHRCNN

    Paper #100 · Computer Vision & Multimodal

    Abstract

    本研究針對海鱺種魚外觀性徵不易由岸上觀察之問題,自行蒐集養殖場水下影像並進行人工標註,建立海鱺種魚性徵成熟度資料集,提出以腹部骨架與條紋幾何特徵為基礎的影像分析方法。系統以 YOLOR 定位魚體並選取側面影像,再以重新訓練之 MobileNet v1 作為特徵擷取網路,利用自建海鱺關鍵點資料微調 OpenPose,預測依養殖專家經驗定義之性徵位置與腹部骨架,透過主成分分析量化條紋特徵長度,將條紋與腹部長度比例 R 及腹部角度 D 輸入 FHRCNN,完成 0 至 3 期外觀性徵分類。研究貢獻包括自建性徵成熟度資料集、海鱺專用關鍵點與骨架設計、OpenPose 任務微調、腹部與條紋幾何表示,以及水下魚體偵測至性徵分期之流程整合。成熟度分類資料包含訓練 1,200 筆、驗證 150 筆及測試 150 筆,依十次實驗結果計算,FHRCNN 平均測試準確率為 74.30%,線性 SVM 平均測試準確率為 74.10%。本研究將養殖人員依經驗觀察的腹部與條紋特徵轉換為量化資料,建立海鱺種魚外觀性徵分期之影像分析基礎。

  • BoardDP-21

    組合料號電子零件內容之自動擷取

    洪宗貝 (Tzung-Pei Hong)1, 林義勳1, 卓恩綺2, 黃士峰3, 施宣妤4, 陳怡婷4

    Affiliations: 1國立高雄大學資訊工程研究所 2國立高雄大學應用數學研究所 3國立中央大學統計研究所 4富比庫股份有限公司

    Keywords: 電子設計自動化, 電子零件規格書, 組合料號圖, 物件偵測, 深度學習

    Paper #186 · Computer Vision & Multimodal

    Abstract

    組合料號圖,又稱為料號說明列表,常存在於電子零件規格書中表示一組相似零件料號的基本特性,而各廠商組合料號圖也常具有不同的樣式,甚至同一家廠商就可能有多種組合料號表示。通常一份組合料號圖上至少會含有下列三部分的資料:樣板、特性、及屬性值(含說明),而這三個部分的資料內容常會是電子設計自動化公司之工程師所需要參考的資料。而組合料號的形式眾多,而且都是以圖形形式儲存,而不是簡單的以表格儲存,因此更增添了處理時的困難度。由於一份PDF電子規格書可能包含很多頁,因此我們先結合關鍵字判斷及物件偵測的技術找出組合料號圖所在的頁數及該圖在所找到頁數的位置,並把它切割出來。接著我們利用深度學習的方法去擷取一組合料號圖的樣板、特性、及屬性值(含說明)區塊,並使用傳統圖形識別的方法找出組合料號圖的特徵如有無方框、線條方向等精確地框定並配對子名稱與其對應的屬性值以獲得更準確的結果。接下來,我們再運用光學文字辨識技術對所割出來的樣板、特性、及屬性值(含說明)區塊作內容辨識,並利用正規表達式以及黑白名單策略將其分類為子名稱、屬性、值和值集合。實驗顯示不受OCR影響時準確率可達到87%。

  • BoardDP-22

    Melody–Accompaniment Separation in Synthesized Solo Piano Audio Using Spectral U-Nets and a Composite Loss

    Hao Chun Kao, Chao Zong Wang, Yu Han Huang

    Affiliations: National Dong Hwa University, Taiwan

    Keywords: Music Source Separation, Solo Piano, Melody–Accompaniment Separation, Spectral U-Net, Composite Loss

    Paper #64 · Speech & Audio

    Abstract

    Melody–accompaniment separation in solo piano audio requires distinguishing musical roles that share timbre and overlapping spectra. We evaluated two independent spectral two-dimensional (2D) U-Nets with complementary-source masking and mixture-phase reconstruction, trained on piano audio rendered from Classical MIDI files. A composite objective combined spectral L1, multi-scale pooling, waveform scale-invariant signal-to-distortion ratio (SI-SDR), and similarity losses. On 80 held-out test pieces, mean SI-SDR was 8.4 dB for melody and 10.7 dB for accompaniment. In a supplementary re-rendering test with two alternative SoundFonts, mean SI-SDR improvement over the input mixture remained positive, although scores decreased. An exploratory listening study with 126 respondents detected differences among accompaniment excerpts but no significant differences among melody outputs. The findings are limited to synthesized audio; controlled model comparisons, loss ablations, and evaluation on real recordings remain necessary.

  • BoardDP-23

    Patient-Level Weak Supervision as a Stress Test of Vision Foundation Model Transfer and Domain Adaptation in Gastroscopy

    Chien-Liang Liu1, Bo-Jyun Wang1, Shayan Kordi1, Shu-Wei Huang2, Yu-Chung Wang1, Kwei-Jay Lin1, Ying-Feng Chang1

    Affiliations: 1Chang Gung University, Taiwan 2New Taipei Municipal Tucheng Hospital, Taiwan

    Keywords: Helicobacter pylori, gastroscopy, weakly supervised learning, vision foundation model, domain adaptation

    Paper #97 · Computer Vision & Multimodal

    Abstract

    Patient-level weak supervision reduces frame-level annotation in gastroscopy but propagates each patient's diagnosis to many nondiagnostic images. We compared eight Vision Transformer backbones for Helicobacter pylori prediction under fine-grained image-level and patient-level weak supervision. Models were developed with five-fold patient-level cross-validation in 327 patients and evaluated in an independent temporal cohort of 97 patients. Under fine-grained supervision, all backbones achieved AUROCs of 92.71%-94.11%. Under weak supervision, seven retained 91.92%-93.77%, whereas native DINOv2 ViT-B/14 declined to 78.29% ± 17.92%. Gastrointestinal continuation self-supervision on 480,000 to 4.8 million GastroNet-5M images restored AUROC to 91.64%-93.25%. The 480,000-image, 50,000-step configuration reached 92.92% ± 0.50%, only 0.33 percentage points below the highest mean. Intermediate supervised fine-tuning on 10,662 HyperKvasir images raised native DINOv2 ViT-B/14 AUROC to 91.76% ± 0.97% but changed already robust backbones little. Patient-level weak supervision therefore exposes representation-specific transfer instability. Effective domain adaptation was possible with sub-million-scale unlabeled data or a smaller labeled gastrointestinal task, but its benefit depended on the starting representation.

  • BoardDP-24

    基於 nnU-Net 之心臟電腦斷層影像多類別自動分割可行性研究

    許倖諴1, 季祖明1, 邱禹瑞1, 劉彥瑋1, 楊珮菁 (Pei-Ching Yang)1,2

    Affiliations: 1長榮大學資訊工程學系 2長榮大學人工智慧研究中心

    Keywords: nnU-Net, 心臟電腦斷層, 醫學影像分割, 深度學習, Dice

    Paper #109 · Computer Vision & Multimodal

    Abstract

    心臟電腦斷層可提供高解析度之三維心臟結構資訊,但人工逐層標註心肌、瓣膜與鈣化區域耗時且高度仰賴專業經驗。本研究目的為初探以 nnU-Net v2 建立心臟 CT 多類別自動分割流程,採 3D Full Resolution 組態與五折交叉驗證進行 1000 epochs 訓練。訓練資料共 50 例,每折使用 40 例訓練與 10 例驗證;五折 Mean Validation Dice 分別為 0.5615、0.5562、0.5640、0.5619 與 0.5627,平均為 0.5613。另以五折集成模型對 50 例具參考標準標註之測試影像進行評估,心肌、瓣膜 與 鈣化之 Dice 分別為 0.9226±0.0144、0.7388±0.0424 與 0.0000±0.0000,三類別平均 Dice 為 0.5538。進一步分析發現 calcium 僅出現在 10 例測試資料中,且前景體素數遠少於 muscle 與 valve,模型未預測出任何 calcium voxel,顯示極端類別不平衡仍是本資料集之主要挑戰。研究結果說明 nnU-Net 對心肌與瓣膜具有良好分割能力,但鈣化區域仍需透過資料增補、損失函數調整或取樣策略改善。

–

IO5 · – · Room A · 2F Lijing Hall A

International Oral Session 5

Topics: LLMs & NLPData Mining & ForecastingComputer Vision & Multimodal

Session chair: Prof. Wen-Hung Liao (National Chengchi University) · 4 papers

  1. Matching Digits or Quantities? A Controlled Diagnostic Benchmark for Cross-Source Verification of Traditional Chinese ESG Disclosures

    Chenxuan Zhou, Jian Song, Christy Jie Liang

    Affiliations: University of Technology Sydney, Australia

    Keywords: ESG disclosure, Green finance, Numeric verification, Diagnostic benchmark, Agent evaluation, Traditional Chinese

    Paper #21 · Data Mining & Forecasting

    Abstract

    Companies listed in Taiwan publish each sustainability indicator twice: in a narrative report, and as a structured record, on the exchange's ESG platform, that declares the figure's boundary. Given a report passage and a filing record for one indicator, a system answers Supported, Contradicted, NotComparable (not shown to be the same quantity) or NotApplicable (not filed); it must thus check whether two figures denote the same quantity, not merely whether their digits agree. We build a controlled diagnostic benchmark whose gold comes from the filings, fixed text rules and a ledger of injected changes, with no human or model judgement: 3,483 digit-exact anchors from 885 companies yield 3,000 perturbed items, and a 95-item panel substitutes whole records that keep their own indicator label. We run one reasoning model, kimi-k2.7-code (with kimi-k3, of the same provider, on the panel), in four configurations, from page text to an adversarial four-role pipeline. On the 88 items all four answered, admissible accuracy, which credits every verdict the task rules allow, ranges from 0.784 (pipeline) to 0.886. Substituted values are rarely affirmed (2 of 160 verdicts), and with neighbouring pages the model rejects a record that declares another indicator in 36 of 37 cases; the pipeline affirms 12 of 35. Of 16 unperturbed controls that a system rejected, five reveal a unit, definition or boundary mismatch that digit-exact anchoring had accepted: the digit matching we set out to detect was in our own construction.

  2. FUSE: A Fused Unified Synthetic-image Ensemble for AI-Generated Image Detection

    Ping-Chen Chung, Nguyen Huynh Phuoc Thien, Pei-Hua Tsai, Hsuan-Cheng Chu, Po-Wei Harn

    Affiliations: National Central University, Taiwan

    Keywords: AI-generated image detection, deepfake forensics, ensemble learning, diffusion models, CLIP, frequency analysis.

    Paper #68 · Computer Vision & Multimodal

    Abstract

    Modern generative models produce synthetic imagery nearly indistinguishable from real photographs. While these capabilities enable applications in creative content generation, they also introduce significant security and societal risks. This motivates the development of reliable methods for detecting AI-generated image. However, existing forensic detectors exploit a single class of artifact and fails outside its designated realm. A single detector that is trained to exploit artifacts associated with one generation paradigm may become a bottleneck when evaluated on another. In this paper, we present **FUSE** (Fused Unified Synthetic-image Ensemble), which fuses five complementary channels (UnivFD, NPR, FreqNet, and two DIRE variants) with a LightGBM meta-classifier that both combines and measures each channel's contribution. FUSE exposes a deployable scoring mechanism, a weighted score and a category OR-gate, so that channels can cover one another's individual failures. In the out-of-distribution evaluation on an unseen AI-generated versus real artwork domain, two fusion variants of FUSE ($0.550$ in weighted score and $0.580$ in OR-gate maximum) outperform the LightGBM meta-ensemble ($0.475$) in AUC. As for in-distribution and in-family benchmarks, FUSE's deployed weighted score reaches $0.94$--$1.00$ AUC across seven splits. An extended robustness study across all five channels shows that FUSE holds $0.985$ AUC under severe Gaussian blur ($\sigma{=}3$), where the semantic channel alone falls to $0.830$.

  3. Direction Echo: Redirecting Attention Flow to Mitigate Length-Induced Representation Collapse in Repetition-Based Language Model Embeddings

    Mu-Feng Tsai, Hung-Yu Kao

    Affiliations: National Tsing Hua University, Taiwan

    Keywords: text embeddings, large language models, causal attention, echo embeddings, length collapse, attention masking, zero-shot learning

    Paper #210 · LLMs & NLP

    Abstract

    Echo embeddings extract high-quality text embeddings from decoder-only LLMs by feeding the input twice and pooling over the repeated segment, requiring no training. We find, however, that this construction amplifies length collapse, the tendency of long-text embeddings to concentrate in a narrow region of the representation space regardless of semantic content. Our analysis traces the amplification to two structural properties of the echo construction. Pooling from the later segment places the pooled tokens at positions with greater smoothing capacity, and the echo-to-echo attention path forms a recursive smoothing loop in which the pooled segment repeatedly averages its own already-smoothed representations. We propose Direction Echo, a training-free method that blocks echo-to-echo attention with an additive mask, so that each echo token reads only the original input. This severs the recursive smoothing loop, mitigating the amplified collapse. On the Massive Text Embeddings Benchmark (MTEB) with Mistral-7B-Instruct, Direction Echo outperforms echo embeddings by 4.33 points on average, with a gain of 11.01 points on retrieval tasks, which typically involve longer inputs.

  4. Reviewed Aspects in Video Games Released from the 1980s to the 2020s

    Jotaro Tasaki, Kazushi Ikemachi, Ryosuke Yamanishi

    Affiliations: Kansai University, Japan

    Keywords: Video game reviews, Natural language processing, Dependency parsing

    Paper #104 · LLMs & NLP

    Abstract

    Evaluating video games is highly subjective, and understanding player perspectives requires analyzing both internal game mechanics and external contexts. Existing research on game reviews often overlooks how multi-layered contexts, such as historical release eras and age ratings, dynamically influence player priorities. To address this gap, this study constructs a comprehensive dataset linking game metadata—including genres, release dates, and age ratings—with 121,787 user reviews across 8,197 video games. Utilizing traditional dependency parsing for transparency, we extract target features (subjects) and their associated evaluation content (predicates) to systematically analyze what players focus on and how they express their evaluations. Our analysis revealed that while fundamental features like "enemy'' and "difficulty'' are universally evaluated across all genres, specific genres heavily emphasize unique, thematic focus points. Furthermore, tracking reviews by release date showed a shifting trend: player focus on hardware-driven elements like graphics has declined, while the importance of narrative elements has significantly increased over time. Comparisons across age ratings indicated that narrative intensity and mature themes become more prominent in titles aimed at older audiences. This paper indicates how a game's multifaceted context dynamically shapes player evaluation criteria.

DO5 · – · Room B · 2F Lijing Hall B

Domestic Oral Session 5

Topics: LLMs & NLPComputer Vision & Multimodal

Session chair: Prof. Minghsiang Su (Soochow University) · 5 papers

  1. Deepfake 偵測模型於多強度影像退化下之穩健性與方向性誤判分析

    張祐齊 (Yu-Chi Chang), 吳孟倫 (Meng-Luen Wu)

    Affiliations: 淡江大學資訊工程學系

    Keywords: Deepfake 偵測, 影像退化, 穩健性, 固定分類門檻, 方向性誤判, Vision Transformer, CLIP

    Paper #29 · Computer Vision & Multimodal

    Abstract

    Deepfake 影像在社群平台傳輸與重新編碼的過程中可能會經歷壓縮、模糊與色彩調整,使原本可被正確辨識的偽造內容逃過偵測,或使真實內容被誤判。本研究在固定分類門檻下量測這類輸入變化對偵測模型的影響,並區分錯誤往誤判或漏判的方向增加。結果顯示,AUC 幾乎不變時,固定分類門檻下的誤判與漏判仍可能大幅上升。

    本研究在 HiDF 上以相同資料切分與評估條件比較 ResNet-50、ImageNet ViT-B/16 與 CLIP ViT-B/16,每種模型各以三個隨機種子訓練,並在七類多強度輸入變化下評估,其中五類為影像退化、兩類為診斷性變化(High-pass 與半臉遮擋)。分類門檻由乾淨驗證集以 Youden's J 選定後固定套用至所有輸入條件。評估指標為 AUC、Balanced Accuracy、FPR 與 FNR。

    在 198 個非 Original 的模型–輸入條件組合中,31 個(15.7%)的 AUC 平均下降不超過 2 個百分點,但 FPR 或 FNR 平均增加至少 10 個百分點。ImageNet ViT 在 JPEG Q90 這一視覺上幾乎無損的壓縮強度下,平均 AUC 由 97.68% 降至 96.85%,FPR 卻由 5.64% 升至 18.32%。色偏的落差則集中於漏判方向:ResNet-50 的 FNR 隨暖色偏移強度由 4.05% 單調升至 49.84%,而 AUC 全程維持在 96.62% 以上。錯誤上升的方向隨輸入變化與模型而異,誤判與漏判在部署上對應不同的風險。

  2. A Hybrid LLM–RL Framework for Army Tactical Decision Support: Evaluation in a Real-Time Strategy Simulation

    Yu Rui Shi1, Zong Xin Lin1, Yi Syuan Lu1, Cheng Shun Lee1,2

    Affiliations: 1R.O.C. Military Academy, Taiwan 2National Cheng Kung University, Taiwan

    Keywords: Reinforcement Learning, StarCraft II, Agent Training, Large Language Model

    Paper #145 · LLMs & NLP

    Abstract

    Modern military tactical training and scenario simulation require adaptable, risk-free environments to formulate doctrine-aligned strategies, moving beyond the prohibitive costs and safety constraints of traditional live-fire exercises. While reinforcement learning (RL) has demonstrated effectiveness in micro-level action optimization, it often lacks macro-level strategic reasoning and doctrine interpretability. To bridge this gap, this paper proposes a hierarchical hybrid framework integrating a locally hosted Large Language Model (LLM) with tabular Q-learning, validated in the StarCraft II (PySC2) real-time strategy simulation environment. In our framework, military doctrines (FM 3-0 and ADP 3-90) are incorporated via Retrieval-Augmented Generation (RAG) to generate structured high-level tactical objectives at macro intervals. These objectives direct an RL action executor, supported by a novel zone-control reward shaping mechanism defined over an 8×8 discretized spatial grid. Experimental results demonstrate that the hybrid agent progressively develops proactive territorial control behaviors and achieves consistent improvements in zone control scores across 2,448 training episodes. This study demonstrates the feasibility of combining doctrine-grounded LLM reasoning with RL execution, offering an interpretable and cost-effective paradigm for AI-driven tactical decision-support systems.

  3. An Effective Spoken Language Understanding Approach Leveraging Query-Adaptive Intent Detection

    Bing-Long Kuo1, Yu-Hsuan Fang1, Tien-Hong Lo1, Hsueh-Wei Liao2, Berlin Chen1

    Affiliations: 1National Taiwan Normal University, Taiwan 2Realtek, Taiwan

    Keywords: Spoken language understanding, large language models, in-context learning, prototype-guided retrieval, intent detection

    Paper #52 · LLMs & NLP

    Abstract

    Large language models enable fine-tuning-free spoken language understanding (SLU) through in-context learning, but direct query-based retrieval may select semantically similar yet intent-irrelevant demonstrations. This paper presents Query-Adaptive Intent Detection via Prototype Extraction (APEX), a two-stage retrieval framework that first selects candidate intents using intent-level prototypes and then retrieves contextual exemplars within the selected intent space. Experiments on the SLURP dataset evaluate joint SLU performance using Exact Match Accuracy (EMA) under full-transcript and perplexity-stratified conditions, with additional retrieval analysis on ASR-generated transcripts. Compared with query-based retrieval, APEX improves EMA by 4.34 and 3.97 percentage points with Qwen3-4B and Gemma-3-4B, respectively, on full transcripts. Under high-perplexity inputs, APEX also yields EMA gains of 7.66 and 2.13 percentage points. Retrieval analysis further indicates that prototype-guided candidate selection achieves higher ground-truth intent coverage across multiple input conditions.

  4. PlainSCOTUS: A Sentence-Aligned Corpus for Legal Text Simplification

    Yun-Mao Lo, Meng-Luen Wu

    Affiliations: Tamkang University, Taiwan

    Keywords: legal text simplification, sentence alignment, parallel corpus, comparable corpora, BGE-M3, margin-based scoring, dataset construction

    Paper #27 · LLMs & NLP

    Abstract

    Data-driven legal text simplification is bottlenecked by data: the few parallel legal resources that exist align whole documents, sections, or statutes, not individual sentences, and so cannot supervise sentence-level models. We release the first sentence-aligned parallel corpus built on U.S. Supreme Court (SCOTUS) material—2,613 filtered pairs that match plain-language Oyez case summaries to the Court's full opinions from the Pile of Law. Instead of generating simplifications with a language model, which leaves no reusable corpus and can hallucinate in a high-stakes domain, we mine pairs from summaries that human editors already wrote. Our pipeline pairs documents, segments them with legal-domain sentence splitters, and aligns sentences with a bidirectional margin score that fuses the dense and sparse similarities of BGE-M3; crucially, it assumes no sentence ordering, which lets a single summary sentence match content scattered across a long opinion. A cross-encoder then rescores every candidate, and hard filters enforce the length, lexical-overlap, and readability-direction properties a simplification pair must have. On the released corpus the mean Flesch–Kincaid Grade Level drops from 19.0 to 14.3 and the mean cross-encoder relevance score is 0.89. Ablations across three design axes show the corpus is stable because the cross-encoder gate, not the margin, makes the final selection. We frame the result as a plain-language parallel corpus with a consistent readability gap—the summaries remain near college level—and intend it to support future training of legal simplification models.

  5. 應用變換式架構模型於華語轉換客家語

    洪士程, 王俊詠

    Affiliations: 朝陽科技大學資訊工程系

    Keywords: 變換式架構模型, 華語, 客家語, 網路爬蟲, 超參數優化, mt5模型

    Paper #4 · LLMs & NLP

    Abstract

    華語是具有華人共同語言地位的通用語,客家語則是漢語族中的一支獨立語言,具備自身獨特的音韻系統與詞彙。本篇論文採用變換式架構模型,針對華語及客家語進行字詞間的翻譯,開發適合客家話特徵的翻譯模型,以提升翻譯的準確性和自然性。我們採用了二種基於變換式架構模型, mT5-small 和 mT5-base 模型,在華語與客家語之間進行翻譯。結透過變換式模型在結合層正規化調整與梯度裁剪技術,能顯著提升翻譯的品質。實驗結果顯示,當 mT5-small 模型結合上述技術後,在 BLEU、ChrF 和 TER 指標上均取得了顯著的提升,顯示出更準確且更流暢的翻譯效果。尤其是梯度裁剪的技術穩定了訓練過程,進而產生了更高質量的翻譯結果。針對更大規模mT5-base 模型的實驗結果顯示,翻譯性能得到了更大的提升。mT5-base 模型擁有更大的容量,使其能在華語與客家語之間提供更細緻的翻譯,並在各項 BLEU 指標上取得了更高的分數。

PS5 · – · Poster Area · 2F Liquan Hall exhibition area

Poster Session 5 (International)

Topics: LLMs & NLPSecurity & Trustworthy AIComputer Games & Game AI

Session chair: Prof. Te-Chuan Chiu (National Tsing Hua University) · 10 papers

  • BoardIP-21

    Measuring and Repairing NLI Sensitivity to Emoji and Informal Markers

    Avinash Goutham Aluguvelly

    Affiliations: University of Texas at Austin, USA

    Keywords: Averages Conceal Where Accuracy Is Lost: Emoji Substitution and Appended Phrases in Natural Language Inference

    Paper #50 · LLMs & NLP

    Abstract

    Small edits, such as replacing the word dog with or ap- pending the informal phrase no cap to a hypothesis, should not change the label of a natural language inference (NLI) pair, yet they can change the prediction of a fine-tuned classifier. We study two kinds of edit on SNLI and MultiNLI with six fine-tuned encoders: the substitution of 16 nouns by emoji, and the appending of nine informal markers. On average, emoji substitution lowers accuracy by 2.54 to 4.94 points per encoder and appended markers lower it by 4.91 to 12.83 points, but these averages conceal where the accuracy is lost. For emoji, the loss depends on how the replaced nouns are distributed over the two sentences and much less on which noun is replaced. On SNLI it is below one point when the same noun is replaced in both sentences. It is 18 to 24 points for five of the encoders when the premise and the hypothesis contain different replaced nouns. For markers, the loss comes from a few phrases and not from informality as such. Five of nine informal markers cost no more than control phrases, whereas by heaven, which is not informal, changes 39.2% of predictions, more than any marker. A measure that needs no labels ranks the phrases as accuracy does. The two losses also need different fixes: mapping emoji back to nouns at inference removes the emoji loss, and training on other markers recovers 72.1% of the loss on held-out markers. Robustness evaluations should therefore report effects within an edit type and not only its average.

  • BoardIP-22

    Humans and LLMs: Role Inference under Varying Information Availability in the Werewolf Game

    Taiki Takiuchi, Takeshi Ito

    Affiliations: The University of Electro-Communications, Japan

    Keywords: Werewolf game, Large Language Models, Inference.

    Paper #131 · Computer Games & Game AI

    Abstract

    This pilot study examined how information availability relates to role-inference performance by novice humans and large language models (LLMs) in the Werewolf game. Using six logs from five-player games, we compared Target-Role Accuracy at two game stages and classified four logs into Types I–IV accord-ing to their information structures. We evaluated three OpenAI models: gpt-5.6-sol, gpt-5.6-terra, and gpt-5.6-luna, with 10 trials per model. In Quiz 4, where ex-plicit evidence was more abundant, the LLM group showed descriptively higher accuracy than the human group in both temporal settings, although neither differ-ence was statistically significant after Holm adjustment. In Quiz 2 for the specific Type IV log, where objective cues were scarce, the human-group mean was 48.3%, compared with 16.7% for the three-model mean. This result does not establish a general human advantage under low-information conditions. Among the seven par-ticipants analyzed for Type IV, mean accuracy increased from 43% on Day 1 to 86% on Day 3 after game experience and repeated presentation. However, the change was not statistically significant (p = 0.25), and only three participants im-proved. Exploratory analysis suggested that LLM errors often reflected interpreta-tions of active behavior as Villager-like, whereas some humans came to consider the strategic intentions behind utterances. Because each type was represented by one log and the human sample was small, these findings are preliminary and lim-ited to the conditions studied. Further research using more participants and inde-pendent game logs is needed to determine whether these patterns generalize.

  • BoardIP-23

    Agentic Workflow Automation for n8n: Prompt Engineering, Domain Fine-Tuning, and a Comparative Case Study

    Zhi-Ying Wang, Hsuan-Yu Liu, Chun-Yao Lin, Wen-Hsien Huang, Chia-Hui Chang

    Affiliations: National Central University, Taiwan

    Keywords: Large Language Models, Workflow Automation, Agentic AI, Fine-tuning, n8n, Natural Language Programming

    Paper #38 · LLMs & NLP

    Abstract

    This paper studies how large language models (LLMs) can enable natural-language workflow construction and editing on the n8n automation platform. We compare six prompt-engineering strategies on GPT-4.1 against three domain fine-tuning input representations across GPT-4.1, Qwen2.5-Coder 32B, and Gemma 2 27B on a shared 300-template benchmark. Structured, plan-based fine-tuning substantially improves schema-grounded generation over the best prompting approach, raising Connection F1 from 0.254 to 0.543 and Parameter Accuracy from 0.273 to 0.450. Building on this, we develop an agentic system that routes natural-language instructions to creation, insertion, or deletion pipelines, pairing the fine-tuned generator with deterministic programmatic control, and compare it with n8n's own Cloud AI Workflow Builder. The proposed system performs competitively on creation and substantially outperforms the official tool on node deletion (100\% vs. 46.7\%, $N=30$); insertion success is low for all three (5--15\%) from omitted parameter values, though ours best preserves untouched nodes (100\% vs. 66.7--86.7\%).

  • BoardIP-24

    Price Movement Prediction for High-frequency Trading by Leveraging Fine-tuned Large Language Model as Short-term Trend Indicator

    Fan-Yu Pu, Shiou-Chi Li, Jen-Wei Huang

    Affiliations: National Cheng Kung University, Taiwan

    Keywords: Price movement prediction, High-frequency trading, Large language model, Deep learning model

    Paper #114 · LLMs & NLP

    Abstract

    With the rapid advancement of deep learning, artificial intelligence (AI) applications in predicting financial asset price trends have diversified significantly. Accurate forecasts reduce risks and boost returns, particularly in volatile markets like cryptocurrencies, which offer abundant profit opportunities. However, high-frequency trading data, with its second-level fluctuations, poses challenges for models in handling fine-grained details and adaptability. To tackle these issues, this study introduces a novel hybrid architecture integrating a fine-tuned large language model (LLM) with a daily-retrained deep learning model. The LLM excels at extracting short-term market patterns from vast second-level historical data, addressing traditional models' limitations in retaining past patterns amid massive datasets. Conversely, the deep learning component adapts to long-term trends. To enhance prediction accuracy, we incorporate first-, third-, and fourth-order statistical moments to capture distributional characteristics of price fluctuations. The workflow involves feeding historical data into the LLM for signal generation, then combining these with statistical moments and cross-asset data to support the deep learning model's price movement predictions. Experiments demonstrate that our approach outperforms standard deep learning models, improving accuracy by 5\% to 25\%, confirming the architecture's efficacy.

  • BoardIP-25

    Structural Fidelity of Automated Multidimensional AI Judges for Earnings Call Argument Quality Assessment

    Wei-Hsi Sun, Yi-Ting Liao, Yi-En Liu, Min-Yuh Day

    Affiliations: National Taipei University, Taiwan

    Keywords: Structural Fidelity, LLM-as-a-Judge, Argument Quality Assessment, Multidimensional Evaluation, Earnings Calls

    Paper #155 · LLMs & NLP

    Abstract

    Assessing argument quality in earnings call statements is essential for interpreting the specificity, persuasiveness, strength, and objectivity of managerial communication. Yet strong performance on individual dimensions does not guarantee that an automated judge preserves the relationships among them. To address this gap, this study investigates the structural fidelity of multidimensional LLM judges and examines whether higher task performance corresponds to better preservation of human-referenced score relationships. We compare three judging systems, namely few-shot prompting, fine-tuning, and a post-hoc correction pipeline, using overall and OBJECTIVE-specific correlation distances, a conditional independence null model, and robustness analyses. The primary comparison is an exploratory analysis of these preexisting systems on a shared 359-statement development split, on which the pipeline's post-hoc rules were tuned. Human annotations exhibit a two-block pattern in which OBJECTIVE is comparatively weakly associated with SPECIFIC, PERSUASIVE, and STRONG. Relative to the observed human labels, most OBJECTIVE-related correlations are higher in the automated outputs, although this direction is sensitive to uncertainty and attenuation in the human reference, and on this split the fine-tuned system shows the largest OBJECTIVE-specific deviation, an ordering not reproduced on a 131-statement held-out subset. The observed comparisons suggest that higher Macro-F1 need not coincide with smaller reference-relative structural discrepancies. Controlled manipulations further show that joint elicitation raises overall but not detectably OBJECTIVE-specific coupling, while false-score disclosure produces only modest, dimension-dependent shifts. These findings extend multidimensional evaluation beyond criterion-level accuracy and provide a reference-based diagnostic for detecting cross-dimensional distortion. In practice, automated judges should be assessed using both predictive performance and structural behavior before they are used in evaluation or decision-support settings.

  • BoardIP-26

    Turning Books into SNS: Effects of Familiar Social Media-Style Reading Interfaces on Cognitive Load and Reading Performance

    Konosuke Tada, Junjie Shan, Megumi Yasuo, Yoko Nishihara

    Affiliations: Ritsumeikan University, Japan

    Keywords: Reading Support, Cognitive Load, Social Media Interface, Digital Natives, Reluctant Readers

    Paper #75 · LLMs & NLP

    Abstract

    While digital natives frequently read massive amounts of text on social media without fatigue, they often experience severe psychological aversion and cognitive load when confronted with dense, full-length book pages. Existing e-book designs primarily tweak low-level typography (e.g., font size, line spacing) but fail to address the initial visual dread of ``walls of text.'' In this study, we propose a novel reading support approach that transforms full-text literary novels into familiar social media interfaces---specifically modeling LINE (messaging app), X (microblog feed), and 5ch (bulletin board system, BBS)---alongside an e-book baseline. We modernized ten public-domain Japanese novels and evaluated reading behavior across 20 participants in an experiment with balanced novel--interface assignments, measuring page dwell time, reading speed, text comprehension, and subjective cognitive load (NASA-TLX-inspired 14-item questionnaire). The results reveal that while mean comprehension scores were descriptively similar across interfaces, the LINE-style messaging app interface received favorable subjective evaluations among reluctant readers. These findings suggest that familiar chat and feed layouts may make literary reading more approachable for digital-generation readers.

  • BoardIP-27

    The Steepest Derivative: AI Neuro-Persuasion as a Compounding Cognitive-Security Risk

    Aayush Gandhi

    Affiliations: DatumND, USA

    Keywords: AI safety, cognitive security, neuro-persuasion, persuasion, technology ethics, responsible AI, model loyalty

    Paper #173 · Security & Trustworthy AI

    Abstract

    Persuasion is becoming a machine capability. Randomized studies now find that language-model-written messages change political and factual attitudes at least as much as human-written ones, and this capability couples naturally to the behavioral and affective forecasting that a decade of engagement optimization already produces. We call this coupling AI neuro-persuasion and argue that it is best understood not as a new kind of manipulation but as a multiplier on manipulation that already exists. The contribution is a way to reason about where that multiplier does the most damage. We state a general principle, the steepest derivative: the marginal harm from each increment of persuasion capability is largest where three conditions coincide, a high baseline of organized manipulation, high population vulnerability, and the absence of \emph{model-level} auditing, the ability to test the systems themselves rather than only the content they emit. We treat the ``derivative, not level'' framing as an organizing device rather than a fitted model, and we show the three conditions are general by instantiating them across contexts, synthetic-media financial fraud, electoral information operations, personalized political targeting, and a focused multi-region case study where all three conditions are acute at once. We then add a measurable, cross-cutting vector: models aligned to a principal carry directional loyalties, and as users come to treat a chatbot as a neutral expert those loyalties become standing influence infrastructure. A secondary analysis of published refusal-rate data quantifies one instance, a state-aligned model refuses origin-sensitive prompts at a risk difference of $26$ to $31$ percentage points over comparable models (Cohen's $h = 0.74$ to $1.06$), with no matching elevation on the other side. We engage the counter-capacity that already exists, fact-checking, platform moderation, and media literacy, and argue why it does not reach the model level. As an existence proof that a defense is buildable and deployable by any body that needs one, we describe a small-model instrument coupling a behavioral forecaster with an abstaining cognitive-security check, validated on synthetic controls only and released as open, inspectable code. We make no claim to have measured persuasion in any named campaign.

  • BoardIP-28

    ShardedGold: Mitigating Gradient Mimicry Attack on Blockchain-Based Federated Learning

    Patcharawit Wilaikaew1, Wei-Zhe Xu1, Min-Te Sun1, Kazuya Sakai2, Wei-Shinn Ku3

    Affiliations: 1National Central University, Taiwan 2Tokyo Metropolitan University, Japan 3Auburn University, USA

    Keywords: Federated Learning, Blockchain, Gradient Mimicry Attack, Poisoning Defense, Gradient Sharding

    Paper #110 · Security & Trustworthy AI

    Abstract

    Blockchain-based Federated Learning (BCFL) remains vulnerable to gradient mimicry attacks, in which malicious clients imitate the behavior of honest ones. We study how such attackers degrade a BCFL system protected by FoolsGold and Multi-Krum, and propose ShardedGold, a defense that combines gradient sharding with an enhanced FoolsGold algorithm adding an Order-based penalty score and a Consistency score, and that stores shards in the InterPlanetary File System (IPFS) with on-chain Content Identifiers (CIDs) to overcome ledger storage limits. We evaluate the full attacker range from 0 to 50% of clients on MNIST and CIFAR-10 and compare against FoolsGold+Multi-Krum run through an identical pipeline. Under the evaluated protocol, ShardedGold keeps malicious clients' aggregation weight below that of honest clients and preserves accuracy up to moderate attacker fractions, degrading gradually beyond them, with accuracy on par with FoolsGold+Multi-Krum. Repeated runs further reveal a bimodal convergence instability that concentrates at intermediate attacker fractions rather than at the maximum, a pattern visible only across multiple runs.

  • BoardIP-29

    Comments Are Load-Bearing: Semantic-Preserving Obfuscation Evades Cheap LLM Smart-Contract Auditors

    Ruiyang Zhang

    Affiliations: Ryonix Labs, Canada

    Keywords: smart contracts, LLM security, vulnerability detection, adversarial robustness, evaluation methodology

    Paper #3 · Security & Trustworthy AI

    Abstract

    Large language models are increasingly deployed as smart-contract vulnerability auditors. We ask whether such auditors can be evaded by rewrites that provably do not change what a contract does. Using 130 labelled contracts from SmartBugs-Curated and SolidiFI across five vulnerability classes, seven LLM auditors spanning three model families, and six semantic-preserving source transformations (identifier renaming, dead-code insertion, comment stripping, control-flow rewriting, inlining, and reformatting) verified behaviour-preserving at a 99.7% rate by bytecode identity or differential execution, we report two findings. First, obfuscation does not degrade auditors on average - mean evasion is within +/-3 percentage points - but it opens specific, reproducible blind spots: on arithmetic bugs, stripping comments alone collapses the recall of a well-calibrated cheap auditor (Qwen2.5-7B) from 0.88 to 0.48 while its false-positive rate stays at 0.00, with non-overlapping bootstrap confidence intervals at n=33. Comments, not code, were carrying the detection. Second, and more troubling for the field, most auditors we test are degenerate: the largest model (Llama-3.3-70B) attains perfect reentrancy recall while flagging 93% of non-vulnerable contracts, i.e. precision 0.33. Because recall rewards indiscriminate flagging, a recall-only evaluation both overstates auditor quality and makes robustness-to-obfuscation unmeasurable - an apparent "capability confers robustness" correlation (rho = -0.82) is confounded by exactly this effect and is not statistically significant (p = 0.13, five models). Finally, the obvious mitigation fails: escalating to the largest model restores recall (0.46 to 0.96) but inflates false positives (0.00 to 0.26, and to 0.94 on reentrancy). We argue that LLM smart-contract auditors must be evaluated with precision alongside recall, and that cosmetic-robustness testing belongs in that evaluation.

  • BoardIP-30

    When Extra Reliability Signals Hurt: Selective Activity Recognition under Unseen Fault Families

    Nuwantha Senadhi Ranaweera, Savindu Dilshan Wickramasinghe, Thusith Wijewardena, H.W.P. Sandeepa

    Affiliations: University of Moratuwa, Sri Lanka

    Keywords: Human activity recognition, Selective prediction, Sensor faults, Distribution shift, Reliability estimation

    Paper #185 · LLMs & NLP

    Abstract

    Can observed signal quality and sensor-removal sensitivity reveal activity-classification errors under a sensor-fault family excluded from training and calibration? We test this hypothesis on UCI HAR while preserving its nine official test participants. For each of five simulated fault families, a compact CNN, three logistic correctness predictors, temperature scaling, entropy, and MC dropout exclude that family from every fitting stage. Three classifier seeds and paired corruptions cover 30 held-out family severity sensor-group conditions. Fault augmentation improves mean held-out accuracy from 67.7% to 71.0%, versus 89.9% on clean test windows. However, adding quality and removal features to the confidence-only correctness predictor worsens the prespecified area under the risk-coverage curve (AURC, lower is better) from 0.1473±0.0084 to 0.1681 ± 0.0110. The paired participant-bootstrap difference is +0.0208 (95% interval [+0.0116, +0.0297]). The expanded score helps for held out missing segments and noise, but fails for bias, gain, and freeze; it also raises error AUPRC from 0.560 to 0.574 and slightly lowers risk at 80% coverage, showing that ranking summaries need not agree. A 14k-parameter GRU and a reduced reconstruction-pretraining control, each run on a single seed, are consistent with the same negative AURC pattern. These results reject the broad hypothesis that inexpensive quality and removal signals reliably improve selective HAR under an unseen fault family, and identify family-dependent score transfer as the central obstacle.

–

IO6 · – · Room A · 2F Lijing Hall A

International Oral Session 6

Topics: LLMs & NLPAI Agents & RAGAI for Health

Session chair: Prof. Kuo-Chan Huang (National Taichung University of Education) · 6 papers

  1. Resolving Knowledge Conflicts in Versioned Documents via Agentic Evidence Synthesis and Hierarchical Dual-Store Retrieval

    Chao-Chun Chuang1, Chih-Min Yao1, Tsui-Mei Lee1, Yi-Ni Liu2

    Affiliations: 1National Institutes of Applied Research, Taiwan 2Chung Shan Medical University, Taiwan

    Keywords: Retrieval-Augmented Generation, Agentic AI, Knowledge Conflicts, Temporal Evidence Resolution, Multimodal Document Processing, Single Source of Truth

    Paper #85 · AI Agents & RAG

    Abstract

    Institutional collections evolve continuously through amendments, administrative memos, and budget revisions. In such versioned collections, standard Retrieval-Augmented Generation (RAG) can fail because retrieval optimizes semantic relevance rather than temporal or administrative authority. We study this problem on 27 government AI-infrastructure documents containing 92 embedded images and propose a two-phase framework combining offline scope-aware agentic evidence synthesis with online Hierarchical Dual-Store RAG. The offline pipeline performs multimodal inspection, temporal and scope-aware arbitration, and fresh-session auditing to construct a reviewed Single Source of Truth (SSoT), while the online architecture retrieves from both SSoT and archival stores under an explicit priority prompt. Multimodal inspection uncovered a 20-fold discrepancy between narrative text (NTD 20 million) and an operative table (NTD 1 million), while fresh-session review identified an erroneous budget growth rate of 37.7% and recalculated it as 41.8%. On a 100-question adversarial benchmark spanning three conflict modes and one factoid control category, the proposed configuration achieved an 85.0% automated answer-match rate, a +35.0 percentage-point gain over single-store hybrid RAG. Its retrieved-context budget is estimated to be approximately 83% smaller than full-context injection; this is not a measured end-to-end cost reduction. Exploratory inspection of non-matches and trap flags identified matching limitations, unused retrieved evidence, rubric misalignment, and residual numerical contamination. No independently validated semantic accuracy is claimed; the original automated scores remain the primary results. These findings support evaluating authority-aware evidence arbitration alongside online retrieval in evolving document repositories.

  2. When Case-Disjoint Evaluation Is Not Subject-Disjoint in EEG Seizure Forecasting

    Swastik Nanda1, Rohan Sharma2, Kevin Zhu2

    Affiliations: 1Stanford University, USA 2Algoverse AI Research, USA

    Keywords: EEG, seizure forecasting, subject leakage, evaluation, transformers, biomedical artificial intelligence

    Paper #203 · AI for Health

    Abstract

    Reliable cross-patient evaluation in electroencephalography (EEG) seizure forecasting requires more than disjoint case identifiers. We audit two evaluation protocols on the CHB-MIT scalp EEG database and show how a benchmark can appear patient-disjoint while violating biological subject separation and concentrating all positive test support in one case. On an original three-way split, the strongest transfer-pretrained configuration achieved validation AUROC 0.810 and AUPRC 0.170 but test AUROC 0.535 and AUPRC 0.0158. A later unified split, used for transformer, CNN, and BENDR comparisons, produced pooled window-level AUROC 0.9890 and AUPRC 0.4617 with corrected normalization. However, CHB-MIT documents chb21 as a later recording from the same biological subject as chb01; the unified protocol places chb01 in training and chb21 in testing. In addition, all 1,174 retained positive test windows came from chb24, while chb20–chb23 contributed only retained inter-ictal windows under the preprocessing pipeline despite public case summaries documenting seizures in each case. Because 98.82% of the unified test negatives come from chb20–chb23, the pooled AUROC is numerically dominated by cross-case positive–negative comparisons and cannot establish within-subject or multi-subject positive-class generalization. We further examine normalization, score compression, temporal aggregation, time-to-onset behavior, and window-level uncertainty, and derive a practical audit checklist for rare-event biomedical time-series evaluation.

  3. Towards Reliable Chinese Spelling Correction: Consensus-Based Correction under Linguistic Variation

    Cen-Chieh Chen1, Yu-Chen Hsu2, Berlin Chen1, Tao-Hsing Chang2, Yao-Ting Sung1

    Affiliations: 1National Taiwan Normal University, Taiwan 2National Kaohsiung University of Science and Technology, Taiwan

    Keywords: Chinese Spelling Check, Consensus-based Models, Ensemble Learning, False Positive Reduction, Linguistic Variation, Pre-trained Language Models, Text Correction Reliability

    Paper #214 · LLMs & NLP

    Abstract

    False-positive corrections remain a critical barrier to deploying Chinese Spelling Check (CSC) systems in real-world educational and language-processing set-tings. Incorrectly modifying valid expressions can adversely affect learning, data quality, and downstream knowledge construction. This study examines the benchmark–real-world gap arising from natural language variation, identifying character variants, fixed expressions, and Traditional–Simplified Chinese coexist-ence as major sources of false positives and data inconsistency. To address these challenges, we propose a consensus-based framework integrating heterogeneous models and applying corrections only when both agree, thereby improving relia-bility. Experimental results achieve a false-positive rate of 0.293, 98.2% preci-sion, 66.2% recall, and 79.1% F1-score, demonstrating the trade-off between cor-rection reliability and error coverage. Contributions: (1) deployment-oriented false-positive control; (2) analysis of contextual linguistic variations; and (3) a robust, high-precision consensus-based CSC framework.

  4. LAWRENCE: A Benchmark for Adversarial Lawyering in Taiwanese Criminal Law

    Yu-Kai Guo, Wei-Cheng Lai, Chen-Wei Hsu, Hung-yi Lee

    Affiliations: National Taiwan University, Taiwan

    Keywords: Large language models, Multi-agent systems, Courtroom simulation, Legal argumentation, LLM-as-a-judge

    Paper #180 · LLMs & NLP

    Abstract

    Existing legal benchmarks for LLMs focus mostly on answering legal questions, including multiple-choice questions, classification, judgment prediction, and document drafting. Although courtroom simulations of legal practice have been studied, they mostly use the debate as a means or study the simulation itself, and rarely score the advocates in it as a large-scale benchmark. We propose LAWRENCE (LAWyering under adversarial debate, evaluated on Reasoning, Engagement, Normative Correctness, and Ethics), a framework and evaluation method in which a multi-agent system simulates legal practice through adversarial debate grounded in real Taiwanese criminal judgments. With prosecutor, defense counsel, and judge agents, we ran roughly 1,000 simulated courtroom debates, comprising about 20 million Chinese characters, under both self-play and fixed opponents drawn from different models. The LLM judge we selected reaches a Pearson correlation of $+0.829$ with a human evaluator on the weighted total, averaged over the two sides (single evaluator, single case). The leaderboards indicate the broad standing of models, but their noise prevents a precise measure of model ability; we therefore analyze this noise, find that run-to-run noise arises mainly from debate generation, and identify directions in which the debate framework and the judge agent can be improved. This study thus represents an initial attempt at using adversarial debate over legal practice as a standard of evaluation.

  5. FIVE: Fixed-Prefix Failure Prediction for Tool-Using LLM Agents from Visible Trajectory Evidence

    Tomorn Soontornnapar1, Marius Herzog2, Tuchsanai Ploysuwan1, Kay Rottmann2

    Affiliations: 1King Mongkut's Institute of Technology Ladkrabang, Thailand 2Hochschule der Medien, Germany

    Keywords: LLM Agents, Early Failure Prediction, Multi-Domain Evaluation

    Paper #181 · AI Agents & RAG

    Abstract

    Tool-using large language model agents may reveal failure evidence before task completion, yet pooled prediction can be confounded by domain identity and variable trajectory length. We present FIVE (Failure Inference from Visible Evidence), a prefix-only framework that converts the first $K$ scored events into deterministic process evidence and estimates eventual failure with a conventional classifier. FIVE denotes the complete protocol, while FIVE-30 is its 30-feature representation: Core-18 summarizes step quality, drift, and information gain, and Relation-12 captures grounding, evidence use, repetition, action diversity, effort, and error persistence. Outcome labels are observed only after run completion, but each prediction at $K$ uses no future events and can be updated incrementally during execution. We evaluate FIVE on 400 $\tau^2$-Bench runs comprising 8,372 post-request scored events using task-grouped cross-validation, with test tasks excluded from model fitting. FIVE-30 provided moderate discrimination with full coverage at $K=3$, but a comparable domain-prior baseline showed that domain composition materially influenced pooled performance. At $K=20$, relational features improved all four classifiers, although coverage fell to 34.25%; fully nested selection yielded a more conservative AUROC of 0.686. FIVE therefore offers a transparent, cohort-aware framework for online failure-risk estimation that can support early stopping or escalation; the benefit of acting on these predictions requires prospective evaluation.

  6. Calibrated Hierarchical Structured Decisions for SASB Compliance Evidence in Sustainability Reports

    Wei-Chen Huang, Min-Yuh Day

    Affiliations: National Taipei University, Taiwan

    Keywords: SASB, Sustainability Reporting, Hierarchical Structured Decisions, Compliance Evidence Classification, Threshold Calibration

    Paper #209 · LLMs & NLP

    Abstract

    Sustainability reports are increasingly used to assess corporate environmental, social, and governance performance, yet evidence required by sector-specific sustainability disclosure standards is often fragmented across narrative text, tables, footnotes, and image-based PDF content. Existing page-level classification approaches typically rely on flat relevance or multi-class decisions, making it difficult to explicitly distinguish between irrelevant evidence and relevant but incomplete disclosure evidence. This study therefore proposes a calibrated hierarchical structured decision framework that decomposes SASB compliance evidence classification into two sequential dimensions: topical relevance and evidence completeness. Using 378 annotated records from Chinese sustainability reports, the framework integrates native PDF text and OCR-enhanced evidence and compares a character n-gram TF–IDF baseline, flat structured classification, and hierarchical structured decisions; decision thresholds are selected exclusively from training data using five-fold cross-validation. On the 189-record exploratory test split, the proposed framework achieves 73.02% accuracy and 60.39% macro-F1, compared with 46.03% accuracy and 35.12% macro-F1 for the strongest TF–IDF baseline, while the yes but not complete class remains challenging with an F1-score of 27.59%. Ablation results suggest that threshold calibration, which the flat baseline did not receive, accounts for most of the gain over flat classification; these findings remain exploratory. The main contribution of this study is to advance SASB compliance evidence classification from flat page-level labeling toward a calibrated hierarchical structured decision paradigm that explicitly models relevance and completeness as distinct decision dimensions, thereby improving transparency and auditability. The practical implication is that ESG analysts and assurance teams can apply the framework as a human-in-the-loop triage mechanism to prioritize clear cases and route incomplete or uncertain disclosures, together with preserved source-page evidence, for targeted verification.

DO6 · – · Room B · 2F Lijing Hall B

Domestic Oral Session 6

Topics: AI Agents & RAGLLMs & NLPOptimization, Theory & RLData Mining & Forecasting

Session chair: Prof. Shing-Tai Pan (National University of Kaohsiung) · 7 papers

  1. When Does a Two-Phase WEF1T Allocation Satisfy WEF1? Structured Experiments and Local Repair

    Chi-Hsuan Wu, Chuang-Chieh Lin

    Affiliations: National Taiwan Ocean University, Taiwan

    Keywords: Envy-freeness, Fair division, Social welfare.

    Paper #42 · Optimization, Theory & RL

    Abstract

    We study weighted envy-freeness up to one item (WEF1) for additive mixed goods-and-chores allocation with unequal entitlements. A good is an item that all agents evaluate positively, while a chore is a task with negative value for all agents, such as cleaning a restroom. The mixed setting is difficult because positive and negative items interact after normalization by agent weights: a fairness witness that works for the goods subproblem or the chores subproblem need not remain valid after the two parts are merged. We start from the known two-phase construction of Garg and Sharma (2024), which guarantees weighted envy-freeness up to one transfer (WEF1T) after merging goods-side and chores-side WEF1 allocations. This known guarantee is not a WEF1 guarantee, and we do not claim it as our own algorithmic contribution. Our contribution is an empirical study of when the merged allocation is already WEF1 and when local repair helps. Our experiments specify ordinary and structured goods-ratio generators, run 3,600 trials in each regime, report confidence intervals, repair depth, repair baselines, runtime, and welfare effects, and include a small instance demonstrating a local-search failure. Ordinary random trials produce no WEF1 failures. Structured trials expose 217 initial failures, and best-improvement repair fixes those failures in one step in this set of instances. The results show that the goods ratio \(r=|G|/|M|\), where \(G\) denotes the set of goods and \(M\) the set of all items, is not a reliable predictor of WEF1 success. Difficulty arises from the interaction of the goods ratio, entitlement configuration, concentrated desirable goods, and high-cost chores.

  2. 非獨立同分布數據對聯邦學習的影響分析

    洪士程, 賴胤佑

    Affiliations: 朝陽科技大學資訊工程系

    Keywords: 聯邦學習, CIFAR-10, CIFAR-100, 預訓練, 伺服器學習

    Paper #7 · Data Mining & Forecasting

    Abstract

    近年來,數據呈現出越來越分散的趨勢,導致眾多分佈式數據庫的出現。Google提出了一種名為聯邦學習的新型機器學習方法,該方法在保護本地數據隱私的基礎上,實現多方協同訓練機器學習模型。然而,在傳統聯邦學習方法中,伺服器通常不直接參與訓練任務。本篇研究聚焦於伺服器是否可以參與訓練過程的可行性,特別是針對伺服器提供部分數據集或持有專屬數據集的場景進行探討,以最大程度地發揮伺服器在計算能力上的優勢。本研究引入了兩種學習方法來獲取更優的模型性能。第一種方法為預訓練策略,該方法中伺服器首先在本地完成多輪訓練以生成初始模型,然後將其分發給所有客戶端節點進行深度學習。第二種方法則是訓練中的學習策略,即伺服器在每輪聯邦學習聚合後,利用自有數據集執行單輪本地訓練,以進一步優化模型性能。為驗證提出方法的有效性,本研究使用了CIFAR-10與CIFAR-100這兩個數據集進行實驗分析,探討了伺服器參與聯邦學習過程的可行性,同時對這兩種學習方法在提升模型性能方面的表現進行了比較和評估。

  3. 程式設計課程中大型語言模型之對抗性測資生成

    姜柏仰, 吳宜鴻

    Affiliations: 中原大學資訊工程學系

    Keywords: 大型語言模型, 測資生成, 擴展有限狀態機, 擴展巴科斯範式

    Paper #22 · LLMs & NLP

    Abstract

    本研究提出結合表示法與錯誤回饋的大型語言模型測資生成流程。四項作業、每種方法三次、每組20筆測資的結果顯示,EBNF平均初始與兩階段整體錯誤現象數最高,為11.00與19.25;EFSM平均對抗性與新增錯誤現象數最高,為13.25與10.25,觀察及完整錯誤揭露率最高,為28.76%與25.74%。研究結果顯示,相較於直接生成,表示法引導的提示設計能提升錯誤揭露能力,其中 EFSM 在對抗性測資階段具有較佳的補充效果。

  4. 提示微調結合自訓練技術於少樣本情緒原因組合提取

    簡瑋霆, 吳宜鴻

    Affiliations: 中原大學資訊工程學系

    Keywords: 情緒原因組合提取, 自訓練, 提示微調

    Paper #80 · LLMs & NLP

    Abstract

    情緒原因組合提取任務(Emotion-Cause Pair Extraction, ECPE)需要找出文檔中所有的情緒子句與原因子句,也要判定二者的對應關係。因此,標註成本與品質需求都很高。大多數相關研究著重在監督式學習下提升提取結果的準確度,本研究則針對在少量已標註文檔的環境下,利用佔多數的未標註文檔提升ECPE任務的表現。我們結合提示微調(Prompt-Tuning)與自訓練(Self-Training)的技術,透過提示微調可同時進行多個預測任務的特性,讓我們能統合不同任務的偽標籤在自訓練過程中,並在此架構上提出子任務模型參數融合的做法。

  5. Can We Trust LLM Agents as Playtesters? A Benchmark of Behavioral Diagnostics for Monetization Design

    Szu-Yu Chou, Ting-Kang Wang, Yueh-Po Peng

    Affiliations: Gamania Digital Entertainment Co., Ltd., Taiwan

    Keywords: multi-agents, LLM, IAP

    Paper #166 · AI Agents & RAG

    Abstract

    Large language model (LLM) agents are increasingly employed as simulated players for evaluating game designs. Existing agent benchmarks, however, primarily measure task success rather than behavioral consistency with an assigned player persona. This paper introduces IAP-Bench, a benchmark that evaluates persona-conditioned agents on in-app purchase (IAP) designs prevalent in free-to-play games. Four personas, defined by spending tier, are specified with explicit rules that are verified automatically. Four LLMs are evaluated on 14 conditions and on four variants of a single offer, yielding 5,760 decisions, and one small model is included for contrast. The four models exhibit strong agreement on the perceived fairness of offers, with a mean pairwise Spearman’s ρ of 0.92, but only moderate agreement on purchase rankings, with ρ = 0.62. Rule violations occur in 0.9% of scenario decisions and in 3.2% of design-study decisions. The absolute rule of never paying is almost always observed, whereas the conditional rule that prohibits one-time rescue items is violated in 0.8–8.9% of the minnow’s decisions. The contrast model, Gemma 3 4B, violates its rules in 21% of decisions, compared with 0.2–3.3% for the four main models. The results indicate that capable LLM agents reflect distinct player types and can support the analysis of monetization designs.

  6. 基於階層式記憶與雙代理協同之個人化食譜推薦機制

    郭馨妤, 王佳佳, 林其誼

    Affiliations: 淡江大學資訊工程學系

    Keywords: LLM Agent, 記憶機制, 個人化推薦

    Paper #132 · AI Agents & RAG

    Abstract

    本研究針對LLM Agent應用於個人化食譜推薦系統中,大多缺乏能同時兼顧長期穩定偏好、短期情境需求與偏好漂移衝突之結構化記憶管理機制,致使長期互動下的使用者理解難以維持一致與準確的問題,設計一套具動態偏好適應能力的管理機制。系統採Main Agent與Preference Analyzer的雙Agent架構,並將使用者資訊分為硬性限制、長期軟性偏好與短期狀態三層記憶,同時結合偏好更新門檻、Confidence評估及指數衰減機制,依據使用者互動訊號與時間變化調整偏好記憶。研究透過明確陳述、隱含推論、矛盾訊號及情境需求四種情境進行功能測試。結果顯示,系統能依據不同類型的使用者訊號更新或保留偏好,逐步處理偏好變化,並避免將一次性的情境需求納入長期記憶。未來可進一步整合更多行為資料,並延伸至跨會話飲食規劃與主動推薦。

  7. 導入語意之ERP Agent:基於 WebMCP 的跨文件流程

    陳禹璋, 謝文川

    Affiliations: 國立高雄科技大學智慧商務系

    Keywords: 大型語言模型代理, 企業資源規劃, WebMCP, 企業語意

    Paper #152 · AI Agents & RAG

    Abstract

    大型語言模型代理 (Large Language Model Agent, LLM Agent) 已逐步具備工具使用與任務執行能力,如何將其整合至企業資訊系統成為值得探討的議題。本研究以 SAP S/4HANA 銷售與配銷 (Sales and Distribution, SD) 模組為驗證情境,建構一套基於 WebMCP 的 ERP Agent 原型架構,讓使用者無須直接操作 ERP 原生介面,即可透過自然語言提出需求,由 Agent 利用網頁提供的功能與 SAP OData 執行跨文件查詢並呈現結果。 本研究進一步比較技術導向、型別導向與語意導向三種工具描述,探討企業語意對 Agent 任務執行的影響。結果顯示,在較寬鬆的操作額度下,三組皆具有較高的任務完成率;當限制至最少必要操作數時,各組在工具選擇與執行路徑上呈現差異,但未達統計顯著。研究顯示,WebMCP 具備整合 ERP Agent 的可行性,而企業語意雖未顯著提升任務效率,但可能影響 Agent 的工具選擇與執行路徑。

PS6 · – · Poster Area · 2F Liquan Hall exhibition area

Poster Session 6 (Domestic)

Topics: LLMs & NLPSecurity & Trustworthy AI

Session chairs: Prof. Huai-Sheng Huang (National Taipei University); Chuei-Huei Kung (Fu Jen Catholic University) · 12 papers

  • BoardDP-25

    Fusion Limitations and LLM-Assisted Decision Integration for Conversational Emotion Recognition

    Melvin Liew Lip Wei, Cheng-Tso Chiang, Hao-Ming Hung, Lieu-Hen Chen

    Affiliations: National Chi Nan University, Taiwan

    Keywords: emotion recognition, multimodal fusion, modality complementarity, language models, candidate routing

    Paper #86 · LLMs & NLP

    Abstract

    A weak audio classifier can correct some errors of a stronger text classifier, but selecting audio indiscriminately also causes damage. We study this problem on the Multimodal EmotionLines Dataset (MELD). We compare trained fusion models with a large language model (LLM) judge that reads dialogue text and the two classifiers’ candidate labels. The judge’s relative support selects between those labels, increasing support-weighted F1 (WF1) from 63.76 to 66.46. Combining its full class scores with text instead reaches 68.41 WF1 and increases macro-averaged F1 (MF1) from 46.49 to 55.33. Output composition improves four backbone–text references, whereas shuffled scores and the tested training-time injections do not reproduce those gains. Prediction-change counts distinguish useful corrections from damage. The results support testing decision-level integration in this setting; they remain exploratory because earlier model development consulted the test set.

  • BoardDP-26

    INTEGRATING LARGE LANGUAGE MODELS AND IOT SENSING FOR AN INTELLIGENT DECISION-SUPPORT SYSTEM IN MARINE CORAL RESTORATION

    Shi-Jim Yen, Jia-Huei Wu, Yi-Hao Pai

    Affiliations: National Dong Hwa University, Taiwan

    Keywords: Large Language Model, Retrieval-Augmented Generation, Ocean Big Data, Intelligent Decision-Support System, IoT Sensing

    Paper #72 · LLMs & NLP

    Abstract

    This study integrates a Large Language Model (LLM) with a Retrieval-Augmented Generation (RAG) architecture to build a cloud-based dashboard that combines Internet of Things (IoT) data—including underwater cameras, temperature probes, and driftwood-tracking records—with AI prediction models, providing real-time queries and intelligent question-answering services. This strengthens science communication and cross-domain decision support, complementing ongoing efforts in ecological restoration, material innovation, and education outreach to jointly advance data-driven governance. The study site is the Penghu area, where coral in nearby waters has suffered massive mortality in recent years due to climate change. Our team's coral restoration work in the waters of Penghu can help the region develop tourism, offering new approaches for promoting climate resilience and sustainable ocean governance.

  • BoardDP-27

    HMPA: A Neuro-Symbolic Framework for Natural-Language-Driven, Multi-Emotion Motion Generation on a Low-Cost Humanoid Robot

    Zhi-Zhong Chen, Shih-Hung Wu

    Affiliations: Chaoyang University of Technology, Taiwan

    Keywords: Humanoid Robot, Large Language Model, Neuro-Symbolic AI, Inverse Kinematics, Emotional Motion Generation

    Paper #197 · LLMs & NLP

    Abstract

    Getting humanoid robots to turn natural-language emotional expressions into physical motion is still hard, especially on low-cost hardware that cannot run large end-to-end models. We present HMPA (Hybrid Motor-Proprioception Architecture), a training-free neuro-symbolic pipeline with four layers. A locally hosted large language model (LLM) maps an utterance to a small set of posture parameters (Semantic Motor Imagery); these are interpolated into a trajectory and solved into servo commands by an analytic inverse-kinematics layer (Morphological Negotiation); every frame then passes a rule-based Geometric Safety Valve that enforces joint limits, prevents arm-body self-collision, and checks static stability before the execution driver sends it to the robot. A "Physics of Emotion" prompt tells the LLM how emotions map onto body geometry (height, lean, arm aperture, and timing) instead of asking it for raw joint values. We deployed HMPA on a 16-servo PlayRobot EDE0256 humanoid and generated motions for 40 emotional prompts. A human evaluator rated each recorded video on a three-point scale. The mean semantic-match score was 1.32 and the mean emotional-intensity score was 1.32; only 4 motions clearly matched the intended emotion and 22.5% matched it at least partially. The pipeline produced an executable motion for every prompt on inexpensive hardware, and prototypical emotions such as happiness, sadness, and calm were conveyed clearly, but most emotions were not recognizable from posture alone. These results locate the main bottleneck in expressiveness rather than in feasibility.

  • BoardDP-28

    LLM Proposals and Deterministic Adjudication for Observable Decision Tracing in Quadruped Robots

    Po-Yu Lu, Wei-Feng Tung

    Affiliations: Fu Jen Catholic University, Taiwan

    Keywords: Embodied AI, Quadruped Robot, LLM Safety, Human Robot Interaction, Observability

    Paper #198 · LLMs & NLP

    Abstract

    Large language models (LLMs) make companion robots conversational, but an LLM that can command motion turns a wrong answer into a physical risk. Our quadruped system, built on ROS 2 and a Unitree Go2 Pro with an 8 GB Jetson Orin Nano Super, separates the two: the LLM may propose at most one skill from a fixed allowlist, and a deterministic Interaction Executive alone decides whether any motion is dispatched. Each gate decision is recorded with its reason, and an operator Studio makes these records inspectable. A 26-person exploratory survey, mostly of demonstration viewers, found perceived intelligence higher than perceived safety (3.76 vs 3.40, paired Wilcoxon p = .015), which motivates, but does not test, safety control that is visible as well as enforced.

  • BoardDP-29

    An LLM- and Multi-Source Bibliographic API-Based Automated System for Academic Publication Registration

    Ruei-Chen Wang, Wen-Hung Liao

    Affiliations: National Chengchi University, Taiwan

    Keywords: Publication Management, Bibliographic Metadata, LLM, Chrome Extension, ORCID

    Paper #91 · LLMs & NLP

    Abstract

    Academic publication registration is critical to university administration, yet manual entry is time-consuming and error-prone across 30+ structured fields. This paper presents a non-intrusive automated registration system, implemented as a Chrome Extension, that integrates parallel queries to CrossRef (with DataCite as fallback), OpenAlex, Semantic Scholar, and Unpaywall, together with DBLP-based indexing checks, and applies LLM-based field mapping, using National Chengchi University's publication catalog system as a case study. An ORCID two-stage matching mechanism periodically detects unregistered works and labels them for user confirmation rather than automatic filtering. A three-layer PDF extraction strategy (binary DOI scan, metadata parsing, PDF.js text extraction up to two pages with garbled-text detection) further handles diverse PDF types. Model selection together with two prompt optimization strategies reduced AI field-mapping response time from approximately 26 to 8 seconds, yielding a total end-to-end wait time of about 12 to 16 seconds.

  • BoardDP-30

    通用語言模型 Embedding 至領域特定空間之遷移方法研究 ——以監督式 Embedding 適配於 UK 簽證法規語意分群為例

    陳翔暐 (Shawn Chen), 黃昭義

    Affiliations: 國立雲林科技大學資訊管理系

    Keywords: Domain-specific Embedding, Supervised Embedding Adaptation, Knowledge Graph, Semantic Clustering, Pseudo-labels

    Paper #192 · LLMs & NLP

    Abstract

    General-purpose LLM sentence embeddings lack domain-specific semantic sensitivity. We propose a hybrid strategy that freezes the pretrained encoder and trains a lightweight Dense adaptation network on Ward-clustering pseudo-labels, mapping embeddings into a 64-dimensional domain-specific space. On 400 UK visa regulations, stratified 5-fold cross-validation shows that the test-fold Silhouette rises from 0.15 to 0.51 (MPNet) and from 0.12 to 0.48 (OpenAI), outperforming PCA, UMAP and LDA. On 20 Newsgroups, evaluated against original categories never used in training, the Silhouette of true categories rises from 0.07 to 0.27, while an oracle trained on true categories reaches 0.41, showing that the adaptation network is effective and performance is bounded by pseudo-label quality. Keywords: Domain-specific Embedding, Supervised Embedding Adaptation, Knowledge Graph, Semantic Clustering, Pseudo-labels.

  • BoardDP-31

    台股加權指數波動度預測:新聞情緒特徵之穩健性驗證

    林芳螢, 黃文楨

    Affiliations: 國立高雄科技大學資訊管理所

    Keywords: realized volatility, news sentiment, walkforward validation, paired testing

    Paper #28 · LLMs & NLP

    Abstract

    本研究以台灣加權指數(TAIEX)已實現波動度為預測標的,結合技術面與中文新聞情緒特徵,以技術面(含當日 RV)為基準,並以 walk-forward 逐折配對檢定取代單次切分評估。實證發現新聞情緒對短窗口(次日、次週)波動度具顯著貢獻,長窗口(h=10、22)則各檢定結論不一致;此效應已由Audrino et al. [1]於美股證實,本研究貢獻在於:於散戶成交比重遠高於美股之台灣市場重新驗證,並發現單一衰減設定皆無法穩定重現此效應,以多維半衰期特徵輸入表現較佳。

  • BoardDP-32

    原生語言與翻譯語言作為語言模型訓練資料集之比較-以垃圾簡訊為例

    吳函諺 (Han-Yan Wu), 楊翔丞, 沈宏霖, 劉嘉慶, 黃詠浚

    Affiliations: 亞洲大學資訊工程學系

    Keywords: 垃圾簡訊識別, BERT, 機器翻譯, 資源匱乏語言, 語意分析

    Paper #136 · LLMs & NLP

    Abstract

    本研究探討翻譯語言應用於垃圾簡訊辨識之可行性。以 UCI SMS Spam Collection經前處理後之 5,572 筆英文簡訊為資料來源,透過 Qwen3-8B翻譯為繁體中文,並保留正常訊息(ham)與垃圾訊息(spam)標籤。研究採用 BERT-tiny、Chinese RoBERTa與 XLM-RoBERTa,分別以中英文語料進行微調(fine-tuning),並以四種條件比較跨語言的辨識表現,以Accuracy、Precision、Recall 與 F1-Score 進行評估。實驗結果顯示,各模型於原驗證集皆具有良好表現,其中 XLM-R的垃圾訊息 F1-Score 達 0.95 以上;然而,在不同訊息情境的測試集中,模型效能明顯下降。結果顯示,翻譯既有英文標註語料可作為建立繁體中文訓練資料的可行方法,但辨識效能仍受到模型預訓練背景、翻譯品質及資料分布等因素影響。

  • BoardDP-33

    基於修辭角色與語意一致性片段擾動之法律文本分類解釋研究

    黃柏熏 (Bo-Xun Huang), 杜明道 (Ming-Dao Tu), 吳孟倫 (Meng-Luen Wu)

    Affiliations: 淡江大學資訊工程學系

    Keywords: 可解釋人工智慧, 法律文本分類, 修辭角色, LIME, 語意片段擾動

    Paper #34 · LLMs & NLP

    Abstract

    在法律文本分類領域,部分分類模型存在黑箱問題,使用者難以理解其分類依據。過去多以單字或單句解釋分類模型,雖能標註關鍵內容,但解釋單位較為零碎,可能使法律論述脈絡難以理解。本文提出基於修辭角色與語意一致性片段擾動之法律文本分類解釋,將相同語意詞彙的句子合併,提升解釋效果與可讀性。為提升分類結果的可解釋性,本文提出 SPS-LIME,以修辭角色將相鄰同角色句子合併為語意片段,透過片段擾動與局部代理模型估計各片段對預測的貢獻,再定位片段內的關鍵句子,呈現由論證區塊至句子的雙層解釋,協助使用者回查影響預測的原文內容。SCOTUS 原設定下,片段擾動的 Consistency 為 0.7591、COMP 為 0.0859,均高於詞級與句級擾動;ECtHR 輔助分析亦呈相近趨勢。然而,擾動粒度與文字覆蓋率尚未受控,跨法域角色標註及不同分類器上的適用性仍待驗證。本文提供結構化的局部解釋流程;其歸因反映模型行為,不等同法律推理正確性,亦未經使用者研究驗證理解效果。

  • BoardDP-34

    地表線型判釋、地表溫度異常預測與大型語言模型問答:地熱探勘之 GeoAI 應用與初步成果

    林采蓁1, 鄭錦桐1, 黃瑞賢1, 陳亭佑1, 吳笙緯1, 蘇宗正2, 陳致言2

    Affiliations: 1興創知能股份有限公司 2經濟部地質調查及礦業管理中心

    Keywords: 地熱探勘, 地理空間人工智慧, 語意分割, 梯度提升決策樹, 檢索增強生成

    Paper #46 · LLMs & NLP

    Abstract

    臺灣地熱探勘的早期潛能區篩選仍高度依賴地質師人工判釋。本文整理同一地熱資料整合計畫下的三項 GeoAI 應用:以 U-Net 從數值地形模型反演的 12 項地形因子判釋地表線型(滲透性通道);以 LightGBM 整合 Landsat-8 波段、地形因子與大地電磁法電阻率判釋地表溫度異常區(熱源顯示);以地端部署之大型語言模型結合地質詞彙庫與檢索增強生成建置地質智慧問答模組。前兩項為獨立的概念驗證研究,第三項已納入上線運作之空間資訊整合系統。以大屯火山群標記訓練的線型模型套用至臺東紅葉與花蓮瑞穗兩處變質岩案場,初步產生與地形紋理相符的線型分布,可歸因於模型僅以地形因子為輸入,惟其構造意義仍待地質驗證;線型模型訓練區測試集 F1 為 0.57;溫度異常模型驗證集 AUC 為 0.91、F1 為 0.86,改以 6 公尺光達地形重算地形因子後召回率提高至 0.92,特徵重要度顯示近紅外與紅光波段及淺層電阻率主導判斷。本文並說明三項應用的分工與定位、現階段的驗證缺口與後續發展。

  • BoardDP-35

    Automated Trust Management under LLM Monitoring Uncertainty: Adversarial Risk-Aware Deployment in a Decentralized Multi-Agent Network

    Zong-Ye Li1, Weiyang He2, Chip-Hong Chang2

    Affiliations: 1City University of Hong Kong, Hong Kong 2Nanyang Technological University, Singapore

    Keywords: Decentralized Multi-Agent Systems, Trust Management, LLM Monitoring, Adversarial Robustness

    Paper #169 · Security & Trustworthy AI

    Abstract

    Decentralized multi-agent systems increasingly rely on shared information, yet repeated interactions allow locally plausible actions to accumulate into distributed harm. We propose an automated trust-management framework that converts noisy monitor scores into directed local trust, aggregates them into a global reputation via an EigenTrust-style process, and removes persistently low-reputation agents. Building on this framework, we study an adaptive Red syndicate using shared Q-learning to farm trust, attack benign agents, smear reputations, or boost malicious teammates. We evaluate pretrust, removal threshold population, defense calibration, and Red observation regimes on attacks, Red survival and eradication, and Blue false isolation. In evaluated regimes, including pretrust anchors in threshold computation can prevent removal; excluding them restores operation but reveals an attack-false isolation trade-off. Full manipulation generally increases attacks and Red survival, while post-attack credence has limited aggregate impact despite affecting greedy action preferences. Results characterize adversarial trust dynamics under uncertain monitoring.

  • BoardDP-36

    邁向 AI 情緒建模:句向量嵌入空間中情緒表徵之幾何分析

    黃嘉瑜1, 劉錦燕1, 吳茹婷1, 何浩瑋2, 黃健峯1

    Affiliations: 1國立高雄大學資訊工程學系 2亞馬遜公司

    Keywords: 人工智慧情緒建模, 自然語言處理表徵 學習, 句向量嵌入, 情緒表徵, UMAP

    Paper #31 · LLMs & NLP

    Abstract

    本研究從 NLP representation learning 與 AI emotion modeling 的角度,探討不同認知與語意抽象層次的情緒在 sentence embedding space 中的幾何表徵特性。研究建立包含 12 類情緒、共 1,200 筆英文語句之語料集,並提出 Basic、Reflective 與 Inner 三層操作性情緒架構。實驗採用 all-mpnet-base-v2 與 e5-base-v2 產生句向量,結合 UMAP、silhouette score、centroid cosine distance 與 one-sided permutation test,分析不同情緒層次的群聚、重疊與分離情形。結果顯示,MPNet 與 E5 均呈現一致的 Basic > Reflective > Inner 語意分離度趨勢;其中 Basic 具有較明確的語意邊界,而 Reflective 與 Inner 則呈現較高的重疊與連續性。整體而言,本研究顯示 embedding-space geometry 可提供傳統 emotion classification 指標以外的 representation-level 分析觀點,並可作為後續 hierarchy-aware 或 continuous AI emotion modeling 之研究基礎。

–

IO7 · – · Room A · 2F Lijing Hall A

International Oral Session 7

Topics: Security & Trustworthy AIAI Agents & RAG

Session chair: Prof. Chuang-Chieh Lin (National Taiwan Ocean University) · 4 papers

  1. Bridging Static and Agentic RAG for Taiwanese Historical Question Answering

    Kai-Hsin Chen, Wei-Yu Chen, Xuanjun Chen, Su-Ling Yeh, Jyh-Shing Roger Jang

    Affiliations: National Taiwan University, Taiwan

    Keywords: Retrieval-Augmented Generation, Agentic RAG, Retrieval Orchestration, Historical Question Answering, Answer Selection

    Paper #69 · AI Agents & RAG

    Abstract

    Agentic retrieval-augmented generation (RAG) enables language models to adapt retrieval based on previously retrieved evidence, but it remains unclear whether such adaptive orchestration consistently outperforms well-designed static pipelines. We conduct a controlled comparison of agentic and static RAG for Taiwanese historical question answering, sharing the same generator and hybrid retrieval backend. Despite similar aggregate performance, the two pipelines differ on 70.83% of questions, with their advantages largely canceling out when averaged. An oracle that selects the better response per question improves the composite score by 0.2417 over the better individual pipeline, revealing substantial headroom for question-level selection. We therefore introduce a post-hoc selector that compares the two responses and their cited evidence, significantly outperforming either individual pipeline and recovering 60.34% of the oracle headroom. These results show that aggregate comparisons can obscure meaningful question-level differences between retrieval strategies, suggesting that exploiting their complementarity may be more fruitful than seeking a universally superior pipeline.

  2. SAFE-T: A Safe Agentic Framework for Evidence-Grounded Malware Triage

    Mai Xuan Ha, Le Chanh Thanh Tin, Aquata Theodora Thyme, Po-Wei Harn

    Affiliations: National Central University, Taiwan

    Keywords: malware triage, large language models, agentic systems, sandbox analysis, ATT\&CK, explainable security

    Paper #88 · Security & Trustworthy AI

    Abstract

    Malware sandbox reports are often too verbose for timely analysis, as their commands, filenames, and URLs require manual interpretation and validation by analysts. Because these artifacts originate from an untrusted sample, they cannot be treated as trustworthy evidence without additional validation. This paper presents a Safe Agentic Framework for Evidence-Grounded Triage (SAFE-T), a client–host agent architecture for malware triage. In SAFE-T, a client-side LLM agent selectively retrieves relevant sandbox evidence through bounded read-only tools to produce a concise behavioral summary containing claims, evidence anchors, and ATT\&CK tactic labels. The host then validates the evidence, filters unsupported claims, and verifies the ATT\&CK tactic assignments. Finally, the host summarizes unsupported claims in an explicit abstention message, helping analysts make informed decisions based on the malware sandbox report. We evaluated SAFE-T with six backend models---Gemma4-31B, Gemma4-26B-A4B, GPT-OSS-20B, Qwen3-32B, Qwen3-4B-Instruct, and Mistral-7B---on Paper300, a 300-report cohort based on Avast-CTU reports that combines 209 tactic-annotated reports with 91 adversarial variants. SAFE-T achieved tactic micro-F1 ranged from 0.857--0.893, compared with 0.419--0.658 for passive one-shot and 0.178--0.680 for passive multi-shot prompting on identical evidence catalogs. All published SAFE-T claims had traceable evidence anchors, yielding a grounding rate of 1.000 under the catalog-based metric.

  3. DIAL-ROS: Defense-in-Depth Analysis of Layered ROS 2 Security

    Hassan Abbas1, Chinyang Henry Tseng1, Po-Cheng Chen2, Ke-Cheng Tan1, Javad Ghofrani3

    Affiliations: 1National Taipei University, Taiwan 2Taichung Municipal Dongshan Senior High School, Taiwan 3Hochschule Bonn-Rhein-Sieg, Germany

    Keywords: ROS 2 security, SROS2, robot security, anomaly detection, firmware reverse engineering, defense-in-depth

    Paper #60 · Security & Trustworthy AI

    Abstract

    With ROS 2 increasingly deployed in real-world robotic systems, securing inter-node communication is critical for safe operation. However, existing security research largely focuses on network-layer authentication, leaving open what an authenticated insider or a physically-present attacker can accomplish. This study presents an empirically validated, three-layer security assessment of ROS 2 integrating network authentication evaluation, behavioral anomaly detection, and firmware-layer analysis. At the network layer, SROS2 is evaluated against six attack classes, showing that cryptographic authentication restricts unauthorized access while highlighting the need for behavior-level evaluation among credentialed nodes. Building on this insight, two lightweight statistical anomaly monitors -- a rate-based watchdog and a kinematic-plausibility filter -- are designed for authenticated attackers that SROS2 cannot identify: the watchdog blocks all evaluated flood messages, while the plausibility filter rejects kinematically implausible commands. Together, the two monitors introduce a mean end-to-end latency of 4.87 ms, with a false-positive rate of 0.036% (over 99.96% of legitimate commands preserved). As network and behavioral defenses depend on traffic passing through the ROS graph, the OpenCR controller is reverse-engineered; proof-of-concept exploits assessed through CPU emulation and, where applicable, physical-hardware actuation tests show that the evaluated firmware-layer attacks can bypass network- and ROS-layer defenses. These results demonstrate that network authentication and behavioral anomaly detection provide complementary protection against unauthenticated network attacks and authenticated-insider attacks, while the firmware findings expose an additional protection gap that requires firmware- or hardware-level safeguards.

  4. V-ADAPT: A Verified Adversarial Discovery and Dual-Path Defense Framework for Hardening WAFs Against XSS

    Hua-You Chen1, Po-Cheng Chen2, Chinyang Henry Tseng1

    Affiliations: 1National Taipei University, Taiwan 2Taichung Municipal Dongshan Senior High School, Taiwan

    Keywords: Web Application Firewall, Cross-Site Scripting, Double Deep Q-Network, Large Language Models, Adversarial Testing, Browser-Based Validation, Automated Rule Generation

    Paper #77 · Security & Trustworthy AI

    Abstract

    Web application firewalls (WAFs) remain vulnerable to encoded and context-dependent cross-site scripting (XSS) payloads. We present V-ADAPT, a verified adversarial discovery and protection framework linking attack discovery to defensive repair. AEG-Flow combines large language model (LLM) seed generation, Double Deep Q-Network (DDQN) mutation, and Playwright browser validation. DIS-Flow generates rules from discovered bypasses and inspects original and recursively decoded inputs in parallel. The 100/30/30 DDQN dataset is separate from the defensive evaluation corpora. Across five seeds, final-100-episode goal success reached 93.40% ± 0.55%, and success on the 30-payload DDQN test set was 83.33%. On the 40,978-trial repair corpus, detection increased from 8.26% to 97.39%; all configurations reported an FPR of 0.87% on a separate benign corpus. Full-defense trial-level and payload-level bypass rates were 2.58% and 1.01%, respectively. A further held-out defense evaluation used 32,271 trials derived from 8,438 newly generated source payloads that had not been used to construct the defense. Full defense reduced trial-level bypass from 84.57% to 1.87% and payload-level bypass from 100.00% to 3.98%. Component ablations evaluated generated rules, decoded-only inspection, and dual-path inspection on both corpora. The results demonstrate repair of discovered attacks and provide evidence that defensive effectiveness extends to newly generated payloads withheld from defense construction within the tested environment.

DO7 · – · Room B · 2F Lijing Hall B

Domestic Oral Session 7

Topics: AI in EducationSpeech & AudioAI Agents & RAGSecurity & Trustworthy AI

Session chair: Prof. Mao-Hsiu Hsu (National Formosa University) · 5 papers

  1. 迎向自主性大型語言模型代理與長程規劃時代:歐美比較法論我國 AI 安全規範、風險管控與責任歸責

    陳薇如 (Wei Ju Chen)

    Affiliations: 東海大學法律學系

    Keywords: 人工智慧代理人, 長程規劃, 人工智慧基本法, Agent Safety, Legal LLM Systems

    Paper #160 · AI Agents & RAG

    Abstract

    人工智慧語言模型已由單次問答逐步發展為可拆解目標、調用外部工具並長時間執行任務之自主性大型語言模型代理(Autonomous LLM Agents)。若此類架構進入法律服務,風險不僅在於輸出錯誤,更涉及長程行動鏈中的權限越界、錯誤累積、證據保存與責任歸屬。本文比較歐盟《人工智慧法》(EU AI Act)、美國 NIST 風險管理框架及司法專業責任,並檢視我國2026年《人工智慧基本法》及人工智慧風險分類框架,區分具有拘束力之現行義務與待建構之政策建議。本文提出以自主程度、法律影響與行動持續性為核心的風險判斷,建立分級 Agent Logging、人類實質監督、重大依賴之有限揭露,以及模型提供者、系統整合者、部署者與專業使用者四層治理責任模型。進一步藉由假設法律 AI 書狀案例檢驗各主體之注意義務、因果關係及舉證問題,主張以現行契約與侵權責任為起點,循序將技術對齊轉化為可操作、可追溯的法律合規機制。

  2. 語音對抗淨化之實證稽核:表徵混淆與自適應攻擊的梯度保真度

    劉冠廷 (Guan-Ting Liu), 黃意婷 (Yi-Ting Huang)

    Affiliations: 國立臺灣科技大學電機工程系

    Keywords: 自動語音辨識, 對抗樣本, 生成式淨化, 評估協定, 梯度保真度

    Paper #107 · Security & Trustworthy AI

    Abstract

    基於擴散模型的生成式淨化已廣泛應用於自動語音辨識(ASR)的對抗防禦。然而,現有評估多以固定攻擊集比較防禦前後的錯誤率,即使採用 BPDA/EOT 作為自適應評估依據,仍不足以判定觀察到的穩健性是否可歸因於所提出的模組,也無法確認自適應攻擊是否正確反映實際防禦流程。本研究提出一套五層實證稽核框架,將白盒穩健性評估分為五個依序相依的問題:表徵效果(L1)、組件歸因(L2)、梯度保真度(L3)、端點攻擊有效性(L4),以及不確定性與報告紀律(L5),各層皆對應最低控制與可支撐的主張範圍。其中兩項語音特有控制為共享完整方法前後端的 Mel-聲碼器往返基準(Mel-Vocoder RoundTrip Baseline,MVRB),以及同隨機性配對下量化的梯度方向保真度。以 MelDefense 為診斷案例,稽核結果顯示,捨棄相位的重合成即可解釋大部分表觀穩健性;在固定非自適應攻擊下,完整擴散管線相較 MVRB 未呈現可偵測增益;在受控算子實驗(n=16 句)中,嚴重的梯度方向失真伴隨46–49 pp 的攻擊低估,而高保真度控制則未出現此現象;以縮減可微代理進行最佳化並轉移至完整防禦後,reduced-surrogate adaptive attack 的防禦後 CER 較 waveform straight-through BPDA 高16.13 個百分點(第二個種子於 10 句子集重現相同趨勢),但其梯度一致性無法判定,且 meldomain BPDA 並未更強。本研究的主要貢獻並非提出新的淨化模型,而是建立一套用於檢驗穩健性主張之可歸因性、攻擊有效性與不確定性控制的評估協定。

  3. 基於 LLM 與多代理人架構之國文會考適性學習平台:AI 國文會考備戰系統

    何念慈 (Nien Tzu Ho), 洪詠煜 (Hung Yung Yu), 曾俊諭 (Chun Yu Tseng), 顏士淨 (Shi-Jim Yen)

    Affiliations: 國立東華大學資訊工程學系

    Keywords: AI-Assisted Learning, Chinese Language Education, Adaptive Learning, Large Language Models, Multi-Agent Systems

    Paper #61 · AI in Education

    Abstract

    This study proposes an AI-Assisted Adaptive Learning Platform for Chinese Language Comprehensive Assessment Program (CAP) Preparation, integrating Large Language Models (LLMs) with the CrewAI multi-agent collaborative architecture. The platform addresses common challenges faced by junior high school students during Chinese language examination preparation, including indiscriminate practice, difficulty in identifying learning weaknesses, and the lack of timely feedback on essay writing, by providing intelligent learning assistance. Based on past Chinese language examination questions from the Comprehensive Assessment Program for Junior High School Students, the system analyzes question types, examination trends, and score distributions, and employs multiple AI agents to collaboratively perform mock examination generation, response analysis, weakness diagnosis, personalized learning recommendations, and real-time essay grading. In this study, 13 students preparing for the CAP were invited to participate in a pre-test and post-test experiment. The results showed that the system achieved an 84.6% hit rate in diagnosing weak question types. After using the system, the participants demonstrated an average improvement of 0.77 grade levels, with 61.5% of the participants achieving an improvement in grade level. For essay grading, the mean absolute error (MAE) between the system's scores and the scoring standards of the CAP Center was 0.417 score levels, with all scoring errors controlled within one score level. Furthermore, the option-generation strategy experiment showed that the improved strategy reduced the answer-uniqueness error rate from 42% to 26% and the format error rate from 22% to 10%. The multi-agent architecture reduced the content omission rate from 31.9% to 0% and shortened the average generation time from 692 seconds to 378 seconds. These results demonstrate that the proposed system provides effective capabilities in weakness diagnosis, targeted learning support, and essay grading, indicating its potential for practical application.

  4. 邁向可解釋的智慧教育代理人: 基於測驗理論之大型語言模型認知對齊與異常行為評估

    賴明如1, 劉安萱2, 林裕仁1

    Affiliations: 1國立清華大學數理教育研究所 2元培醫事科技大學

    Keywords: 大型語言模型, 試題反應理論, 逆向學習分析, 認知診斷, 可解釋性人工智慧, 智慧代理人

    Paper #9 · AI in Education

    Abstract

    隨著生成式人工智慧與智慧代理人在教育場域的廣泛應用,確保大型語言模型(LLM)具備與人類相符的認知結構與解題穩定性,已成為關鍵挑戰。本研究提出「逆向學習分析」,將受測對象翻轉為AI模型,運用試題反應理論(IRT-2PL)、Rasch模型與Bloom修訂版認知分類,對多模態大型語言模型(F-MLLM,核心為Gemini)在109–114學年度大學入學考試自然科(物理、化學、生物)共18次測驗之作答表現進行量化評估與認知診斷。研究發現:其一,AI雖於潛在能力(θ)評估上穩定達頂標,但其答題正確與否與人類考生之題目難度(P值)呈統計脫鉤;其二,透過認知層次與科學素養分類,精準定位模型於高階評鑑、複雜情境與多步驟推導之學科盲區;其三,以Outfit MNSQ成功捕捉並量化AI類似「粗心失分」或「幻覺」之異常訊號。本研究為AI答題行為提供具可解釋性(XAI)之量化診斷依據,並為智慧教育代理人之校準與審查提出建議。

  5. 基於自監督聲學表徵與大規模弱監督模型之病理語音辨識效能評估與範式對比

    梁文瀚, 潘欣泰 (Shing-Tai Pan)

    Affiliations: 國立高雄大學資訊工程學系

    Keywords: 病理語音辨識, 自監督學習, 大規模弱監督模型, 構音障礙, 失智症語音

    Paper #20 · Speech & Audio

    Abstract

    本研究旨在解決構音障礙與失智症語音因資料稀缺與聲學變異導致的辨識瓶頸,評估自監督(SSL)與弱監督模型(Whisper)的泛化潛力。方法上,針對 UASpeech 獨立詞(Isolated Words)與 DementiaBank 連續語音資料集,建構 SSL 兩階段微調系統,並與 Whisper 執行零樣本及全參數微調對比。本論文關鍵發現指出兩範式優勢截然不同:於 UASpeech 中,SSL 基準 HuBERT 獲最佳字錯率(WER)46.98%,優於微調後 Whisper-large-v3 的 51.81%;然於 DementiaBank 中,Whisper-large-v3 微調版以 38.61% 展現優勢,大幅超越 SSL 基準的 67.35%。研究貢獻為實證病理語音架構須依任務選型,獨立詞高度依賴底層聲學表徵,連續語音則受益於語言先驗推理。結論指出極低可懂度語音仍為技術挑戰,未來應結合生成式特徵擴增與參數高效微調(PEFT)技術,以提升系統之次群體強健性(Subpopulation Robustness)並落實臨床公平性。

PS7 · – · Poster Area · 2F Liquan Hall exhibition area

Poster Session 7 (Domestic)

Topics: AI in EducationLLMs & NLPAI Agents & RAGOtherAI for Health

Session chairs: Prof. Ya-Tang Yang (National Tsing Hua University); Prof. Min-Te Sun (National Central University) · 10 papers

  • BoardDP-37

    TAIDE醫療衛教RAG問答評估:人工評分與QCI&AI模糊推論

    林鈺耀 (Yu-Yao Lin)1, 陳履恒 (Lieu-Hen Chen)1, 曾俊杰 (Chun-Chieh Tseng)2, 陳心瑋 (Hsin-Wei Chen)2, 李健興 (Chang-Shing Lee)2

    Affiliations: 1國立暨南國際大學資訊工程學系 2國立臺南大學資訊工程學系

    Keywords: 醫療衛教, 檢索增強生成, 可信任人工智慧對話引擎, 人工評估, QCI&AI

    Paper #140 · AI for Health

    Abstract

    本研究結合可信任人工智慧對話引擎(Trustworthy AI Dialogue Engine, TAIDE)大型語言模型(Large Language Model, LLM)的檢索增強生成(Retrieval-Augmented Generation, RAG)回答、人工評分與Quantum Computational Intelligence and Artificial Intelligence(QCI&AI)模糊推論,評估醫療衛教問答。兩位護理學系四年級學生(R1、R2)對741題文字回答的正確性、匹配度、完整性及語言與表達各評分1至5分,共5,928筆評分。四項平均依序為3.89、3.82、3.84、3.56分,語言與表達較低,可優先改善。為評估兩位評分者對相同回答的給分一致程度,本研究採用線性加權Cohen’s κ進行分析。四項評分項目的κ值介於0.218至0.264,顯示評分一致程度仍有提升空間。QCI&AI結合答案語意相似度與人工評分,並計算系統判定的等級與部分輸入評分的平均值所換算的等級相同的比例,R1、R2原為85.8%、89.7%。以基因演算法(Genetic Algorithm, GA)及粒子群最佳化演算法(Particle Swarm Optimization, PSO)調整參數後,R1採GA達94.7%,R2採PSO達97.6%。人工評分結果可供後續重新檢查回答內容;模糊推論結果則反映此批資料的等級匹配情形,尚不能證明模型能獨立判斷回答品質,或在其他題目上有相同表現。

  • BoardDP-38

    混合專家模型之異質專家探索

    洪士程, 李耕維

    Affiliations: 朝陽科技大學資訊工程系

    Keywords: 混合專家模型, 自然語言處理, 大型語言模型, 機器學習

    Paper #5 · LLMs & NLP

    Abstract

    隨著大型語言模型的發展,自然語言處理的效能已顯著提升。然而,其仍面臨高計算成本與高硬體需求等挑戰。混合專家模型(Mixture of Experts, MoE)能在固定計算成本下擴展模型容量,因而有效降低這些需求。MoE 模型相較於具相同計算複雜度的密集模型,具有更高的記憶體需求,進而導致專家冗餘與有效容量低等問題。本研究旨在透過分析訓練期間各專家的激活頻率,判定專家對模型的重要性,並據此調整其參數。激活頻率作為縮放因子,可擴大高頻率專家並縮小低頻率專家,以最佳化模型的資源配置。於 SQuAD資料集上的測試結果顯示,三種BERT模型經雙向縮放後的準確率均略微提升,但部分F1分數有所下降。僅縮減參數的策略則可減少約17%至42%的參數量,同時維持或略微提升BERT模型效能。然而,GPT-2模型在兩種縮放策略下的準確率均略微下降。實驗結果顯示,本方法具有減少模型參數冗餘的潛力,但其效能改善仍因模型架構而異,未來需進一步驗證其資源效率與泛化能力。

  • BoardDP-39

    適性評量之多輪對話式提問生成

    王柏甯, 吳宜鴻

    Affiliations: 中原大學資訊工程系

    Keywords: 適性評量, 大型語言模型, 問題生成, 誘答選項, 診斷式追問

    Paper #49 · LLMs & NLP

    Abstract

    本研究提出一套以結構化 Prompt 為核心的多輪適性評量題目生成流程。系統依教材建立核心概念與知識點,生成含診斷式誘答的起始題目(BQ),並將各誘答對應至可能錯誤理解與追問策略,再據此產生後續追問題(FQ)。題目於施測前經生成、審查與重新生成流程後納入題庫。期末施測共 124 位學生、985 筆有效 BQ 題次,初答正確率為 61.52%,追問與重答後最終正確率為 73.50%;初答錯誤題次中,31.13% 於追問後改答正確。結果顯示,本流程可依學生實際錯誤選項提供差異化追問;由於本次未設無 FQ 控制組,相關結果僅作描述性解讀。

  • BoardDP-40

    A Source-Aware Agentic RAG Architecture for Study-Abroad Admissions Advising: Design and Evaluation

    Po-Yuan Huang, Ting-Han Wu, Kai-Ting Chen

    Affiliations: National Chengchi University, Taiwan

    Keywords: source-aware agentic RAG, study-abroad advising, text-to-SQL, hybrid retrieval, evidence verification

    Paper #128 · AI Agents & RAG

    Abstract

    Study-abroad advising draws on official requirements, community-reported experiences, and faculty research information, which differ in authority and structure. Retrieval-augmented generation ranks evidence by relevance, yet a relevant community report about a GPA threshold is not an official requirement. Our insight is that source authority should shape retrieval routing, not be considered only after retrieval. We present a source-aware agentic RAG system built with LangGraph that routes official requirements to text-to-SQL, experience questions to retrieval over community reports, and faculty questions to query-time search; a bounded evidence check allows one retry and otherwise abstains. On 34 official-data queries at five universities, the system answered all correctly; on 60 threshold questions for 20 universities without indexed official data, it abstained on all and gave no unsupported numerical threshold, whereas a ReAct baseline with different prompting and answer model gave one for 55%. An ablation attributes this mainly to intent-based routing rather than the evidence check. The adversarial set does not test over-refusal or source conflicts.

  • BoardDP-41

    具來源追溯與人工檢核之RAG數位證物對話線索整理流程

    陳勇行 (Yung-Sing Chen)1,2, 鄧皓允3

    Affiliations: 1臺北市政府警察局刑事警察大隊科技犯罪偵查隊 2國立中央大學資訊管理學系 3內政部警政署刑事警察局

    Keywords: 檢索增強生成, 數位證物, 來源追溯, 人工檢核, 負責任人工智慧

    Paper #8 · AI Agents & RAG

    Abstract

    刑事案件的對話紀錄數量龐大且脈絡分散,又常夾雜代稱與錯字。本文提出以檢索增強生成(RAG)整理線索的流程。流程以單則訊息作為引用與稽核單位,以同一聊天室的連續訊息作為檢索脈絡,再透過主張與證據對照及人工檢核限制模型推論。原型已在一件案件的數位證物工作複本上完成功能展示,並以去識別化的真實對話進行前導測試。量化評估使用220則合成對話與32道標註題目,比較BM25、BGE-M3向量與兩者融合的檢索,並以qwen3:8b評估受限生成。三種檢索方法的Top-5關鍵訊息找回率為0.833、0.667與0.792,代稱題為0.250至0.500。生成結果沒有超出取回範圍的引用,應拒答題的拒答率為0.875至1.000,三次重複輸出完全相同。代稱與暗語查詢仍需搭配偵查人員的經驗判讀。

  • BoardDP-42

    應用Rapidminer和Optuna預測學生的學業表現

    洪士程, 李常遠

    Affiliations: 朝陽科技大學資訊工程系

    Keywords: 學生學業表現, 決策樹, 超參數優化, RapidMiner, Optuna

    Paper #6 · AI in Education

    Abstract

    預測學生學業表現是教育資料探勘的重要目標之一,可協助及早辨識可能需要額外支援的學生,並提供資料驅動的教育決策資訊。本研究應用資料探勘技術預測學生學業表現,並辨識與分類結果具有較高關聯性的特徵。研究以學生行為與學業資料為基礎,在 RapidMiner 中建立決策樹模型,並使用 Optuna 進行超參數優化。資料集被劃分為相互獨立的訓練集與測試集,超參數優化僅於訓練集上透過 10 折交叉驗證進行。優化後模型在獨立測試集上的準確率為 68.42%,相較於 RapidMiner 預設模型的 65.26%,提升 3.16 個百分點。特徵重要性分析顯示,Visited Resources 與 Discussion 為最具影響力的預測特徵,其次為 Announcements View 與 Raised Hands。結果顯示,超參數優化可使決策樹分類效能獲得小幅改善,並顯示學生使用學習資源與課堂互動等行為特徵對學業表現預測具有重要性。

  • BoardDP-43

    基於強弱人工智慧決策差異驅動之適應式五子棋教學系統

    蘇奇威1, 薛筑軒2, 簡暐哲1

    Affiliations: 1國立東華大學 2北陸先端科學技術大學院大學

    Keywords: 五子棋, 蒙地卡羅樹搜尋, 極小化極大演算法, 適應式教學, 大型語言模型

    Paper #134 · AI in Education

    Abstract

    本研究提出一套以強弱人工智慧決策差異驅動的適應式五子棋教學系統。強AI採用Policy-Value Network搭配Monte Carlo Tree Search(MCTS),弱AI採用深度3之Alpha-Beta Minimax與棋型評估。兩者的走法會以400次搜尋預算的MCTS統一重新評估並計算分數差距;若分數損失超過門檻且玩家在該局面下的走法不屬於可接受集合時會觸發提示;此時系統會將程式辨識的棋型和強AI的推薦座標等盤面資訊交由大型語言模型產生說明。實驗驗證則由20位參與者完成3個主題共10題的問卷,主題分別為提示時機、教學內容與整體知覺效用,平均分數分別為4.25、3.90與4.07,十題總平均為4.06。結果顯示參與者肯定系統的提示時機、教學內容與整體教學價值。

  • BoardDP-44

    整合程式評測與程式碼分析智慧出題之VS Code擴充套件設計與實作

    黃筱婷, 白文君, 劉子安, 吳宜鴻

    Affiliations: 中原大學資訊工程學系

    Keywords: 程式評測, 程式碼分析, VS Code Extension, 抽象語法樹, 智慧出題

    Paper #170 · AI in Education

    Abstract

    隨著生成式人工智慧與大型語言模型快速發展,如何確認學生是否理解生成之程式碼,成為程式設計教學的重要議題。為此,本研究開發整合於 Visual Studio Code(VS Code)的 IntriCode,將既有程式評測與程式理解測驗整合於單一開發環境。系統包含程式碼評測與智慧出題兩大模組,前者提供程式提交、執行與結果回傳,後者利用 Tree-sitter 建立抽象語法樹(AST),進行函式特徵分析與篩選,並透過機器學習預測三種題型的適合程度,再結合大型語言模型生成程式理解題目。此外,本研究透過實際課堂問卷評量,蒐集學生對系統操作、程式檢測及智慧出題功能的使用回饋,作為系統評估與後續改進之依據。

  • BoardDP-45

    以效標關聯效度錨定之無人機操作員複合信任評分:設計科學研究 (A Validity-Anchored Composite Trust Score for Commercial UAS Operators: A Design Science Study)

    黃政傑1, 邱恩芹 (Chiu En Ching)2, 林佑彬3, 彭進德1

    Affiliations: 1偲愷動力股份有限公司 2元智大學國企系 3財團法人資訊工業策進會

    Keywords: 無人機操作員, 無人機飛手, 信任評分, 設計科學研究, 效標關聯效度, 非補償性計分

    Paper #99 · Other

    Abstract

    隨著商用無人機應用逐步普及,帶動無人機操作員人力市場的發展,然而當前市場極度缺乏可信賴的能力指標:各國發照制度著重於法規知識與基本操作能力,職業所需的實務飛行操作水準往往未能完整呈現(美國 Part 107 航空人員檢定標準之技能與風險管理欄位全部標示為 [Reserved] 與 [Not Applicable]),以致市場僅能以總飛行時數作為判別指標。本研究採設計科學研究(DSR)典範,建構並評估一套六構面、總分 1,000 分之無人機操作員操作水平評分成品,其核心設計主張為:複合分數之權重應可追溯至既有的效標關聯效度證據,而非由設計者直覺設定。權重依 Sackett 等(2022)之修正效度估計推導,並疊加時間衰減、部分信度與非補償性閘門三項機制。四項模擬顯示:臨界交互相關 r* = 0.548 而模擬所得實際平均相關 r = 0.398,故六構面複合架構成立;權重 ±20% 擾動下等級改變率 P95 僅 0.50%;非補償性閘門亦阻止 9.1% 高風險操作員取得 B 級以上評等

  • BoardDP-46

    基於題項關聯表徵與注意力導向資料擴增之親密暴力問卷深度分群

    練姸伶 (Yen-Ling Lien)1, 李翊嘉 (I-Chia Li)1, 曾秀雲 (Hsiu Yun Tseng)2, 王雅書 (Ya-Shu Wang)3, 凃瀞珽 (Ching-Ting Tu)1

    Affiliations: 1國立中興大學資料科學與資訊計算研究所 2實踐大學社會工作學系 3國立中興大學應用數學系

    Keywords: 親密暴力問卷, 深度分群, 題項關 聯矩陣, Grad-CAM, 資料擴增

    Paper #157 · Other

    Abstract

    親密暴力問卷的無監督分析面臨題項依存關係、缺乏真實群體標籤與小樣本等問題。本文提出結合題項關聯表徵、深度分群與注意力導向資料擴增的架構:先將 30題、0–4分的問卷轉換為三種30×30題項關聯矩陣,再以Encoder–Decoder建立低維表徵,並結合KL散度、群內一致性與群間差異性損失進行分群;最後以分群結果訓練分類器,利用 Grad-CAM 找出重要的題項關聯區域並產生擴增資料。實驗使用 180 份訓練資料、2,831 份線上測試資料與 331份由專業輔導員協助填寫的測試資料。結果顯示,注意力導向資料擴增在多數設定下提升平均 Cronbach’s alpha,但效果仍受題項關聯表示與資料分布影響。

High school

High School Oral Sessions

Papers from the High School Student Session on Artificial Intelligence and Its Applications are presented in two sessions on Day 2 in Room C, in the order listed below. Times are Asia/Taipei (UTC+8). For the call for papers and presentation rules, see the High School Session page.

HS 1 · Day 2, Sat, Nov 21, 2026 · – · Room C · 2F Liquan Hall C1

High School Oral Session 1: Long Papers

Session organizer: Prof. Jen-Wei Huang, National Cheng Kung University · 4 papers · presented in the order listed

  1. 1

    Evaluating Style Transfer for Ulcerative Colitis Severity Classification

    Jasper Wu1, Furen Xiao2

    Affiliations: 1Taipei American School 2National Taiwan University College of Medicine

    Submission HS-1

  2. 2

    Generative Agents City Simulation

    Daniel Tsen1,2

    Affiliations: 1Li Po Chun United World College, Hong Kong SAR 2MIT City Science Lab @ Taipei Tech, Taipei, Taiwan

    Submission HS-17

  3. 3

    Evaluating Audio-Visual Atmosphere Alignment without Paired Ground-Truth Labels

    Yu-Lin Wu1, Yen-Ting Lin2

    Affiliations: 1National Changhua Senior High School 2Department of Computer Science and Artificial Intelligence, National Pingtung University

    Submission HS-19

  4. 4

    Sensor-Grounded Verification of UAV Fault Claims with Local Language Models

    Wei-Chun Zeng, Bo-Wen Hsieh

    Affiliations: Taipei Digital Experimental High School

    Submission HS-20

HS 2 · Day 2, Sat, Nov 21, 2026 · – · Room C · 2F Liquan Hall C1

High School Oral Session 2: Short Papers

Session organizer: Prof. Jen-Wei Huang, National Cheng Kung University · 6 papers · presented in the order listed

  1. 1

    Model Tier, Tool Access, and Cost in LLM-Based Cryptographic Algorithm Identification: A 2 × 3 Controlled Experiment

    Zi-Cheng Lin

    Affiliations: Taichung Municipal Taichung Industrial High School

    Submission HS-5

  2. 2

    Which Direction Matters? A Paired Single-Path Ablation of Embedding Re-injection in Post-LN Transformers

    Jue-Hao Chen

    Affiliations: Taipei Municipal Daan Vocational High School

    Submission HS-11

  3. 3

    How Much of Speech Recognition Must Be Learned? A Parameter-Free Analysis of Lexical Decoding

    Po-Ting Lin

    Affiliations: National Tainan Chia-Chi Senior High School

    Submission HS-13

  4. 4

    Disaster Hub: An Open-Data-Driven RAG-GIS Decision Support System for Disaster Response with Scenario Stress Testing

    Yi-Le Liu1, Chih-Hung Chung2

    Affiliations: 1Tamkang Senior High School (TKSH) 2Department of Educational Technology, Tamkang University

    Submission HS-14

  5. 5

    Evaluating Cost-Sensitive Learning Strategies for Large Wildfire Classification Under Severe Class Imbalance

    Andrea Feng

    Affiliations: Hsinchu County American School

    Submission HS-15

  6. 6

    Design and Analysis of a Model-Inversion-Inspired CTF Challenge

    Yu-Chen Huang

    Affiliations: National Changhua Girls' Senior High School

    Submission HS-18

Partner events

Partner Events

The finals of the NAPAI Agentic AI Innovation Competition for Campus Applications are a partner event held at the conference venue. Times are Asia/Taipei (UTC+8).

NAPAI · Day 2, Sat, Nov 21, 2026 · – · Room D · 7F Summit Hall

NAPAI Agentic AI Innovation Competition for Campus Applications · Finals & Award Ceremony

Partner event · Organized by the NAPAI Project Office (National Agentic & Physical AI Initiative) · 16 finalist teams (9 minutes each: 5-minute demo + 4-minute Q&A)

The competition rules, finals submission requirements and latest announcements are published on the official NAPAI competition website (external site, opens in a new tab).

  1. Participant and jury registration

    On-site registration, projection equipment and network testing

  2. Opening remarks and jury introduction

    Opening by Project Investigator Prof. Chia-Hui Chang; introduction of Co-Investigator Prof. Min-Yuh Day and the jury

  3. Demo evaluation, first half: Teams 1–7

    1. thon · 2. 火矩方舟 · 3. Loopy · 4. 補助同行 · 5. 關東組 · 6. AgentLab · 7. 牛排群組

  4. Tea break

    Conference refreshment area

  5. Demo evaluation, second half: Teams 8–16

    8. 五夠補 · 9. 讀伴 · 10. 就是藥對決 · 11. NOVA5|新星 5 號 · 12. 你愛我對不隊 · 13. INMU KING · 14. FEAF · 15. 20 分鐘燒完 token · 16. PINWISE

  6. Intermission and score aggregation

    Jury score calculation, deliberation and final ranking confirmation

  7. Award ceremony

    Jury summary feedback, awards for both tracks, and group photo

Official NAPAI competition website (external site, opens in a new tab)

Poster presentations

Poster Presentation Guidelines

Poster size and orientation

  • Recommended size: A0 portrait (84.1 cm wide × 118.9 cm high).
  • Posters must not exceed A0 dimensions. Smaller formats, such as A1, are acceptable.
  • Portrait orientation is required. Landscape posters are not permitted.

Poster content

Posters should clearly include the paper title, authors, affiliations, motivation and objectives, methods, results, and conclusions.

Authors are encouraged to use clear figures, concise text, and fonts that are easily readable from approximately 1–2 meters away.

Printing and display

  • Presenters are responsible for printing and bringing their posters to the conference venue.
  • Each accepted poster paper will be assigned a display space. Poster boards and mounting materials will be provided.
  • Put up your poster during the break before your session, stay at your board for the whole session to present your work and answer questions, and take it down right after it ends.
  • When the poster session chair(s) visit your board, give a 3-minute presentation of your work.

Poster session times are in the poster session schedule below, and board numbers are listed under Paper Sessions.

Authors presenting remotely by prior approval: see the Registration FAQ.

Poster session schedule

SessionDay and time (Asia/Taipei)TrackBoards
Poster Session 1 Day 1 · Fri, Nov 20, 10:40–12:00 International IP-01 – IP-08 (8 papers)
Poster Session 2 Day 1 · Fri, Nov 20, 13:00–14:20 Domestic DP-01 – DP-12 (12 papers)
Poster Session 3 Day 1 · Fri, Nov 20, 14:40–16:00 International IP-11 – IP-19 (9 papers)
Poster Session 4 Day 2 · Sat, Nov 21, 10:10–11:00 Domestic DP-13 – DP-24 (12 papers)
Poster Session 5 Day 2 · Sat, Nov 21, 11:10–12:00 International IP-21 – IP-30 (10 papers)
Poster Session 6 Day 2 · Sat, Nov 21, 13:00–14:20 Domestic DP-25 – DP-36 (12 papers)
Poster Session 7 Day 2 · Sat, Nov 21, 14:40–15:30 Domestic DP-37 – DP-46 (10 papers)

All poster sessions are in the Poster Area (2F Liquan Hall exhibition area). Each poster session has its own boards: put up your poster during the break before your session, stay at your board for the whole session to present your work and answer questions, and take it down right after the session ends. When the poster session chair(s) visit your board, give a 3-minute presentation of your work. Find your board number next to your paper under Paper Sessions.

Awards

TAAI 2026 Awards

Paper Awards

Announced at the Welcome Banquet: Day 1, Friday, November 20, 2026, –, 1F Lichi Hall (麗池廳).

TAAI 2026 Best Paper Awards

For outstanding papers accepted to TAAI 2026.

TAAI 2026 Best Student Paper Awards

For outstanding student papers.

TAAI 2026 Best Industry Paper Awards

For outstanding industry papers.

Presentation Awards

Presented at the Closing Ceremony & Awards: Day 2, Saturday, November 21, 2026, –, Plenary Hall (5F Lishan Hall).

TAAI 2026 Best Oral Paper Presentation Awards

For outstanding presentations in the oral paper sessions, judged by the session chairs and the awards committee on the content, the clarity of the presentation, and the answers to questions.

TAAI 2026 Best Poster Paper Presentation Awards

For outstanding presentations in the poster paper sessions, judged by the session chair(s) and the awards committee on the content, the clarity, and the answers to questions in each poster’s 3-minute presentation.

TAAI 2026 Master's and Doctoral Thesis Awards

Award winners present on Day 1, Friday, November 20, 2026, –, Room D (7F Summit Hall).

Thesis · Day 1 Friday, November 20, 2026 · – · Room D · 7F Summit Hall

TAAI Thesis Award Presentations

TAAI 碩博士論文獎口頭報告

Session chair: Prof. Chia-Ru Chung (National Central University)

Winners of the TAAI Master's and Doctoral Thesis Awards (ROC year 115) · 8 theses · listed by award. Selected in two review rounds, with each thesis read by at least three reviewers. Award committee chair: Prof. Chih-Chieh Hung. See the TAAI announcement (in Chinese) (external site, opens in a new tab).

  1. 1

    Doctoral Thesis Award

    學習優化策略:多臂老虎機演算法與用於黑箱決策問題的強化學習方法

    Yu-Heng Hung (洪鈺恆) · Advisor: Prof. Ping-Chun Hsieh (謝秉均)

    Affiliations: Institute of Computer Science and Engineering, National Yang Ming Chiao Tung University

  2. 2

    Doctoral Thesis Honorable Mention

    通用目標追蹤之人類層級感知能力再探

    Shih-Fang Chen (陳世芳) · Advisors: Prof. Yen-Yu Lin (林彥宇) and Dr. Jun-Cheng Chen (陳駿丞, Research Center for Information Technology Innovation, Academia Sinica)

    Affiliations: Institute of Computer Science and Engineering, National Yang Ming Chiao Tung University

  3. 3

    Doctoral Thesis Honorable Mention

    面向人本導向人工智慧之視覺智慧研究

    Ling Lo (羅婈) · Advisor: Prof. Wen-Huang Cheng (鄭文皇)

    Affiliations: Institute of Electronics, National Yang Ming Chiao Tung University

  4. 4

    Master's Thesis Award

    用後悔值引導AlphaZero提升學習效率

    Yun-Jui Tsai (蔡昀叡) · Advisors: Prof. I-Chen Wu (吳毅成) and Dr. Ti-Rong Wu (吳廸融, Institute of Information Science, Academia Sinica)

    Affiliations: Institute of Computer Science and Engineering, National Yang Ming Chiao Tung University

  5. 5

    Master's Thesis Award

    無獎勵表徵到偏好學習:重新思考離線偏好強化學習

    Jun-Jie Yang (楊竣傑) · Advisor: Prof. Ping-Chun Hsieh (謝秉均)

    Affiliations: Institute of Computer Science and Engineering, National Yang Ming Chiao Tung University

  6. 6

    Master's Thesis Honorable Mention

    適應性雙重知識引導的學習輔助演化最佳化方法

    Yu-Tang Hsu (許育棠) · Advisor: Prof. Chuan-Kang Ting (丁川康)

    Affiliations: Department of Computer Science, National Tsing Hua University

  7. 7

    Master's Thesis Honorable Mention

    整合語音辨識與合成之雙向流匹配模型

    Chih-Chuan Yeh (葉志銓) · Advisor: Prof. Jen-Tzung Chien (簡仁宗)

    Affiliations: Department of Electrical and Computer Engineering, National Yang Ming Chiao Tung University

  8. 8

    Master's Thesis Honorable Mention

    基於跨空間去噪之快速零樣本三維視覺幻象生成

    Siang-Ling Zhang (張欀齡) · Advisor: Prof. Yu-Lun Liu (劉育綸)

    Affiliations: Institute of Computer Science and Engineering, National Yang Ming Chiao Tung University

Rooms

Room Guide

Room photos: The Great Roots Forestry Spa Resort (external site, opens in a new tab), used with credit.

FAQ

Program FAQ

Venue & travel

Q1. Is the program final?

Yes. If anything changes, this page will have the latest information.

Q2. How do I find my paper?

Go to Paper Sessions and search by paper ID (for example 148), title, author, or keyword. Use Search in to search only one field, and the Topic, Day, and session-type filters to narrow the list. Each paper has its own link (for example program.html#paper-148) that you can share with co-authors.

Q3. Where do I find my paper ID?

Your paper ID is your OpenReview submission number, shown on your paper in OpenReview (external site, opens in a new tab) and next to each paper under Paper Sessions (for example, Paper #148). Please include it in every email about your paper.

Q4. Something about my paper is wrong, or I cannot find it. What should I do?

Email taai2026org@gmail.com with your paper ID by November 9, 2026. Please check your paper title, author names, session, and presentation time (poster papers: also your board number).

Q5. Can I change my session or presentation time? I have a scheduling conflict.

Sessions were arranged so that no author has two papers presented at the same time, and the presentation type (oral or poster) is assigned by the Organizing Committee. If you still have a conflict, email taai2026org@gmail.com with your paper IDs and the reason by November 9, 2026.

Q6. Which time zone are the times in?

All times on this page are Asia/Taipei time (UTC+8).

Q7. I have more than one accepted paper. How does that work in the program?

Each paper has its own slot; search Paper Sessions with Search in: Author to see all of yours. Each accepted paper also needs its own registration, with at least one author presenting it on-site. See Registration FAQ Q4.

Q8. What is the Program & Abstract Book?

It compiles the conference program with paper titles, authors, affiliations, abstracts, and session information. It is a record of the conference presentations, not the formal proceedings. See Call for Papers FAQ Q33.

Q9. Will there be a printed conference handbook?

No. To support sustainability, TAAI 2026 does not print a handbook or a Program & Abstract Book; both are provided as digital PDFs only. You can download the Conference Handbook above. This page always has the latest program, including any changes made after the handbook was published.

Q10. Why don’t I see the High School, Special Session, or Industrial Track papers in Paper Sessions?

Paper Sessions lists the International and Domestic Track oral and poster papers. The other sessions in the timetable, such as the High School Oral Sessions (Day 2, Room C), Special Sessions, Industrial Tracks, and the TAAI Thesis Award presentations (winners listed under Awards), are organized separately; see the timetable for their times and rooms.

Q11. How long is an oral presentation?

About 10 minutes per paper, including Q&A. Papers are presented in the order listed in each session, and each paper shows its start time under Paper Sessions.

Q12. What should I do before my oral session?

Check your session, room, and start time under Paper Sessions, and please be in the room before the session begins. Papers are presented in the order listed, so stay for the whole session if you can. Session chairs are listed with each session; see Q22.

Q13. What equipment is available for oral presentations? How do I load my slides?

Each session room has a projector and a presentation laptop (Windows, with PowerPoint and a PDF reader), connected by HDMI. Please prepare 16:9 slides as PDF or PPTX and copy them to the room laptop from a USB drive during the break before your session; a PDF copy is a good backup. If you use your own laptop, bring an adapter for HDMI (for example, USB-C to HDMI) and test it before the session starts.

Q14. Which language should I present in?

International sessions are presented in English. Domestic sessions may be presented in Chinese or English; English slides are encouraged so that international attendees can follow.

Q15. How was my paper assigned to an oral or poster session?

The Organizing Committee assigns the presentation type based on review outcomes and program scheduling. Oral and poster are different paper types, not different review standards: International Track oral papers are published as Full Papers (12–15 pages) and poster papers as Short Papers (6–11 pages), in the same Springer CCIS post-proceedings. Domestic Extended Abstracts are, in principle, presented as posters. See Call for Papers FAQ Q19 and Q29.

Q16. What do I need to know for a poster presentation?

Each poster paper has a board number: IP- for international and DP- for domestic papers, shown next to the paper under Paper Sessions. Posters should be A0 portrait (A1 is also acceptable; landscape is not). Please print and bring your own poster; boards and mounting materials are provided. Put it up during the break before your session, stay at your board for the whole session to present your work and answer questions, and take it down right after it ends (see Q17). When the poster session chair(s) visit your board, give a 3-minute presentation of your work. See the Poster Presentation Guidelines.

Q17. When do I put up and take down my poster?

Each poster session has its own boards, labeled with board numbers (IP-/DP-). Put up your poster at your board during the break before your session and take it down right after the session ends, so the board is ready for the next session. Mounting materials are provided; the board size and any setup details will be posted at the poster area.

Q18. I chose Presentation Only (NOT-to-Publish). Is my paper still in the program?

Yes. Presentation Only means the paper is not published in the proceedings; it does not change your oral or poster assignment or cancel your presentation slot. At least one author must still register and present on-site, and the title, authors, and abstract may still appear in program materials. See Camera-Ready FAQ Q7 and Call for Papers FAQ Q12.

Q19. Can a student or another co-author present my paper?

Yes. The presenting-author registration must be held by the author who will present the paper on-site, so the co-author who presents registers in their own name; you may pay the fee for them. See Registration FAQ Q19.

Q20. Can I present remotely?

Only with prior approval. On-site presentation is the default; authors who cannot travel for a justified reason may apply by November 10, 2026, 23:59 AoE. See Registration FAQ Q24 for how to apply and the video requirements.

Q21. What happens if no author presents the paper?

Every accepted paper needs at least one registered author who presents it on-site (or remotely with prior approval). A paper that is not presented may be removed from the program and cannot be published. If no author can attend, email taai2026org@gmail.com as early as possible. See Camera-Ready FAQ Q24 and Registration FAQ Q24.

Q22. Who chairs each session?

Session chairs are listed under each session in the timetable, and paper session chairs are also listed with each session under Paper Sessions. Chairs for the remaining sessions will be added once confirmed.

Q23. I am a session chair. What should I do?

Oral session chairs: please arrive at your room about 10 minutes before the session, check that the presenters are there and their slides are loaded, introduce each speaker, keep each paper to its slot (about 8 minutes for the talk and 2 minutes for Q&A), and moderate questions.

Poster session chairs: please come to the Poster Area before the session, and during the session visit each board to hear each poster’s 3-minute presentation and moderate questions.

Session chairs also judge the presentation awards with the awards committee (see Q32). After the session, report any paper that is not presented to the registration desk. Presenters: please introduce yourself to your session chair before the session starts.

Q24. When and where are the keynote speeches?

All keynotes are in the Plenary Hall (5F Lishan Hall): Keynote I on Day 1 at 09:30, Keynote II on Day 1 at 16:10, Keynote III on Day 2 at 09:00, and Keynote IV on Day 2 at 15:40. The International Panel with the keynote speakers follows on Day 1 at 17:00. See Keynote Speeches and the International Panel Discussion.

Q25. Can I attend sessions other than my own?

Yes. Every registration type includes both conference days, keynotes, and all sessions, so you are welcome to attend any session in the program.

Q26. Does a presenting author need to register?

Yes. Every accepted paper needs at least one presenting author who has completed registration and payment by the camera-ready deadline, October 31, 2026, 23:59 AoE (High School Session: November 8, 2026, 23:59 AoE). Otherwise the paper may be removed from the program. See the Registration FAQ.

Q27. What does registration include? Is the banquet included?

All registration types include both conference days, keynotes and sessions, coffee/tea breaks, lunches, the conference kit, and admission to the Opening & Closing Ceremony. The Conference Banquet is included for Full Registrants and Presenting Authors; Student and Accompanying Person registrations can add a banquet ticket (NT$ 2,000). Accommodation and hot-spring access are not included (see Registration FAQ Q28). See Registration FAQ Q11.

Q28. When is the registration desk open? Can I register on-site?

Registration is open 08:00–17:00 on both conference days (see the timetable), at the registration desk in the 5F Lishan Hall open courtyard. On-site registration is available on November 20–21 at on-site rates and accepts cash (NT$) and credit cards (Visa, Mastercard, JCB) only. Presenting authors must register earlier. See Registration FAQ Q23.

Q29. Can I get a certificate of presentation or attendance?

Yes. Certificates of presentation (for presenting authors) and of attendance are available on request: email taai2026org@gmail.com with your full name and, for a presentation certificate, your paper ID.

Q30. I need a visa. Can I get an invitation letter?

Yes. Email taai2026org@gmail.com with your full name as in your passport, nationality, affiliation, paper ID and title, and planned travel dates, and request it early. See Registration FAQ Q25.

Q31. When are the awards announced?

The Best Paper, Best Student Paper, and Best Industry Paper Awards are announced at the Welcome Banquet (Day 1, Friday, November 20, 18:00–20:00). The Best Oral and Best Poster Paper Presentation Awards are presented at the Closing Ceremony & Awards (Day 2, Saturday, November 21, 16:30–17:00). The Welcome Banquet is in 1F Lichi Hall (麗池廳), and the Closing Ceremony & Awards in the Plenary Hall (5F Lishan Hall). See TAAI 2026 Awards.

Q32. How are the presentation awards judged?

The Best Oral and Best Poster Paper Presentation Awards are judged during the sessions by the session chairs and the awards committee, based on the content, the clarity of the presentation, and the answers to questions (for posters, the 3-minute presentation given at the board). To be considered, the paper must be presented in person at its scheduled session. Winners are announced at the Closing Ceremony & Awards, so candidates are encouraged to attend.

Q33. Where are the session rooms?

All sessions are at The Great Roots Forestry Spa Resort: the Plenary Hall is 5F Lishan Hall, Rooms A and B are 2F Lijing Hall A and B, Room C is 2F Liquan Hall C1, Room D is 7F Summit Hall, and the Poster Area is the exhibition area of 2F Liquan Hall. See the Room Guide.

Q34. Where are lunch and the coffee breaks? Is there Wi-Fi?

Lunch and coffee breaks are at the times shown in the timetable. Coffee breaks and the Day 1 lunch are in the 5F Lishan Hall exhibition area, and the Day 2 luncheon is in 1F Lichi Hall (麗池廳); the Wi-Fi details will be posted at the venue and are available at the registration desk.

Q35. How do I get to the venue?

Free conference shuttles run from Banqiao HSR Station (about 50 minutes) and Taipei University Station (MRT Sanying Line, about 25 minutes). See Getting here and the shuttle timetable.

Q36. Where can I stay?

See Where to stay for accommodation options. Rooms are booked separately from registration.

Q37. Where is the Computer Game Tournament?

It is held online. Rules and the latest information are on the Computer Game Tournament website (external site, opens in a new tab).

Q38. Who do I contact about the program?

Email the organizing team at taai2026org@gmail.com, and include your paper ID if your question is about a paper.

More questions: see the Registration FAQ and the Camera-Ready FAQ.